"summary":"FastAPI is a modern, fast (high-performance), web framework for building APIs with Python based on standard Python type hints.",
"learning_value":"fastapi 适合作为 Web 框架 的学习样本,可以帮助理解 Python 生态下的核心能力、工程组织方式以及真实项目的功能拆分。",
"prerequisites":[
"Python 基础",
"HTTP 与 REST 基础",
"后端服务开发基础"
],
"knowledge_points":[
{
"name":"高性能",
"category":"核心能力",
"description":"仓库强调这一能力,重点在于:Very high performance, on par with NodeJS and Go (thanks to Starlette and Pydantic). One of the fastest Python frameworks available",
"importance":"高",
"evidence":"README main_features: Fast: Very high performance, on par with NodeJS and Go (thanks to Starlette and Pydantic). One of the fastest Python frameworks available"
},
{
"name":"开发效率",
"category":"核心能力",
"description":"仓库强调这一能力,重点在于:Increase the speed to develop features by about 200% to 300%",
"importance":"高",
"evidence":"README main_features: Fast to code: Increase the speed to develop features by about 200% to 300%"
},
{
"name":"降低错误率",
"category":"核心能力",
"description":"仓库强调这一能力,重点在于:Reduce about 40% of human (developer) induced errors",
"importance":"高",
"evidence":"README main_features: Fewer bugs: Reduce about 40% of human (developer) induced errors"
},
{
"name":"编辑器友好",
"category":"核心能力",
"description":"仓库强调这一能力,重点在于:Great editor support. Completion everywhere. Less time debugging",
"importance":"高",
"evidence":"README main_features: Intuitive: Great editor support. Completion everywhere. Less time debugging"
},
{
"name":"低学习成本",
"category":"核心能力",
"description":"仓库强调这一能力,重点在于:Designed to be easy to use and learn. Less time reading docs",
"importance":"高",
"evidence":"README main_features: Easy: Designed to be easy to use and learn. Less time reading docs"
},
{
"name":"低样板代码",
"category":"核心能力",
"description":"仓库强调这一能力,重点在于:Minimize code duplication. Multiple features from each parameter declaration. Fewer bugs",
"importance":"高",
"evidence":"README main_features: Short: Minimize code duplication. Multiple features from each parameter declaration. Fewer bugs"
},
{
"name":"生产可用性",
"category":"核心能力",
"description":"仓库强调这一能力,重点在于:Get production-ready code. With automatic interactive documentation",
"importance":"高",
"evidence":"README main_features: Robust: Get production-ready code. With automatic interactive documentation"
},
{
"name":"标准兼容性",
"category":"核心能力",
"description":"仓库强调这一能力,重点在于:Based on (and fully compatible with) the open standards for APIs: OpenAPI (previously known as Swagger) and JSON Schema",
"importance":"高",
"evidence":"README main_features: Standards-based: Based on (and fully compatible with) the open standards for APIs: OpenAPI (previously known as Swagger) and JSON Schema"
"summary":"Transformers acts as the model-definition framework for state-of-the-art machine learning with text, computer vision, audio, video, and multimodal models, for both inference and training.",
"summary":"LangChain is a framework for building agents and LLM-powered applications. It helps you chain together interoperable components and third-party integrations to simplify AI application development — all while future-proofing decisions as the underlying technology evolves.",
"summary":"Visual Studio Code is a distribution of the Code - OSS repository with Microsoft-specific customizations released under a traditional Microsoft product license.",
"summary":"PyTorch is a Python package that provides two high-level features: - Tensor computation (like NumPy) with strong GPU acceleration - Deep neural networks built on a tape-based autograd system",
"summary":"LlamaIndex OSS (by LlamaIndex) is an open-source framework to build agentic applications. **Parse** is our enterprise platform for agentic OCR, parsing, extraction, indexing and more. You can use LlamaParse with this framework or on its own; see LlamaParse below for signup and product links.",
"summary":"Streamlit lets you transform Python scripts into interactive web apps in minutes, instead of weeks. Build dashboards, generate reports, or create chat apps. Once you’ve created an app, you can use our Community Cloud platform to deploy, manage, and share your app.",
"content":"请基于下面的 GitHub 仓库信息,提取结构化知识点。\n\n目标要求:\n1. 判断仓库类别,例如深度学习框架、Web 框架、LLM 应用框架、开发工具、数据平台等。\n2. 总结仓库的核心定位和学习价值。\n3. 提炼 5 到 8 个值得学习的知识点,每个知识点都要附带来源证据。\n4. 给出建议的前置知识和学习路径。\n5. 标出最值得关注的目录。\n\n仓库名称:airflow\n仓库链接:https://github.com/apache/airflow\n主要语言:Python\nStars:46099\n最近更新时间:2026-07-13T08:02:43Z\nmain_features:[\"Project Focus\", \"Principles\", \"Installing from PyPI\", \"Official source code\", \"Convenience packages\", \"User Interface\", \"Semantic versioning\", \"Version Life Cycle\"]\nmetadata:{\"owner\": \"apache\", \"default_branch\": \"main\", \"topics\": [\"airflow\", \"apache\", \"apache-airflow\", \"automation\", \"dag\", \"data-engineering\", \"data-integration\", \"data-orchestrator\", \"data-pipelines\", \"data-science\", \"elt\", \"etl\", \"machine-learning\", \"mlops\", \"orchestration\", \"python\", \"scheduler\", \"workflow\", \"workflow-engine\", \"workflow-orchestration\"]}\n\n目录结构摘录:\n├── .agents\n│ └── skills\n│ ├── aip-user-stories\n│ │ ├── references\n│ │ │ └── playbook-template.md\n│ │ └── SKILL.md\n│ ├── airflow-java-sdk\n│ │ └── SKILL.md\n│ ├── airflow-new-sdk\n│ │ └── SKILL.md\n│ ├── airflow-translations\n│ │ ├── locales\n│ │ │ ├── ar.md\n│ │ │ ├── ca.md\n│ │ │ ├── de.md\n│ │ │ ├── el.md\n│ │ │ ├── es.md\n│ │ │ ├── fr.md\n│ │ │ ├── he.md\n│ │ │ ├── hi.md\n│ │ │ ├── hu.md\n│ │ │ ├── it.md\n│ │ │ ├── ja.md\n│ │ │ ├── ko.md\n│ │ │ ├── nl.md\n│ │ │ ├── pl.md\n│ │ │ ├── pt.md\n│ │ │ ├── th.md\n│ │ │ ├── tr.md\n│ │ │ ├── zh-CN.md\n│ │ │ └── zh-TW.md\n│ │ └── SKILL.md\n│ ├── magpie-setup\n│ │ ├── adopt.md\n│ │ ├── agents.md\n│ │ ├── overrides.md\n│ │ ├── skill-sources.md\n│ │ ├── SKILL.md\n│ │ ├── unadopt.md\n│ │ ├── upgrade.md\n│ │ ├── verify.md\n│ │ └── worktree-init.md\n│ ├── prepare-providers-documentation\n│ │ └── SKILL.md\n│ └── upgrade-fab-provider\n│ └── SKILL.md\n├── .apache-magpie-overrides\n│ ├── pr-management-config.md\n│ ├── pr-management-triage-ci-check-map.md\n│ ├── pr-management-triage-comment-templates.md\n│ ├── README.md\n│ └── setup-isolated-setup-install.md\n├── .claude\n│ └── skills\n│ ├── aip-user-stories\n│ ├── airflow-translations\n│ ├── magpie-setup\n│ ├── prepare-providers-documentation\n│ └── upgrade-fab-provider\n├── .devcontainer\n│ ├── mysql\n│ │ └── devcontainer.json\n│ ├── postgres\n│ │ └── devcontainer.json\n│ └── devcontainer.json\n├── .github\n│ ├── actions\n│ │ ├── breeze\n│ │ │ └── action.yml\n│ │ ├── install-prek\n│ │ │ └── action.yml\n│ │ ├── migration_tests\n│ │ │ └── action.yml\n│ │ ├── post_tests_failure\n│ │ │ └── action.yml\n│ │ ├── post_tests_success\n│ │ │ └── action.yml\n│ │ ├── prepare_all_ci_images\n│ │ │ └── action.yml\n│ │ ├── prepare_breeze_and_image\n│ │ │ └── action.yml\n│ │ └── prepare_single_ci_image\n│ │ └── action.yml\n│ ├── instructions\n│ │ └── code-review.instructions.md\n│ ├── ISSUE_TEMPLATE\n│ │ ├── 1-airflow_bug_report.yml\n│ │ ├── 2-feature_request.yml\n│ │ ├── 3-free_form.yml\n│ │ ├── airflow_ctl_issue_template.yml\n│ │ └── config.yml\n│ ├── skills\n│ │ ├── aip-user-stories\n│ │ ├── airflow-translations\n│ │ ├── magpie-setup\n│ │ ├── prepare-providers-documentation\n│ │ └── upgrade-fab-provider\n│ ├── workflows\n│ │ ├── additional-ci-image-checks.yml\n│ │ ├── additional-prod-image-tests.yml\n│ │ ├── airflow-distributions-tests.yml\n│ │ ├── airflow-e2e-tests.yml\n│ │ ├── asf-allowlist-check.yml\n│ │ ├── automatic-backport.yml\n│ │ ├── backport-cli.yml\n│ │ ├── basic-tests.yml\n│ │ ├── check-newsfragment-pr-number.yml\n│ │ ├── ci-amd.yml\n│ │ ├── ci-arm.yml\n│ │ ├── ci-duration-monitor.yml\n│ │ ├── ci-image-build.yml\n│ │ ├── ci-image-checks.yml\n│ │ ├── ci-notification.yml\n│ │ ├── codeql-analysis.yml\n│ │ ├── e2e-flaky-tests-report.yml\n│ │ ├── finalize-tests.yml\n│ │ ├── generate-constraints.yml\n│ │ ├── helm-tests.yml\n│ │ ├── integration-system-tests.yml\n│ │ ├── java-sdk-release-verify.yml\n\nREADME 摘录:\n<!--\n Licensed to the Apache Software Foundation (ASF) under one\n or more contributor license agreements. See the NOTICE file\n distributed with this work for additional information\n regarding copyright ownership. The ASF licenses this file\n to you under the Apache License, Version 2.0 (the\n\"License\"); you may not use this file except in compliance\n with the License. You may obtain a copy of the License at\n\n http://www.apache.org/licenses/LICENSE-2.0\n\n Unless required by applicable law or agreed to in writing,\n software distributed under the License is distributed on an\n\"AS IS\" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY\n KIND, either express or implied. See the License for the\n specific language governing permissions and limitations\n under the License.\n-->\n\n<!-- START Apache Airflow, please keep comment here to allow auto update of PyPI readme.md -->\n# Apache Airflow\n\n| Category | Badges |\n|------------|--------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------|\n| License | [](https://www.apache.org/licenses/LICENSE-2.0.txt) |\n| PyPI | [](https://badge.fury.io/py/apache-airflow) [](https://pypi.org/project/apache-airflow/) [](https://pypi.org/project/apache-airflow/) |\n| Containers | [](https://hub.docker.com/r/apache/airflow) [](https://hub.docker.com/r/apache/airflow) [](https://artifacthub.io/packages/search?repo=apache-airflow) |\n| Community | [](https://github.com/apache/airflow/graphs/contributors) [](https://s.apache.org/airflow-slack) [](https://insights.linuxfoundation.org/project/apache-airflow) |\n| Dev tools | [](https://github.com/j178/prek) |\n\n| Version | Build Status |\n|---------|-----------------------------------------------------------------------------------------------------------------------------------------------------------------|\n| Main | [](https://github.com/apache/airflow/actions/workflows/ci-amd.yml) [](https://github.com/apache/airflow/actions/workflows/ci-arm.yml) |\n| 3.x | [](https://github.com/apache/airflow/actions/workflows/ci-amd.yml) [](https://github.com/apache/airflow/actions/workflows/ci-arm.yml) |\n\n<picture width=\"500\">\n\n</picture>\n\n[Apache Airflow](https://airflow.apache.org/docs/apache-airflow/stable/) (or simply Airflow) is a platform to programmatically author, schedule, and monitor workflows.\n\nWhen workflows are defined as code, they become more maintainable, versionable, testable, and collaborative.\n\nUse Airflow to author workflows (Dags) that orchestrate tasks. The Airflow scheduler executes your tasks on an array of workers while following the specified dependencies. Rich command line utilities make performing complex surgeries on Dags a snap. The rich user interface makes it easy to visualize pipelines running in production, monitor progress, and troubleshoot issues when needed.\n\n<!-- END Apache Airflow, please keep comment here to allow auto update of PyPI readme.md -->\n<!-- START doctoc generated TOC please keep comment here to allow auto update -->\n<!-- DON'T EDIT THIS SECTION, INSTEAD RE-RUN doctoc TO UPDATE -->\n**Table of contents**\n\n- [Project Focus](#project-focus)\n- [Principles](#principles)\n- [Requirements](#requirements)\n- [Getting started](#getting-started)\n- [Installing from PyPI](#installing-from-pypi)\n- [Installation](#installation)\n- [Official source code](#official-source-code)\n- [Convenience packages](#convenience-packages)\n- [User Interface](#user-interface)\n- [Semantic versioning](#semantic-versioning)\n- [Version Life Cycle](#version-life-cycle)\n- [Support for Python and Kubernetes versions](#support-for-python-and-kubernetes-versions)\n- [Base OS support for reference Airflow images](#base-os-support-for-reference-airflow-images)\n- [Approach to dependencies of Airflow](#approach-to-dependencies-of-airflow)\n- [Contributing](#contributing)\n- [Community standards](#community-standards)\n- [Agent-assisted contribution (apache-magpie)](#agent-assisted-contribution-apache-magpie)\n- [Voting Policy](#voting-policy)\n- [Who uses Apache Airflow?](#who-uses-apache-airflow)\n- [Who maintains Apache Airflow?](#who-maintains-apache-airflow)\n- [What goes into the next release?](#what-goes-into-the-next-release)\n- [Can I use the Apache Airflow logo in my presentation?](#can-i-use-the-apache-airflow-logo-in-my-presentation)\n- [Links](#links)\n- [Sponsors](#sponsors)\n\n<!-- END doctoc generated TOC please keep comment here to allow auto update -->\n\n## Project Focus\n\nAirflow works best with workflows that are mostly static and slowly changing. When the Dag structure is similar from one run to the next, it clarifies the unit of work and continuity. Other similar projects include [Luigi](https://github.com/spotify/luigi), [Oozie](https://oozie.apache.org/) and [Azkaban](https://azkaban.github.io/).\n\nAirflow is commonly used to process data, but has the opinion that tasks should ideally be idempotent (i.e., results of the task will be the same, and will not create duplicated data in a destination system), and should not pass large quantities of data from one task to the next (though tasks can pass metadata using Airflow's [XCom feature](https://airflow.apache.org/docs/apache-airflow/stable/concepts/xcoms.html)). For high-volume, data-intensive tasks, a best practice is to delegate to external services specializing in that type of work.\n\nAirflow is not a streaming solution, but it is often used to process real-time data, pulling data off streams in batches.\n\n## Principles\n\n- **Dynamic**: Pipelines are defined in code, enabling dynamic dag generation and parameterization.\n- **Extensible**: The Airflow framework includes a wide range of built-in operators and can be extended to fit your needs.\n- **Flexible**: Airflow leverages the [**Jinja**](https://jinja.palletsprojects.com) templating engine, allowing rich customizations.\n\n<!-- START Requirements, please keep comment here to allow auto update of PyPI readme.md -->\n## Requirements\n\nApache Airflow is tested with:\n\n| | Main version (dev) | Stable version (3.3.0) | Deprecate version (2.11.2) |\n|------------|------------------------------------|-------------------------------------|------------------------------|\n| Python | 3.10, 3.11, 3.12, 3.13, 3.14 | 3.10, 3.11, 3.12, 3.13, 3.14 | 3.10, 3.11, 3.12 |\n| Platform | AMD64/ARM64 | AMD64/ARM64 | AMD64/ARM64(\\*) |\n| Kubernetes | 1.30, 1.31, 1.32, 1.33, 1.34, 1.35 | 1.30, 1.31, 1.32, 1.33, 1.34, 1.35 | 1.26, 1.27, 1.28, 1.29, 1.30 |\n| PostgreSQL | 14, 15, 16, 17, 18 | 14, 15, 16, 17, 18 | 12, 13, 14, 15, 16 |\n| MySQL | 8.0, 8.4, Innovation | 8.0, 8.4, Innovation | 8.0, Innovation |\n| SQLite | 3.15.0+ | 3.15.0+ | 3.15.0+ |\n\n\\* Experimental\n\n**Note**: MariaDB is not tested/recommended.\n\n**Note**: SQLite is used in Airflow tests. Do not use it in production. We recommend\nusing the latest stable version of SQLite for local development.\n\n**Note**: Airflow currently can be run on POSIX-compliant Operating Systems. For development, it is regularly\ntested on fairly modern Linux Distros and recent versions of macOS.\nOn Windows you can run it via WSL2 (Windows Subsystem for Linux 2) or via Linux Containers.\nThe work to add Windows support is tracked via [#10388](https://github.com/apache/airflow/issues/10388), but\nit is not a high priority. You should only use Linux-based distros as \"Production\" execution environment\nas this is the only environment that is supported. The only distro that is used in our CI tests and that\nis used in the [Community managed DockerHub image](https://hub.docker.com/p/apache/airflow) is\n`Debian Bookworm`.\n\n<!-- END Requirements, please keep comment here to allow auto update of PyPI readme.md -->\n<!-- START Getting started, please keep comment here to allow auto update of PyPI readme.md -->\n## Getting started\n\nVisit the official Airflow website documentation (latest **stable** release) for help with\n[installing Airflow](https://airflow.apache.org/docs/apache-airflow/stable/installation/),\n[getting started](https://airflow.apache.org/docs/apache-airflow/stable/start.html), or walking\nthrough a more complete [tutorial](https://airflow.apache.org/docs/apache-airflow/stable/tutorial/).\n\n> Note: If you're looking for documentation for the main branch (latest development branch): you can find it on [s.apache.org/airflow-docs](https://s.apache.org/airflow-docs/).\n\nFor more information on Airflow Improvement Proposals (AIPs), visit\nthe [Airflow Wiki](https://cwiki.apache.org/confluence/display/AIRFLOW/Airflow+Improvement+Proposals).\n\nDocumentation for dependent projects like provider distributions, Docker image, Helm Chart, you'll find it in [the documentation index](https://airflow.apache.org/docs/).\n\n<!-- END Getting started, please keep comment here to allow auto update of PyPI readme.md -->\n<!-- START Installing from PyPI, please keep comment here to allow auto update of PyPI readme.md -->\n\n## Installing from PyPI\n\nWe publish Apache Airflow as `apache-airflow` package in PyPI. Installing it however might be sometimes tricky\nbecause Airflow is a bit of both a library and application. Libraries usually keep their dependencies open, and\napplications usually pin them, but we should do neither and both simultaneously. We decided to keep\nour dependencies as open as possible (in `pyproject.toml`) so users can install different versions of libraries\nif needed. This means that `pip install apache-airflow` will not work from time to time or will\nproduce unusable Airflow installation.\n\nTo have repeatable installation, however, we keep a set of \"known-to-be-working\" constrain\n"
"content":"请基于下面的 GitHub 仓库信息,提取结构化知识点。\n\n目标要求:\n1. 判断仓库类别,例如深度学习框架、Web 框架、LLM 应用框架、开发工具、数据平台等。\n2. 总结仓库的核心定位和学习价值。\n3. 提炼 5 到 8 个值得学习的知识点,每个知识点都要附带来源证据。\n4. 给出建议的前置知识和学习路径。\n5. 标出最值得关注的目录。\n\n仓库名称:fastapi\n仓库链接:https://github.com/fastapi/fastapi\n主要语言:Python\nStars:100418\n最近更新时间:2026-07-13T08:08:30Z\nmain_features:[\"Fast: Very high performance, on par with NodeJS and Go (thanks to Starlette and Pydantic). One of the fastest Python frameworks available\", \"Fast to code: Increase the speed to develop features by about 200% to 300%\", \"Fewer bugs: Reduce about 40% of human (developer) induced errors\", \"Intuitive: Great editor support. Completion everywhere. Less time debugging\", \"Easy: Designed to be easy to use and learn. Less time reading docs\", \"Short: Minimize code duplication. Multiple features from each parameter declaration. Fewer bugs\", \"Robust: Get production-ready code. With automatic interactive documentation\", \"Standards-based: Based on (and fully compatible with) the open standards for APIs: OpenAPI (previously known as Swagger) and JSON Schema\"]\nmetadata:{\"owner\": \"fastapi\", \"default_branch\": \"master\", \"topics\": [\"api\", \"async\", \"asyncio\", \"fastapi\", \"framework\", \"json\", \"json-schema\", \"openapi\", \"openapi3\", \"pydantic\", \"python\", \"python-types\", \"python3\", \"redoc\", \"rest\", \"starlette\", \"swagger\", \"swagger-ui\", \"uvicorn\", \"web\"]}\n\n目录结构摘录:\n├── .github\n│ ├── DISCUSSION_TEMPLATE\n│ │ ├── questions.yml\n│ │ └── translations.yml\n│ ├── ISSUE_TEMPLATE\n│ │ ├── config.yml\n│ │ └── privileged.yml\n│ ├── workflows\n│ │ ├── add-to-project.yml\n│ │ ├── build-docs.yml\n│ │ ├── bump-pre-commit-hooks.yml\n│ │ ├── contributors.yml\n│ │ ├── create-draft-release.yml\n│ │ ├── deploy-docs.yml\n│ │ ├── detect-conflicts.yml\n│ │ ├── guard-dependencies.yml\n│ │ ├── issue-manager.yml\n│ │ ├── label-approved.yml\n│ │ ├── labeler.yml\n│ │ ├── latest-changes.yml\n│ │ ├── notify-translations.yml\n│ │ ├── people.yml\n│ │ ├── pre-commit.yml\n│ │ ├── prepare-release.yml\n│ │ ├── publish.yml\n│ │ ├── smokeshow.yml\n│ │ ├── sponsors.yml\n│ │ ├── test-redistribute.yml\n│ │ ├── test.yml\n│ │ ├── topic-repos.yml\n│ │ ├── translate.yml\n│ │ └── zizmor.yml\n│ ├── dependabot.yml\n│ └── labeler.yml\n├── docs\n│ ├── de\n│ │ ├── docs\n│ │ │ ├── about\n│ │ │ │ └── index.md\n│ │ │ ├── advanced\n│ │ │ │ ├── security\n│ │ │ │ │ ├── http-basic-auth.md\n│ │ │ │ │ ├── index.md\n│ │ │ │ │ └── oauth2-scopes.md\n│ │ │ │ ├── additional-responses.md\n│ │ │ │ ├── additional-status-codes.md\n│ │ │ │ ├── advanced-dependencies.md\n│ │ │ │ ├── advanced-python-types.md\n│ │ │ │ ├── async-tests.md\n│ │ │ │ ├── behind-a-proxy.md\n│ │ │ │ ├── custom-response.md\n│ │ │ │ ├── dataclasses.md\n│ │ │ │ ├── events.md\n│ │ │ │ ├── generate-clients.md\n│ │ │ │ ├── index.md\n│ │ │ │ ├── json-base64-bytes.md\n│ │ │ │ ├── middleware.md\n│ │ │ │ ├── openapi-callbacks.md\n│ │ │ │ ├── openapi-webhooks.md\n│ │ │ │ ├── path-operation-advanced-configuration.md\n│ │ │ │ ├── response-change-status-code.md\n│ │ │ │ ├── response-cookies.md\n│ │ │ │ ├── response-directly.md\n│ │ │ │ ├── response-headers.md\n│ │ │ │ ├── settings.md\n│ │ │ │ ├── stream-data.md\n│ │ │ │ ├── strict-content-type.md\n│ │ │ │ ├── sub-applications.md\n│ │ │ │ ├── templates.md\n│ │ │ │ ├── testing-dependencies.md\n│ │ │ │ ├── testing-events.md\n│ │ │ │ ├── testing-websockets.md\n│ │ │ │ ├── using-request-directly.md\n│ │ │ │ ├── websockets.md\n│ │ │ │ └── wsgi.md\n│ │ │ ├── deployment\n│ │ │ │ ├── cloud.md\n│ │ │ │ ├── concepts.md\n│ │ │ │ ├── docker.md\n│ │ │ │ ├── fastapicloud.md\n│ │ │ │ ├── https.md\n│ │ │ │ ├── index.md\n│ │ │ │ ├── manually.md\n│ │ │ │ ├── server-workers.md\n│ │ │ │ └── versions.md\n│ │ │ ├── how-to\n│ │ │ │ ├── authentication-error-status-code.md\n│ │ │ │ ├── conditional-openapi.md\n│ │ │ │ ├── configure-swagger-ui.md\n│ │ │ │ ├── custom-docs-ui-assets.md\n│ │ │ │ ├── custom-request-and-route.md\n│ │ │ │ ├── extending-openapi.md\n│ │ │ │ ├── general.md\n│ │ │ │ ├── graphql.md\n│ │ │ │ ├── index.md\n│ │ │ │ ├── migrate-from-pydantic-v1-to-pydantic-v2.md\n│ │ │ │ ├── separate-openapi-schemas.md\n│ │ │ │ └── testing-database.md\n│ │ │ ├── learn\n│ │ │ │ └── index.md\n│ │ │ ├── resources\n│ │ │ │ └── index.md\n│ │ │ ├── tutorial\n│ │ │ │ ├── dependencies\n│ │ │ │ │ ├── classes-as-dependencies.md\n│ │ │ │ │ ├── dependencies-in-path-operation-decorators.md\n│ │ │ │ │ ├── dependencies-with-yield.md\n│ │ │ │ │ ├── global-dependencies.md\n│ │ │ │ │ ├── index.md\n│ │ │ │ │ └── sub-dependencies.md\n│ │ │ │ ├── security\n│ │ │ │ │ ├── first-steps.md\n│ │ │ │ │ ├── get-current-user.md\n│ │ │ │ │ ├── index.md\n│ │ │ │ │ ├── oauth2-jwt.md\n│ │ │ │ │ └── simple-oauth2.md\n│ │ │ │ ├── background-tasks.md\n│ │ │ │ ├── bigger-applications.md\n│ │ │ │ ├── body-fields.md\n│ │ │ │ ├── body-multiple-params.md\n\nREADME 摘录:\n<p align=\"center\">\n <a href=\"https://fastapi.tiangolo.com\"></a>\n</p>\n<p align=\"center\">\n <em>FastAPI framework, high performance, easy to learn, fast to code, ready for production</em>\n</p>\n<p align=\"center\">\n<a href=\"https://github.com/fastapi/fastapi/actions?query=workflow%3ATest+event%3Apush+branch%3Amaster\">\n\n</a>\n<a href=\"https://coverage-badge.samuelcolvin.workers.dev/redirect/fastapi/fastapi\">\n\n</a>\n<a href=\"https://pypi.org/project/fastapi\">\n\n</a>\n<a href=\"https://pypi.org/project/fastapi\">\n\n</a>\n</p>\n\n---\n\n**Documentation**: [https://fastapi.tiangolo.com](https://fastapi.tiangolo.com)\n\n**Source Code**: [https://github.com/fastapi/fastapi](https://github.com/fastapi/fastapi)\n\n---\n\nFastAPI is a modern, fast (high-performance), web framework for building APIs with Python based on standard Python type hints.\n\nThe key features are:\n\n* **Fast**: Very high performance, on par with **NodeJS** and **Go** (thanks to Starlette and Pydantic). [One of the fastest Python frameworks available](#performance).\n* **Fast to code**: Increase the speed to develop features by about 200% to 300%. *\n* **Fewer bugs**: Reduce about 40% of human (developer) induced errors. *\n* **Intuitive**: Great editor support. <dfn title=\"also known as auto-complete, autocompletion, IntelliSense\">Completion</dfn> everywhere. Less time debugging.\n* **Easy**: Designed to be easy to use and learn. Less time reading docs.\n* **Short**: Minimize code duplication. Multiple features from each parameter declaration. Fewer bugs.\n* **Robust**: Get production-ready code. With automatic interactive documentation.\n* **Standards-based**: Based on (and fully compatible with) the open standards for APIs: [OpenAPI](https://github.com/OAI/OpenAPI-Specification) (previously known as Swagger) and [JSON Schema](https://json-schema.org/).\n\n<small>* estimation based on tests conducted by an internal development team, building production applications.</small>\n\n## Sponsors\n\n<!-- sponsors -->\n### Keystone Sponsor\n\n<a href=\"https://fastapicloud.com\" target=\"_blank\" title=\"FastAPI Cloud. By the same team behind FastAPI. You code. We Cloud.\"></a>\n\n### Gold Sponsors\n\n<a href=\"https://blockbee.io?ref=fastapi\" target=\"_blank\" title=\"BlockBee Cryptocurrency Payment Gateway\"></a>\n<a href=\"https://www.propelauth.com/?utm_source=fastapi&utm_campaign=1223&utm_medium=mainbadge\" target=\"_blank\" title=\"Auth, user management and more for your B2B product\"></a>\n<a href=\"https://docs.render.com/deploy-fastapi?utm_source=deploydoc&utm_medium=referral&utm_campaign=fastapi\" target=\"_blank\" title=\"Deploy & scale any full-stack web app on Render. Focus on building apps, not infra.\"></a>\n<a href=\"https://www.coderabbit.ai/?utm_source=fastapi&utm_medium=badge&utm_campaign=fastapi\" target=\"_blank\" title=\"Cut Code Review Time & Bugs in Half with CodeRabbit\"></a>\n<a href=\"https://subtotal.com/?utm_source=fastapi&utm_medium=sponsorship&utm_campaign=open-source\" target=\"_blank\" title=\"The Gold Standard in Retail Account Linking\"></a>\n<a href=\"https://docs.railway.com/guides/fastapi?utm_medium=integration&utm_source=docs&utm_campaign=fastapi\" target=\"_blank\" title=\"Deploy enterprise applications at startup speed\"></a>\n<a href=\"https://serpapi.com/?utm_source=fastapi_website\" target=\"_blank\" title=\"SerpApi: Web Search API\"></a>\n<a href=\"https://www.greptile.com/?utm_source=fastapi&utm_medium=sponsorship&utm_campaign=fastapi_sponsor_page\" target=\"_blank\" title=\"Greptile: The AI Code Reviewer\"></a>\n\n### Silver Sponsors\n\n<a href=\"https://databento.com/?utm_source=fastapi&utm_medium=sponsor&utm_content=display\" target=\"_blank\" title=\"Pay as you go for market data\"></a>\n<a href=\"https://www.svix.com/\" target=\"_blank\" title=\"Svix - Webhooks as a service\"></a>\n<a href=\"https://www.permit.io/blog/implement-authorization-in-fastapi?utm_source=github&utm_medium=referral&utm_campaign=fastapi\" target=\"_blank\" title=\"Fine-Grained Authorization for FastAPI\"></a>\n<a href=\"https://dribia.com/en/\" target=\"_blank\" title=\"Dribia - Data Science within your reach\"></a>\n<a href=\"https://www.bairesdev.com/\" target=\"_blank\" title=\"BairesDev | Nearshore Software Development & Staff Augmentation Company\"></a>\n<a href=\"https://tutorcruncher.com/?utm_source=fastapi\" target=\"_blank\" title=\"TutorCruncher\"></a>\n\n<!-- /sponsors -->\n\n[Other sponsors](https://fastapi.tiangolo.com/fastapi-people/#sponsors)\n\n## Opinions\n\n<div class=\"only-github\" markdown=\"1\">\n\n\"_[...] I'm using **FastAPI** a ton these days. [...] I'm actually planning to use it for all of my team's **ML services at Microsoft**. Some of them are getting integrated into the core **Windows** product and some **Office** products._\"\n\n<div style=\"text-align: right; margin-right: 10%;\">Kabir Khan - <strong>Microsoft</strong> <a href=\"https://github.com/fastapi/fastapi/pull/26\"><small>(ref)</small></a></div>\n\n---\n\n\"_We adopted the **FastAPI** library to spawn a **REST** server that can be queried to obtain **predictions**. [for Ludwig]_\"\n\n<div style=\"text-align: right; margin-right: 10%;\">Piero Molino, Yaroslav Dudin, and Sai Sumanth Miryala - <strong>Uber</strong> <a href=\"https://eng.uber.com/ludwig-v0-2/\"><small>(ref)</small></a></div>\n\n---\n\n\"_**Netflix** is pleased to announce the open-source release of our **crisis management** orchestration framework: **Dispatch**! [built with **FastAPI**]_\"\n\n<div style=\"text-align: right; margin-right: 10%;\">Kevin Glisson, Marc Vilanova, Forest Monsen - <strong>Netflix</strong> <a href=\"https://netflixtechblog.com/introducing-dispatch-da4b8a2a8072\"><small>(ref)</small></a></div>\n\n---\n\n\"_If anyone is looking to build a production Python API, I would highly recommend **FastAPI**. It is **beautifully designed**, **simple to use** and **highly scalable**, it has become a **key component** in our API first development strategy and is driving many automations and services such as our Virtual TAC Engineer._\"\n\n<div style=\"text-align: right; margin-right: 10%;\">Deon Pillsbury - <strong>Cisco</strong> <a href=\"https://www.linkedin.com/posts/deonpillsbury_cisco-cx-python-activity-6963242628536487936-trAp/\"><small>(ref)</small></a></div>\n\n---\n\n</div>\n\n## FastAPI Conf\n\n[**FastAPI Conf '26**](https://fastapiconf.com) is happening on **October 28, 2026** in **Amsterdam, NL**. All about FastAPI, right from the source. 🎤\n\n<a class=\"fastapi-feature-banner\" href=\"https://fastapiconf.com\"></a>\n\n## FastAPI mini documentary\n\nThere's a [FastAPI mini documentary](https://www.youtube.com/watch?v=mpR8ngthqiE) released at the end of 2025, you can watch it online:\n\n<a class=\"fastapi-feature-banner\" href=\"https://www.youtube.com/watch?v=mpR8ngthqiE\"></a>\n\n## **Typer**, the FastAPI of CLIs\n\n<a href=\"https://typer.tiangolo.com\"></a>\n\nIf you are building a <abbr title=\"Command Line Interface\">CLI</abbr> app to be used in the terminal instead of a web API, check out [**Typer**](https://typer.tiangolo.com/).\n\n**Typer** is FastAPI's little sibling. And it's intended to be the **FastAPI of CLIs**. ⌨️ 🚀\n\n## Requirements\n\nFastAPI stands on the shoulders of giants:\n\n* [Starlette](https://www.starlette.dev/) for the web parts.\n* [Pydantic](https://docs.pydantic.dev/) for the data parts.\n\n## Installation\n\nCreate and activate a [virtual environment](https://fastapi.tiangolo.com/virtual-environments/) and then install FastAPI:\n\n<div class=\"termy\">\n\n</div>\n\n**Note**: Make sure you put `\"fastapi[standard]\"` in quotes to ensure it works in all terminals.\n\n## Example\n\n### Create it\n\nCreate a file `main.py` with:\n\n<details markdown=\"1\">\n<summary>Or use <code>async def</code>...</summary>\n\nIf your code uses `async` / `await`, use `async def`:\n\n**Note**:\n\nIf you don't know, check the _\"In a hurry?\"_ section about [`async` and `await` in the docs](https://fastapi.tiangolo.com/async/#in-a-hurry).\n\n</details>\n\n### Run it\n\nRun the server with:\n\n<div class=\"termy\">\n\n</div>\n\n<details markdown=\"1\">\n<summary>About the command <code>fastapi dev</code>...</summary>\n\nThe command `fastapi dev` reads your `main.py` file automatically, detects the **FastAPI** app in it, and starts a server using [Uvicorn](https://www.uvicorn.dev).\n\nBy default, `fastapi dev` will start with auto-reload enabled for local development.\n\nYou can read more about it in the [FastAPI CLI docs](https://fastapi.tiangolo.com/fastapi-cli/).\n\n</details>\n\n### Check it\n\nOpen your browser at [http://127.0.0.1:8000/items/5?q=somequery](http://127.0.0.1:8000/items/5?q=somequery).\n\nYou will see the JSON response as:\n\nYou already created an API that:\n\n* Receives HTTP requests in the _paths_ `/` and `/items/{item_id}`.\n* Both _paths_ take `GET` <em>operations</em> (also known as HTTP _methods_).\n* The _path_ `/items/{item_id}` has a _path parameter_ `item_id` that should be an `int`.\n* The _path_ `/items/{item_id}` has an optional `str` _query parameter_ `q`.\n\n### Interactive API docs\n\nNow go to [http://127.0.0.1:8000/docs](http://127.0.0.1:8000/docs).\n\nYou will see the automatic interactive API documentation (provided by [Swagger UI](https://github.com/swagger-api/swagger-ui)):\n\n### Alternative API docs\n\nAnd now, go to [http://127.0.0.1:8000/redoc](http://127.0.0.1:8000/redoc).\n\nYou will see the alternative automatic documentation (provided by [ReDoc](https://github.com/Rebilly/ReDoc)):\n\n## Example upgrade\n\nNow modify the file `main.py` to receive a body from a `PUT` request.\n\nDeclare the body using standard Python types, thanks to Pydantic.\n\nThe `fastapi dev` server should reload automatically.\n\n### Interactive API docs upgrade\n\nNow go to [http://127.0.0.1:8000/docs](http://127.0.0.1:8000/docs).\n\n* The interactive API documentation will be automatically updated, including the new body:\n\n* Click on the button \"Try it out\", it allows you to fill the parameters and directly interact with the API:\n\n* Then click on the \"Execute\" button, the user interface will communicate with your API, send the parameters, get the results and show them on the screen:\n\n### Alternative API docs upgrade\n\nAnd now, go to [http://127.0.0.1:8000/redoc](http://127.0.0.1:8000/redoc).\n\n* The alternative documentation will also reflect the new query parameter and body:\n\n### Recap\n\nIn summary, you declare **once** the types of parameters, body, etc. as function parameters.\n\nYou do that with standard modern Python types.\n\nYou don't have to learn a new syntax, the methods or classes of a specific library, etc.\n\nJust standard **Python**.\n\nFor example, for an `int`:\n\nor for a more complex `Item` model:\n\n...and with that single declaration you get:\n\n* Editor support, including:\n * Completion.\n * Type checks.\n* Validation of data:\n * Automatic and clear errors when the data is invalid.\n * Validation even for deeply nested JSON objects.\n* <dfn title=\"also known as: serialization, parsing, marshalling\">Conversion</dfn> of input data: coming from the network to Python data and types. Reading from:\n * JSON.\n * Path parameters.\n * Query parameters.\n * Cookies.\n * Headers.\n * Forms.\n * Files.\n* <dfn title=\"also known as: serialization, parsing, marshalling\">Conversion</dfn> of output data: converting from Python data and types to network data (as JSON):\n * Convert Python types (`str`, `int`, `float`, `bool`, `list`, etc).\n * `datetime` objects.\n * `UUID` objects.\n * Database models.\n * ...and many more.\n* Automatic interactive API documentation, including 2 alternative user interfaces:\n * Swagger UI.\n * ReDoc.\n\n---\n\nComing back to the previous code example, **FastAPI** will:\n\n* Validate that there is an `item_id` in the path for `GET` and `PUT` requests.\n* Validate that the `item_id` is of type `int` for `GET` and `PUT` requests.\n * If it is not, the client will see a useful, clear error.\n* Check if there is an optional query parameter named `q` (as in `http://127.0.0.1:8000/items/foo?q=somequery`) for `GET` requests.\n * As the `q` parameter is declared with `= None`, it is optional.\n * Without the `None` it would be required (as is the body in the case wi\n"
"content":"请基于下面的 GitHub 仓库信息,提取结构化知识点。\n\n目标要求:\n1. 判断仓库类别,例如深度学习框架、Web 框架、LLM 应用框架、开发工具、数据平台等。\n2. 总结仓库的核心定位和学习价值。\n3. 提炼 5 到 8 个值得学习的知识点,每个知识点都要附带来源证据。\n4. 给出建议的前置知识和学习路径。\n5. 标出最值得关注的目录。\n\n仓库名称:transformers\n仓库链接:https://github.com/huggingface/transformers\n主要语言:Python\nStars:162559\n最近更新时间:2026-07-13T07:42:55Z\nmain_features:[\"Why should I use Transformers?\", \"When shouldn't I use Transformers?\", \"projects using Transformers\", \"Example models\", \"Citation\"]\nmetadata:{\"owner\": \"huggingface\", \"default_branch\": \"main\", \"topics\": [\"audio\", \"deep-learning\", \"deepseek\", \"gemma\", \"glm\", \"hacktoberfest\", \"llm\", \"machine-learning\", \"model-hub\", \"natural-language-processing\", \"nlp\", \"pretrained-models\", \"python\", \"pytorch\", \"pytorch-transformers\", \"qwen\", \"speech-recognition\", \"transformer\", \"vlm\"]}\n\n目录结构摘录:\n├── .ai\n│ ├── skills\n│ │ └── add-or-fix-type-checking\n│ │ └── SKILL.md\n│ └── AGENTS.md\n├── .circleci\n│ ├── config.yml\n│ ├── config.yml.bak\n│ ├── create_circleci_config.py\n│ ├── parse_test_outputs.py\n│ └── TROUBLESHOOT.md\n├── .github\n│ ├── conda\n│ │ ├── build.sh\n│ │ └── meta.yaml\n│ ├── ISSUE_TEMPLATE\n│ │ ├── bug-report.yml\n│ │ ├── config.yml\n│ │ ├── feature-request.yml\n│ │ ├── i18n.md\n│ │ ├── migration.yml\n│ │ └── new-model-addition.yml\n│ ├── scripts\n│ │ ├── assign_reviewers.py\n│ │ └── codeowners_for_review_action\n│ ├── workflows\n│ │ ├── add-model-like.yml\n│ │ ├── anti-slop.yml\n│ │ ├── assign-reviewers.yml\n│ │ ├── benchmark.yml\n│ │ ├── benchmark_v2.yml\n│ │ ├── benchmark_v2_a10_caller.yml\n│ │ ├── benchmark_v2_mi300_caller.yml\n│ │ ├── build-ci-docker-images.yml\n│ │ ├── build-docker-images.yml\n│ │ ├── build-nightly-ci-docker-images.yml\n│ │ ├── build-past-ci-docker-images.yml\n│ │ ├── build_documentation.yml\n│ │ ├── build_pr_documentation.yml\n│ │ ├── check-workflow-permissions.yml\n│ │ ├── check_failed_tests.yml\n│ │ ├── check_tiny_models.yml\n│ │ ├── circleci-failure-summary-comment.yml.bak\n│ │ ├── codeql.yml\n│ │ ├── collated-reports.yml\n│ │ ├── dependents-smoke-test.yml\n│ │ ├── doctest_job.yml\n│ │ ├── doctests.yml\n│ │ ├── extras-smoke-test.yml\n│ │ ├── get-pr-info.yml\n│ │ ├── get-pr-number.yml\n│ │ ├── model_jobs.yml\n│ │ ├── model_jobs_intel_gaudi.yml\n│ │ ├── new_model_pr_merged_notification.yml\n│ │ ├── nightly-integration-failure-triage-caller.yml\n│ │ ├── pr-ci-caller.yml\n│ │ ├── pr-ci-post-dashboard-link.yml\n│ │ ├── pr-ci-security-gate.yml\n│ │ ├── pr-repo-consistency-bot.yml\n│ │ ├── pr_build_doc_with_comment.yml\n│ │ ├── pr_slow_ci_suggestion.yml\n│ │ ├── push-important-models.yml\n│ │ ├── release-conda.yml\n│ │ ├── release.yml\n│ │ ├── self-comment-ci.yml\n│ │ ├── self-nightly-caller.yml\n│ │ ├── self-nightly-past-ci-caller.yml\n│ │ ├── self-past-caller.yml\n│ │ ├── self-scheduled-amd-caller.yml\n│ │ ├── self-scheduled-amd-mi250-caller.yml\n│ │ ├── self-scheduled-amd-mi300-caller.yml\n│ │ ├── self-scheduled-amd-mi355-caller.yml\n│ │ ├── self-scheduled-caller.yml\n│ │ ├── self-scheduled-flash-attn-caller.yml\n│ │ ├── self-scheduled-intel-gaudi.yml\n│ │ ├── self-scheduled-intel-gaudi3-caller.yml\n│ │ ├── self-scheduled.yml\n│ │ ├── slack-report.yml\n│ │ ├── ssh-runner.yml\n│ │ ├── stale.yml\n│ │ ├── trl-ci-bot.yml\n│ │ ├── TROUBLESHOOT.md\n│ │ ├── trufflehog.yml\n│ │ ├── update_metdata.yml\n│ │ └── upload_pr_documentation.yml\n│ ├── copilot-instructions.md\n│ ├── dependabot.yml\n│ └── PULL_REQUEST_TEMPLATE.md\n├── benchmark\n│ ├── benches\n│ │ └── llama.py\n│ ├── config\n│ │ └── generation.yaml\n│ ├── utils\n│ │ └── init_db.sql\n│ ├── .gitignore\n│ ├── __init__.py\n│ ├── benchmark.py\n│ ├── benchmarks_entrypoint.py\n│ ├── default.yml\n│ ├── grafana_dashboard.json\n│ ├── grafana_datasource.yaml\n│ ├── optimum_benchmark_wrapper.py\n│ ├── README.md\n│ └── requirements.txt\n├── benchmark_v2\n│ ├── benchmark_scripts\n│ │ └── continuous_batching_overall.py\n│ ├── framework\n│ │ ├── benchmark_config.py\n│ │ ├── benchmark_runner.py\n│ │ ├── data_classes.py\n│ │ └── hardware_metrics.py\n│ ├── .gitignore\n│ ├── README.md\n│ ├── requirements.txt\n│ └── run_benchmarks.py\n├── docker\n│ ├── transformers-all-latest-gpu\n│ │ └── Dockerfile\n\nREADME 摘录:\n<!---\nCopyright 2020 The HuggingFace Team. All rights reserved.\n\nLicensed under the Apache License, Version 2.0 (the \"License\");\nyou may not use this file except in compliance with the License.\nYou may obtain a copy of the License at\n\n http://www.apache.org/licenses/LICENSE-2.0\n\nUnless required by applicable law or agreed to in writing, software\ndistributed under the License is distributed on an \"AS IS\" BASIS,\nWITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.\nSee the License for the specific language governing permissions and\nlimitations under the License.\n-->\n\n<p align=\"center\">\n\n <br/>\n <br/>\n</p>\n\n<p align=\"center\">\n <a href=\"https://huggingface.com/models\"></a>\n <a href=\"https://circleci.com/gh/huggingface/transformers\"></a>\n <a href=\"https://github.com/huggingface/transformers/blob/main/LICENSE\"></a>\n <a href=\"https://huggingface.co/docs/transformers/index\"></a>\n <a href=\"https://github.com/huggingface/transformers/releases\"></a>\n <a href=\"https://github.com/huggingface/transformers/blob/main/CODE_OF_CONDUCT.md\"></a>\n <a href=\"https://zenodo.org/badge/latestdoi/155220641\"></a>\n</p>\n\n<h4 align=\"center\">\n <p>\n <b>English</b> |\n <a href=\"https://github.com/huggingface/transformers/blob/main/i18n/README_zh-hans.md\">简体中文</a> |\n <a href=\"https://github.com/huggingface/transformers/blob/main/i18n/README_zh-hant.md\">繁體中文</a> |\n <a href=\"https://github.com/huggingface/transformers/blob/main/i18n/README_ko.md\">한국어</a> |\n <a href=\"https://github.com/huggingface/transformers/blob/main/i18n/README_es.md\">Español</a> |\n <a href=\"https://github.com/huggingface/transformers/blob/main/i18n/README_ja.md\">日本語</a> |\n <a href=\"https://github.com/huggingface/transformers/blob/main/i18n/README_hd.md\">हिन्दी</a> |\n <a href=\"https://github.com/huggingface/transformers/blob/main/i18n/README_ru.md\">Русский</a> |\n <a href=\"https://github.com/huggingface/transformers/blob/main/i18n/README_pt-br.md\">Português</a> |\n <a href=\"https://github.com/huggingface/transformers/blob/main/i18n/README_te.md\">తెలుగు</a> |\n <a href=\"https://github.com/huggingface/transformers/blob/main/i18n/README_fr.md\">Français</a> |\n <a href=\"https://github.com/huggingface/transformers/blob/main/i18n/README_de.md\">Deutsch</a> |\n <a href=\"https://github.com/huggingface/transformers/blob/main/i18n/README_it.md\">Italiano</a> |\n <a href=\"https://github.com/huggingface/transformers/blob/main/i18n/README_vi.md\">Tiếng Việt</a> |\n <a href=\"https://github.com/huggingface/transformers/blob/main/i18n/README_ar.md\">العربية</a> |\n <a href=\"https://github.com/huggingface/transformers/blob/main/i18n/README_ur.md\">اردو</a> |\n <a href=\"https://github.com/huggingface/transformers/blob/main/i18n/README_bn.md\">বাংলা</a> |\n <a href=\"https://github.com/huggingface/transformers/blob/main/i18n/README_fa.md\">فارسی</a> |\n <a href=\"https://github.com/huggingface/transformers/blob/main/i18n/README_tr.md\">Türkçe</a> |\n </p>\n</h4>\n\n<h3 align=\"center\">\n <p>State-of-the-art pretrained models for inference and training</p>\n</h3>\n\n<h3 align=\"center\">\n\n</h3>\n\nTransformers acts as the model-definition framework for state-of-the-art machine learning with text, computer\nvision, audio, video, and multimodal models, for both inference and training.\n\nIt centralizes the model definition so that this definition is agreed upon across the ecosystem. `transformers` is the\npivot across frameworks: if a model definition is supported, it will be compatible with the majority of training\nframeworks (Axolotl, Unsloth, DeepSpeed, FSDP, PyTorch-Lightning, ...), inference engines (vLLM, SGLang, TGI, ...),\nand adjacent modeling libraries (llama.cpp, mlx, ...) which leverage the model definition from `transformers`.\n\nWe pledge to help support new state-of-the-art models and democratize their usage by having their model definition be\nsimple, customizable, and efficient.\n\nThere are over 1M+ Transformers [model checkpoints](https://huggingface.co/models?library=transformers&sort=trending) on the [Hugging Face Hub](https://huggingface.co/models) you can use.\n\nExplore the [Hub](https://huggingface.co/) today to find a model and use Transformers to help you get started right away.\n\n## Installation\n\nTransformers works with Python 3.10+, and [PyTorch](https://pytorch.org/get-started/locally/) 2.4+.\n\nCreate and activate a virtual environment with [venv](https://docs.python.org/3/library/venv.html) or [uv](https://docs.astral.sh/uv/), a fast Rust-based Python package and project manager.\n\nInstall Transformers in your virtual environment.\n\nInstall Transformers from source if you want the latest changes in the library or are interested in contributing. However, the *latest* version may not be stable. Feel free to open an [issue](https://github.com/huggingface/transformers/issues) if you encounter an error.\n\n## Quickstart\n\nGet started with Transformers right away with the [Pipeline](https://huggingface.co/docs/transformers/pipeline_tutorial) API. The `Pipeline` is a high-level inference class that supports text, audio, vision, and multimodal tasks. It handles preprocessing the input and returns the appropriate output.\n\nInstantiate a pipeline and specify model to use for text generation. The model is downloaded and cached so you can easily reuse it again. Finally, pass some text to prompt the model.\n\nTo chat with a model, the usage pattern is the same. The only difference is you need to construct a chat history (the input to `Pipeline`) between you and the system.\n\n> [!TIP]\n> You can also chat with a model directly from the command line, as long as [`transformers serve` is running](https://huggingface.co/docs/transformers/main/en/serving).\n> \n\nExpand the examples below to see how `Pipeline` works for different modalities and tasks.\n\n<details>\n<summary>Automatic speech recognition</summary>\n\n</details>\n\n<details>\n<summary>Image classification</summary>\n\n<h3 align=\"center\">\n <a></a>\n</h3>\n\n</details>\n\n<details>\n<summary>Visual question answering</summary>\n\n<h3 align=\"center\">\n <a></a>\n</h3>\n\n</details>\n\n## Why should I use Transformers?\n\n1. Easy-to-use state-of-the-art models:\n - High performance on natural language understanding & generation, computer vision, audio, video, and multimodal tasks.\n - Low barrier to entry for researchers, engineers, and developers.\n - Few user-facing abstractions with just three classes to learn.\n - A unified API for using all our pretrained models.\n\n1. Lower compute costs, smaller carbon footprint:\n - Share trained models instead of training from scratch.\n - Reduce compute time and production costs.\n - Hundreds of model architectures with 1M+ pretrained checkpoints across all modalities.\n\n1. Choose the right framework for every part of a model's lifetime:\n - Train state-of-the-art models in 3 lines of code.\n - Move a single model between PyTorch/JAX/TF2.0 frameworks at will.\n - Pick the right framework for training, evaluation, and production.\n\n1. Easily customize a model or an example to your needs:\n - We provide examples for each architecture to reproduce the results published by its original authors.\n - Model internals are exposed as consistently as possible.\n - Model files can be used independently of the library for quick experiments.\n\n<a target=\"_blank\" href=\"https://huggingface.co/enterprise\">\n\n</a><br>\n\n## When shouldn't I use Transformers?\n\n- This library is not a modular toolbox of building blocks for neural nets. The code in the model files is not refactored with additional abstractions on purpose, so that researchers can quickly iterate on each of the models without diving into additional abstractions/files.\n- The training API is optimized to work with PyTorch models provided by Transformers. For generic machine learning loops, you should use another library like [Accelerate](https://huggingface.co/docs/accelerate).\n- The [example scripts](https://github.com/huggingface/transformers/tree/main/examples) are only *examples*. They may not necessarily work out-of-the-box on your specific use case and you'll need to adapt the code for it to work.\n\n## 100 projects using Transformers\n\nTransformers is more than a toolkit to use pretrained models, it's a community of projects built around it and the\nHugging Face Hub. We want Transformers to enable developers, researchers, students, professors, engineers, and anyone\nelse to build their dream projects.\n\nIn order to celebrate Transformers 100,000 stars, we wanted to put the spotlight on the\ncommunity with the [awesome-transformers](./awesome-transformers.md) page which lists 100\nincredible projects built with Transformers.\n\nIf you own or use a project that you believe should be part of the list, please open a PR to add it!\n\n## Example models\n\nYou can test most of our models directly on their [Hub model pages](https://huggingface.co/models).\n\nExpand each modality below to see a few example models for various use cases.\n\n<details>\n<summary>Audio</summary>\n\n- Audio classification with [CLAP](https://huggingface.co/laion/clap-htsat-fused)\n- Automatic speech recognition with [Parakeet](https://huggingface.co/nvidia/parakeet-ctc-1.1b#transcribing-using-transformers-%F0%9F%A4%97), [Whisper](https://huggingface.co/openai/whisper-large-v3-turbo), [GLM-ASR](https://huggingface.co/zai-org/GLM-ASR-Nano-2512) and [Moonshine-Streaming](https://huggingface.co/UsefulSensors/moonshine-streaming-medium)\n- Keyword spotting with [Wav2Vec2](https://huggingface.co/superb/wav2vec2-base-superb-ks)\n- Speech to speech generation with [Moshi](https://huggingface.co/kyutai/moshiko-pytorch-bf16)\n- Text to audio with [MusicGen](https://huggingface.co/facebook/musicgen-large)\n- Text to speech with [CSM](https://huggingface.co/sesame/csm-1b)\n\n</details>\n\n<details>\n<summary>Computer vision</summary>\n\n- Automatic mask generation with [SAM](https://huggingface.co/facebook/sam-vit-base)\n- Depth estimation with [DepthPro](https://huggingface.co/apple/DepthPro-hf)\n- Image classification with [DINO v2](https://huggingface.co/facebook/dinov2-base)\n- Keypoint detection with [SuperPoint](https://huggingface.co/magic-leap-community/superpoint)\n- Keypoint matching with [SuperGlue](https://huggingface.co/magic-leap-community/superglue_outdoor)\n- Object detection with [RT-DETRv2](https://huggingface.co/PekingU/rtdetr_v2_r50vd)\n- Pose Estimation with [VitPose](https://huggingface.co/usyd-community/vitpose-base-simple)\n- Universal segmentation with [OneFormer](https://huggingface.co/shi-labs/oneformer_ade20k_swin_large)\n- Video classification with [VideoMAE](https://huggingface.co/MCG-NJU/videomae-large)\n\n</details>\n\n<details>\n<summary>Multimodal</summary>\n\n- Audio or text to text with [Voxtral](https://huggingface.co/mistralai/Voxtral-Mini-3B-2507), [Audio Flamingo](https://huggingface.co/nvidia/audio-flamingo-3-hf)\n- Document question answering with [LayoutLMv3](https://huggingface.co/microsoft/layoutlmv3-base)\n- Image or text to text with [Qwen-VL](https://huggingface.co/Qwen/Qwen2.5-VL-3B-Instruct)\n- Image captioning [BLIP-2](https://huggingface.co/Salesforce/blip2-opt-2.7b)\n- OCR-based document understanding with [GOT-OCR2](https://huggingface.co/stepfun-ai/GOT-OCR-2.0-hf)\n- Table question answering with [TAPAS](https://huggingface.co/google/tapas-base)\n- Unified multimodal understanding and generation with [Emu3](https://huggingface.co/BAAI/Emu3-Gen)\n- Vision to text with [Llava-OneVision](https://huggingface.co/llava-hf/llava-onevision-qwen2-0.5b-ov-hf)\n- Visual question answering with [Llava](https://huggingface.co/llava-hf/llava-1.5-7b-hf)\n- Visual referring expression segmentation with [Kosmos-2](https://huggingface.co/microsoft/kosmos-2-patch14-224)\n\n</details>\n\n<details>\n<summary>NLP</summary>\n\n- Masked word completion with [ModernBERT](https://huggingface.co/answerdotai/ModernBERT-base)\n- Named entity rec\n"
"content":"请基于下面的 GitHub 仓库信息,提取结构化知识点。\n\n目标要求:\n1. 判断仓库类别,例如深度学习框架、Web 框架、LLM 应用框架、开发工具、数据平台等。\n2. 总结仓库的核心定位和学习价值。\n3. 提炼 5 到 8 个值得学习的知识点,每个知识点都要附带来源证据。\n4. 给出建议的前置知识和学习路径。\n5. 标出最值得关注的目录。\n\n仓库名称:vscode\n仓库链接:https://github.com/microsoft/vscode\n主要语言:TypeScript\nStars:187487\n最近更新时间:2026-07-13T08:02:45Z\nmain_features:[\"The Repository\", \"Visual Studio Code\", \"Feedback\", \"Related Projects\", \"Bundled Extensions\", \"Development Container\", \"Code of Conduct\"]\nmetadata:{\"owner\": \"microsoft\", \"default_branch\": \"main\", \"topics\": [\"editor\", \"electron\", \"microsoft\", \"typescript\", \"visual-studio-code\"]}\n\n目录结构摘录:\n├── .agents\n│ └── skills\n│ └── launch\n│ ├── scripts\n│ │ ├── launch.sh\n│ │ └── monaco-paste.sh\n│ └── SKILL.md\n├── .config\n│ ├── 1espt\n│ │ └── PipelineAutobaseliningConfig.yml\n│ ├── guardian\n│ │ └── .gdnsuppress\n│ └── configuration.winget\n├── .devcontainer\n│ ├── devcontainer-lock.json\n│ ├── devcontainer.json\n│ ├── Dockerfile\n│ ├── install-vscode.sh\n│ ├── post-create.sh\n│ └── README.md\n├── .eslint-plugin-local\n│ ├── tests\n│ │ ├── code-no-observable-get-in-reactive-context-test.ts\n│ │ └── code-no-reader-after-await-test.ts\n│ ├── code-amd-node-module.ts\n│ ├── code-declare-service-brand.ts\n│ ├── code-ensure-no-disposables-leak-in-test.ts\n│ ├── code-import-patterns.ts\n│ ├── code-layering.ts\n│ ├── code-limited-top-functions.ts\n│ ├── code-must-use-result.ts\n│ ├── code-must-use-super-dispose.ts\n│ ├── code-no-accessor-after-await.ts\n│ ├── code-no-any-casts.ts\n│ ├── code-no-dangerous-type-assertions.ts\n│ ├── code-no-declare-const-enum.ts\n│ ├── code-no-deep-import-of-internal.ts\n│ ├── code-no-direct-gulp-import.ts\n│ ├── code-no-global-document-listener.ts\n│ ├── code-no-http-import.ts\n│ ├── code-no-icons-in-localized-strings.ts\n│ ├── code-no-in-operator.ts\n│ ├── code-no-localization-template-literals.ts\n│ ├── code-no-localized-model-description.ts\n│ ├── code-no-new-javascript-files.ts\n│ ├── code-no-nls-in-standalone-editor.ts\n│ ├── code-no-observable-get-in-reactive-context.ts\n│ ├── code-no-potentially-unsafe-disposables.ts\n│ ├── code-no-reader-after-await.ts\n│ ├── code-no-runtime-import.ts\n│ ├── code-no-standalone-editor.ts\n│ ├── code-no-static-node-module-import.ts\n│ ├── code-no-static-self-ref.ts\n│ ├── code-no-telemetry-common-property.ts\n│ ├── code-no-test-async-suite.ts\n│ ├── code-no-test-only.ts\n│ ├── code-no-unexternalized-strings.ts\n│ ├── code-no-untyped-meta-access.ts\n│ ├── code-no-unused-expressions.ts\n│ ├── code-parameter-properties-must-have-explicit-accessibility.ts\n│ ├── code-policy-localization-key-match.ts\n│ ├── code-translation-remind.ts\n│ ├── index.ts\n│ ├── package.json\n│ ├── README.md\n│ ├── tsconfig.json\n│ ├── utils.ts\n│ ├── vscode-dts-cancellation.ts\n│ ├── vscode-dts-create-func.ts\n│ ├── vscode-dts-event-naming.ts\n│ ├── vscode-dts-interface-naming.ts\n│ ├── vscode-dts-literal-or-types.ts\n│ ├── vscode-dts-provider-naming.ts\n│ ├── vscode-dts-string-type-literals.ts\n│ ├── vscode-dts-use-export.ts\n│ ├── vscode-dts-use-thenable.ts\n│ └── vscode-dts-vscode-in-comments.ts\n├── .github\n│ ├── actions\n│ │ ├── restore-node-modules\n│ │ │ └── action.yml\n│ │ └── save-node-modules\n│ │ └── action.yml\n│ ├── agents\n│ │ ├── data.md\n│ │ ├── demonstrate.md\n│ │ └── sessions.md\n│ ├── commands\n│ │ └── codespaces_issue.yml\n│ ├── endgame\n│ │ └── insiders.yml\n│ ├── instructions\n│ │ ├── resources\n│ │ │ ├── interactive\n│ │ │ │ ├── interactive.editor.drawio.svg\n│ │ │ │ ├── interactive.eh.drawio.svg\n│ │ │ │ └── interactive.model.resolution.drawio.svg\n│ │ │ └── notebook\n│ │ │ ├── cell-resize-above-viewport.drawio.svg\n│ │ │ ├── hybrid-find.drawio.svg\n│ │ │ └── viewport-rendering.drawio.svg\n│ │ ├── accessibility.instructions.md\n│ │ ├── agentHostTesting.instructions.md\n│ │ ├── ai-customization.instructions.md\n│ │ ├── best-practices.instructions.md\n│ │ ├── buildNext.instructions.md\n│ │ ├── chat.instructions.md\n│ │ ├── coding-guidelines.instructions.md\n│ │ ├── committing.instructions.md\n│ │ ├── design-philosophy.instructions.md\n│ │ ├── design-tokens.instructions.md\n│ │ ├── disposable.instructions.md\n│ │ ├── interactive.instructions.md\n│ │ ├── kusto.instructions.md\n│ │ ├── learnings.instructions.md\n│ │ ├── notebook.instructions.md\n│ │ ├── observables.instructions.md\n│ │ ├── oss-third-party-notices.instructions.md\n│ │ ├── oss.instructions.md\n│ │ ├── sessions.instructions.md\n\nREADME 摘录:\n# Visual Studio Code - Open Source (\"Code - OSS\")\n[](https://github.com/microsoft/vscode/issues?q=is%3Aopen+is%3Aissue+label%3Afeature-request+sort%3Areactions-%2B1-desc)\n[](https://github.com/microsoft/vscode/issues?utf8=✓&q=is%3Aissue+is%3Aopen+label%3Abug)\n[](https://gitter.im/Microsoft/vscode)\n\n## The Repository\n\nThis repository (\"`Code - OSS`\") is where we (Microsoft) develop the [Visual Studio Code](https://code.visualstudio.com) product together with the community. Not only do we work on code and issues here, but we also publish our [roadmap](https://github.com/microsoft/vscode/wiki/Roadmap), [monthly iteration plans](https://github.com/microsoft/vscode/wiki/Iteration-Plans), and our [endgame plans](https://github.com/microsoft/vscode/wiki/Running-the-Endgame). This source code is available to everyone under the standard [MIT license](https://github.com/microsoft/vscode/blob/main/LICENSE.txt).\n\n## Visual Studio Code\n\n<p align=\"center\">\n\n</p>\n\n[Visual Studio Code](https://code.visualstudio.com) is a distribution of the `Code - OSS` repository with Microsoft-specific customizations released under a traditional [Microsoft product license](https://code.visualstudio.com/License/).\n\n[Visual Studio Code](https://code.visualstudio.com) combines the simplicity of a code editor with what developers need for their core edit-build-debug cycle. It provides comprehensive code editing, navigation, and understanding support along with lightweight debugging, a rich extensibility model, and lightweight integration with existing tools.\n\nVisual Studio Code is updated monthly with new features and bug fixes. You can download it for Windows, macOS, and Linux on [Visual Studio Code's website](https://code.visualstudio.com/Download). To get the latest releases every day, install the [Insiders build](https://code.visualstudio.com/insiders).\n\n## Contributing\n\nThere are many ways in which you can participate in this project, for example:\n\n* [Submit bugs and feature requests](https://github.com/microsoft/vscode/issues), and help us verify as they are checked in\n* Review [source code changes](https://github.com/microsoft/vscode/pulls)\n* Review the [documentation](https://github.com/microsoft/vscode-docs) and make pull requests for anything from typos to new content.\n\nIf you are interested in fixing issues and contributing directly to the code base,\nplease see the document [How to Contribute](https://github.com/microsoft/vscode/wiki/How-to-Contribute), which covers the following:\n\n* [How to build and run from source](https://github.com/microsoft/vscode/wiki/How-to-Contribute)\n* [The development workflow, including debugging and running tests](https://github.com/microsoft/vscode/wiki/How-to-Contribute#debugging)\n* [Coding guidelines](https://github.com/microsoft/vscode/wiki/Coding-Guidelines)\n* [Submitting pull requests](https://github.com/microsoft/vscode/wiki/How-to-Contribute#pull-requests)\n* [Finding an issue to work on](https://github.com/microsoft/vscode/wiki/How-to-Contribute#where-to-contribute)\n* [Contributing to translations](https://aka.ms/vscodeloc)\n\n## Feedback\n\n* Ask a question on [Stack Overflow](https://stackoverflow.com/questions/tagged/vscode)\n* [Request a new feature](CONTRIBUTING.md)\n* Upvote [popular feature requests](https://github.com/microsoft/vscode/issues?q=is%3Aopen+is%3Aissue+label%3Afeature-request+sort%3Areactions-%2B1-desc)\n* [File an issue](https://github.com/microsoft/vscode/issues)\n* Connect with the extension author community on [GitHub Discussions](https://github.com/microsoft/vscode-discussions/discussions) or [Slack](https://aka.ms/vscode-dev-community)\n* Follow [@code](https://x.com/code) and let us know what you think!\n\nSee our [wiki](https://github.com/microsoft/vscode/wiki/Feedback-Channels) for a description of each of these channels and information on some other available community-driven channels.\n\n## Related Projects\n\nMany of the core components and extensions to VS Code live in their own repositories on GitHub. For example, the [node debug adapter](https://github.com/microsoft/vscode-node-debug) and the [mono debug adapter](https://github.com/microsoft/vscode-mono-debug) repositories are separate from each other. For a complete list, please visit the [Related Projects](https://github.com/microsoft/vscode/wiki/Related-Projects) page on our [wiki](https://github.com/microsoft/vscode/wiki).\n\n## Bundled Extensions\n\nVS Code includes a set of built-in extensions located in the [extensions](extensions) folder, including grammars and snippets for many languages. Extensions that provide rich language support (inline suggestions, Go to Definition) for a language have the suffix `language-features`. For example, the `json` extension provides coloring for `JSON` and the `json-language-features` extension provides rich language support for `JSON`.\n\n## Development Container\n\nThis repository includes a Visual Studio Code Dev Containers / GitHub Codespaces development container.\n\n* For [Dev Containers](https://aka.ms/vscode-remote/download/containers), use the **Dev Containers: Clone Repository in Container Volume...** command which creates a Docker volume for better disk I/O on macOS and Windows.\n * If you already have VS Code and Docker installed, you can also click [here](https://vscode.dev/redirect?url=vscode://ms-vscode-remote.remote-containers/cloneInVolume?url=https://github.com/microsoft/vscode) to get started. This will cause VS Code to automatically install the Dev Containers extension if needed, clone the source code into a container volume, and spin up a dev container for use.\n\n* For Codespaces, install the [GitHub Codespaces](https://marketplace.visualstudio.com/items?itemName=GitHub.codespaces) extension in VS Code, and use the **Codespaces: Create New Codespace** command.\n\nDocker / the Codespace should have at least **4 cores and 6 GB of RAM (8 GB recommended)** to run a full build. See the [development container README](.devcontainer/README.md) for more information.\n\n## Code of Conduct\n\nThis project has adopted the [Microsoft Open Source Code of Conduct](https://opensource.microsoft.com/codeofconduct/). For more information see the [Code of Conduct FAQ](https://opensource.microsoft.com/codeofconduct/faq/) or contact [opencode@microsoft.com](mailto:opencode@microsoft.com) with any additional questions or comments.\n\n## License\n\nCopyright (c) Microsoft Corporation. All rights reserved.\n\nLicensed under the [MIT](LICENSE.txt) license.\n"
"content":"请基于下面的 GitHub 仓库信息,提取结构化知识点。\n\n目标要求:\n1. 判断仓库类别,例如深度学习框架、Web 框架、LLM 应用框架、开发工具、数据平台等。\n2. 总结仓库的核心定位和学习价值。\n3. 提炼 5 到 8 个值得学习的知识点,每个知识点都要附带来源证据。\n4. 给出建议的前置知识和学习路径。\n5. 标出最值得关注的目录。\n\n仓库名称:pytorch\n仓库链接:https://github.com/pytorch/pytorch\n主要语言:Python\nStars:101788\n最近更新时间:2026-07-13T08:07:53Z\nmain_features:[\"Tensor computation (like NumPy) with strong GPU acceleration\", \"Deep neural networks built on a tape-based autograd system\", \"A replacement for NumPy to use the power of GPUs\", \"A deep learning research platform that provides maximum flexibility and speed\"]\nmetadata:{\"owner\": \"pytorch\", \"default_branch\": \"main\", \"topics\": [\"autograd\", \"deep-learning\", \"gpu\", \"machine-learning\", \"neural-network\", \"numpy\", \"python\", \"tensor\"]}\n\n目录结构摘录:\n├── .ci\n│ ├── caffe2\n│ │ ├── common.sh\n│ │ ├── README.md\n│ │ └── test.sh\n│ ├── docker\n│ │ ├── almalinux\n│ │ │ ├── build.sh\n│ │ │ └── Dockerfile\n│ │ ├── ci_commit_pins\n│ │ │ ├── executorch.txt\n│ │ │ ├── halide.txt\n│ │ │ ├── huggingface-requirements.txt\n│ │ │ ├── jax.txt\n│ │ │ ├── nccl-cu126.txt\n│ │ │ ├── nccl.txt\n│ │ │ ├── rocm-composable-kernel.txt\n│ │ │ ├── rocm-origami.txt\n│ │ │ ├── timm.txt\n│ │ │ ├── torchbench.txt\n│ │ │ ├── triton-cpu.txt\n│ │ │ ├── triton-xpu.txt\n│ │ │ └── triton.txt\n│ │ ├── common\n│ │ │ ├── cache_vision_models.sh\n│ │ │ ├── common_utils.sh\n│ │ │ ├── install_acl.sh\n│ │ │ ├── install_amdsmi.sh\n│ │ │ ├── install_base.sh\n│ │ │ ├── install_cache.sh\n│ │ │ ├── install_clang.sh\n│ │ │ ├── install_conda.sh\n│ │ │ ├── install_conda_docker.sh\n│ │ │ ├── install_cpython.sh\n│ │ │ ├── install_cuda.sh\n│ │ │ ├── install_cudss.sh\n│ │ │ ├── install_cusparselt.sh\n│ │ │ ├── install_docs_reqs.sh\n│ │ │ ├── install_executorch.sh\n│ │ │ ├── install_gcc.sh\n│ │ │ ├── install_halide.sh\n│ │ │ ├── install_inductor_benchmark_deps.sh\n│ │ │ ├── install_jax.sh\n│ │ │ ├── install_jni.sh\n│ │ │ ├── install_lcov.sh\n│ │ │ ├── install_libgomp.sh\n│ │ │ ├── install_libpng.sh\n│ │ │ ├── install_linter.sh\n│ │ │ ├── install_magma.sh\n│ │ │ ├── install_magma_conda.sh\n│ │ │ ├── install_mingw.sh\n│ │ │ ├── install_miopen.sh\n│ │ │ ├── install_mkl.sh\n│ │ │ ├── install_mnist.sh\n│ │ │ ├── install_nccl.sh\n│ │ │ ├── install_nvpl.sh\n│ │ │ ├── install_onnx.sh\n│ │ │ ├── install_openblas.sh\n│ │ │ ├── install_openmpi.sh\n│ │ │ ├── install_patchelf.sh\n│ │ │ ├── install_python.sh\n│ │ │ ├── install_rocm.sh\n│ │ │ ├── install_rocm_drm.sh\n│ │ │ ├── install_rocm_magma.sh\n│ │ │ ├── install_rocSHMEM.sh\n│ │ │ ├── install_torch_tpu.sh\n│ │ │ ├── install_triton.sh\n│ │ │ ├── install_user.sh\n│ │ │ ├── install_xpu.sh\n│ │ │ ├── patch_libstdc.sh\n│ │ │ └── requirements_tpu.txt\n│ │ ├── java\n│ │ │ └── jni.h\n│ │ ├── linter\n│ │ │ └── Dockerfile\n│ │ ├── linter-cuda\n│ │ │ └── Dockerfile\n│ │ ├── manywheel\n│ │ │ ├── s390_scripts\n│ │ │ │ ├── build.sh\n│ │ │ │ └── build_utils.sh\n│ │ │ ├── build.sh\n│ │ │ ├── Dockerfile_2_28\n│ │ │ ├── Dockerfile_2_28_aarch64\n│ │ │ ├── Dockerfile_cuda_aarch64\n│ │ │ └── Dockerfile_s390x\n│ │ ├── ubuntu\n│ │ │ └── Dockerfile\n│ │ ├── ubuntu-cross-riscv\n│ │ │ └── Dockerfile\n│ │ ├── ubuntu-rocm\n│ │ │ ├── .gitignore\n│ │ │ └── Dockerfile\n│ │ ├── ubuntu-xpu\n│ │ │ └── Dockerfile\n│ │ ├── build.sh\n│ │ ├── README.md\n│ │ ├── requirements-ci.txt\n│ │ ├── requirements-docs.txt\n│ │ ├── triton_version.txt\n│ │ └── triton_xpu_version.txt\n│ ├── flash-attention\n│ │ └── build.sh\n│ ├── libtorch\n│ │ ├── build.sh\n│ │ └── extract_libtorch_from_wheel.py\n│ ├── lumen_cli\n│ │ ├── cli\n│ │ │ ├── build_cli\n│ │ │ │ ├── __init__.py\n│ │ │ │ └── register_build.py\n│ │ │ ├── lib\n│ │ │ │ ├── common\n│ │ │ │ │ ├── cli_helper.py\n│ │ │ │ │ ├── docker_helper.py\n│ │ │ │ │ ├── envs_helper.py\n│ │ │ │ │ ├── gh_summary.py\n│ │ │ │ │ ├── git_helper.py\n│ │ │ │ │ ├── logger.py\n│ │ │ │ │ ├── path_helper.py\n\nREADME 摘录:\n--------------------------------------------------------------------------------\n\nPyTorch is a Python package that provides two high-level features:\n- Tensor computation (like NumPy) with strong GPU acceleration\n- Deep neural networks built on a tape-based autograd system\n\nYou can reuse your favorite Python packages such as NumPy, SciPy, and Cython to extend PyTorch when needed.\n\nOur trunk health (Continuous Integration signals) can be found at [hud.pytorch.org](https://hud.pytorch.org/ci/pytorch/pytorch/main).\n\n<!-- toc -->\n\n- [More About PyTorch](#more-about-pytorch)\n - [A GPU-Ready Tensor Library](#a-gpu-ready-tensor-library)\n - [Dynamic Neural Networks: Tape-Based Autograd](#dynamic-neural-networks-tape-based-autograd)\n - [Python First](#python-first)\n - [Imperative Experiences](#imperative-experiences)\n - [Fast and Lean](#fast-and-lean)\n - [Extensions Without Pain](#extensions-without-pain)\n- [Installation](#installation)\n - [Binaries](#binaries)\n - [NVIDIA Jetson Platforms](#nvidia-jetson-platforms)\n - [From Source](#from-source)\n - [Prerequisites](#prerequisites)\n - [NVIDIA CUDA Support](#nvidia-cuda-support)\n - [AMD ROCm Support](#amd-rocm-support)\n - [Intel GPU Support](#intel-gpu-support)\n - [Get the PyTorch Source](#get-the-pytorch-source)\n - [Install Dependencies](#install-dependencies)\n - [Install PyTorch](#install-pytorch)\n - [Adjust Build Options (Optional)](#adjust-build-options-optional)\n - [Docker Image](#docker-image)\n - [Using pre-built images](#using-pre-built-images)\n - [Building the image yourself](#building-the-image-yourself)\n - [Building the Documentation](#building-the-documentation)\n - [Troubleshooting CI Errors](#troubleshooting-ci-errors)\n - [Building a PDF](#building-a-pdf)\n - [Previous Versions](#previous-versions)\n- [Getting Started](#getting-started)\n- [Resources](#resources)\n- [Communication](#communication)\n- [Releases and Contributing](#releases-and-contributing)\n- [The Team](#the-team)\n- [License](#license)\n\n<!-- tocstop -->\n\n## More About PyTorch\n\n[Learn the basics of PyTorch](https://pytorch.org/tutorials/beginner/basics/intro.html)\n\nAt a granular level, PyTorch is a library that consists of the following components:\n\n| Component | Description |\n| ---- | --- |\n| [**torch**](https://pytorch.org/docs/stable/torch.html) | A Tensor library like NumPy, with strong GPU support |\n| [**torch.autograd**](https://pytorch.org/docs/stable/autograd.html) | A tape-based automatic differentiation library that supports all differentiable Tensor operations in torch |\n| [**torch.jit**](https://pytorch.org/docs/stable/jit.html) | A compilation stack (TorchScript) to create serializable and optimizable models from PyTorch code |\n| [**torch.nn**](https://pytorch.org/docs/stable/nn.html) | A neural networks library deeply integrated with autograd designed for maximum flexibility |\n| [**torch.multiprocessing**](https://pytorch.org/docs/stable/multiprocessing.html) | Python multiprocessing, but with magical memory sharing of torch Tensors across processes. Useful for data loading and Hogwild training |\n| [**torch.utils**](https://pytorch.org/docs/stable/data.html) | DataLoader and other utility functions for convenience |\n\nUsually, PyTorch is used either as:\n\n- A replacement for NumPy to use the power of GPUs.\n- A deep learning research platform that provides maximum flexibility and speed.\n\nElaborating Further:\n\n### A GPU-Ready Tensor Library\n\nIf you use NumPy, then you have used Tensors (a.k.a. ndarray).\n\nPyTorch provides Tensors that can live either on the CPU or the GPU and accelerates the\ncomputation by a huge amount.\n\nWe provide a wide variety of tensor routines to accelerate and fit your scientific computation needs\nsuch as slicing, indexing, mathematical operations, linear algebra, reductions.\nAnd they are fast!\n\n### Dynamic Neural Networks: Tape-Based Autograd\n\nPyTorch has a unique way of building neural networks: using and replaying a tape recorder.\n\nMost frameworks such as TensorFlow, Theano, Caffe, and CNTK have a static view of the world.\nOne has to build a neural network and reuse the same structure again and again.\nChanging the way the network behaves means that one has to start from scratch.\n\nWith PyTorch, we use a technique called reverse-mode auto-differentiation, which allows you to\nchange the way your network behaves arbitrarily with zero lag or overhead. Our inspiration comes\nfrom several research papers on this topic, as well as current and past work such as\n[torch-autograd](https://github.com/twitter/torch-autograd),\n[autograd](https://github.com/HIPS/autograd),\n[Chainer](https://chainer.org), etc.\n\nWhile this technique is not unique to PyTorch, it's one of the fastest implementations of it to date.\nYou get the best of speed and flexibility for your crazy research.\n\n### Python First\n\nPyTorch is not a Python binding into a monolithic C++ framework.\nIt is built to be deeply integrated into Python.\nYou can use it naturally like you would use [NumPy](https://www.numpy.org/) / [SciPy](https://www.scipy.org/) / [scikit-learn](https://scikit-learn.org) etc.\nYou can write your new neural network layers in Python itself, using your favorite libraries\nand use packages such as [Cython](https://cython.org/) and [Numba](http://numba.pydata.org/).\nOur goal is to not reinvent the wheel where appropriate.\n\n### Imperative Experiences\n\nPyTorch is designed to be intuitive, linear in thought, and easy to use.\nWhen you execute a line of code, it gets executed. There isn't an asynchronous view of the world.\nWhen you drop into a debugger or receive error messages and stack traces, understanding them is straightforward.\nThe stack trace points to exactly where your code was defined.\nWe hope you never spend hours debugging your code because of bad stack traces or asynchronous and opaque execution engines.\n\n### Fast and Lean\n\nPyTorch has minimal framework overhead. We integrate acceleration libraries\nsuch as [Intel MKL](https://software.intel.com/mkl) and NVIDIA ([cuDNN](https://developer.nvidia.com/cudnn), [NCCL](https://developer.nvidia.com/nccl)) to maximize speed.\nAt the core, its CPU and GPU Tensor and neural network backends\nare mature and have been tested for years.\n\nHence, PyTorch is quite fast — whether you run small or large neural networks.\n\nThe memory usage in PyTorch is extremely efficient compared to Torch or some of the alternatives.\nWe've written custom memory allocators for the GPU to make sure that\nyour deep learning models are maximally memory efficient.\nThis enables you to train bigger deep learning models than before.\n\n### Extensions Without Pain\n\nWriting new neural network modules, or interfacing with PyTorch's Tensor API, was designed to be straightforward\nand with minimal abstractions.\n\nYou can write new neural network layers in Python using the torch API\n[or your favorite NumPy-based libraries such as SciPy](https://pytorch.org/tutorials/advanced/numpy_extensions_tutorial.html).\n\nIf you want to write your layers in C/C++, we provide a convenient extension API that is efficient and with minimal boilerplate.\nNo wrapper code needs to be written. You can see [a tutorial here](https://pytorch.org/tutorials/advanced/cpp_extension.html) and [an example here](https://github.com/pytorch/extension-cpp).\n\n## Installation\n\n### Binaries\nCommands to install binaries via Conda or pip wheels are on our website: [https://pytorch.org/get-started/locally/](https://pytorch.org/get-started/locally/)\n\n#### NVIDIA Jetson Platforms\n\nPython wheels for NVIDIA's Jetson Nano, Jetson TX1/TX2, Jetson Xavier NX/AGX, and Jetson AGX Orin are provided [here](https://forums.developer.nvidia.com/t/pytorch-for-jetson-version-1-10-now-available/72048) and the L4T container is published [here](https://catalog.ngc.nvidia.com/orgs/nvidia/containers/l4t-pytorch)\n\nThey require JetPack 4.2 and above, and [@dusty-nv](https://github.com/dusty-nv) and [@ptrblck](https://github.com/ptrblck) are maintaining them.\n\n### From Source\n\n#### Prerequisites\nIf you are installing from source, you will need:\n- Python 3.10 or later\n- A compiler that fully supports C++20, such as clang or gcc (gcc 11.3.0 or newer is required, on Linux)\n- Visual Studio or Visual Studio Build Tool (Windows only)\n- At least 10 GB of free disk space\n- 30-60 minutes for the initial build (subsequent rebuilds are much faster)\n\n\\* PyTorch CI uses Visual C++ BuildTools, which come with Visual Studio Enterprise,\nProfessional, or Community Editions. You can also install the build tools from\nhttps://visualstudio.microsoft.com/visual-cpp-build-tools/. The build tools *do not*\ncome with Visual Studio Code by default.\n\nAn example of environment setup is shown below:\n\n* Linux:\n\n* Windows:\n\nA conda environment is not required. You can also do a PyTorch build in a\nstandard virtual environment, e.g., created with tools like `uv`, provided\nyour system has installed all the necessary dependencies unavailable as pip\npackages (e.g., CUDA, MKL.)\n\n##### NVIDIA CUDA Support\nIf you want to compile with CUDA support, [select a supported version of CUDA from our support matrix](https://pytorch.org/get-started/locally/), then install the following:\n- [NVIDIA CUDA](https://developer.nvidia.com/cuda-downloads)\n- [NVIDIA cuDNN](https://developer.nvidia.com/cudnn) v9.0 or above\n- [Compiler](https://gist.github.com/ax3l/9489132) compatible with CUDA\n\nNote: You could refer to the [cuDNN Support Matrix](https://docs.nvidia.com/deeplearning/cudnn/backend/latest/reference/support-matrix.html) for cuDNN versions with the various supported CUDA, CUDA driver, and NVIDIA hardware.\n\nIf you want to disable CUDA support, export the environment variable `USE_CUDA=0`.\nOther potentially useful environment variables may be found in `setup.py`. If\nCUDA is installed in a non-standard location, set PATH so that the nvcc you\nwant to use can be found (e.g., `export PATH=/usr/local/cuda-12.8/bin:$PATH`).\n\nIf you are building for NVIDIA's Jetson platforms (Jetson Nano, TX1, TX2, AGX Xavier), Instructions to install PyTorch for Jetson Nano are [available here](https://devtalk.nvidia.com/default/topic/1049071/jetson-nano/pytorch-for-jetson-nano/)\n\n##### AMD ROCm Support\nIf you want to compile with ROCm support, install\n- [AMD ROCm](https://rocm.docs.amd.com/en/latest/deploy/linux/quick_start.html) 4.0 and above installation\n- ROCm is currently supported only for Linux systems.\n\nBy default the build system expects ROCm to be installed in `/opt/rocm`. If ROCm is installed in a different directory, the `ROCM_PATH` environment variable must be set to the ROCm installation directory. The build system automatically detects the AMD GPU architecture. Optionally, the AMD GPU architecture can be explicitly set with the `PYTORCH_ROCM_ARCH` environment variable [AMD GPU architecture](https://rocm.docs.amd.com/projects/install-on-linux/en/latest/reference/system-requirements.html#supported-gpus)\n\nIf you want to disable ROCm support, export the environment variable `USE_ROCM=0`.\nOther potentially useful environment variables may be found in `setup.py`.\n\n##### Intel GPU Support\nIf you want to compile with Intel GPU support, follow these\n- [PyTorch Prerequisites for Intel GPUs](https://www.intel.com/content/www/us/en/developer/articles/tool/pytorch-prerequisites-for-intel-gpu.html) instructions.\n- Intel GPU is supported for Linux and Windows.\n\nIf you want to disable Intel GPU support, export the environment variable `USE_XPU=0`.\nOther potentially useful environment variables may be found in `setup.py`.\n\n#### Get the PyTorch Source\n\n#### Install Dependencies\n\n**Common**\n\n**On Linux**\n\n**On Windows**\n\n#### Install PyTorch\n\n**On Linux**\n\nIf you're compiling for AMD ROCm then first run this command:\n\nInstall PyTorch\n\n**On macOS**\n\n**On Windows**\n\nIf you want to build legacy python code, please refer to [Building on legacy code and CUDA](https://github.com/pytorch/pytorch/blob/main/CONTRIBUTING.md#building-on-legacy-code-and-cud\n"
"content":"请基于下面的 GitHub 仓库信息,提取结构化知识点。\n\n目标要求:\n1. 判断仓库类别,例如深度学习框架、Web 框架、LLM 应用框架、开发工具、数据平台等。\n2. 总结仓库的核心定位和学习价值。\n3. 提炼 5 到 8 个值得学习的知识点,每个知识点都要附带来源证据。\n4. 给出建议的前置知识和学习路径。\n5. 标出最值得关注的目录。\n\n仓库名称:llama_index\n仓库链接:https://github.com/run-llama/llama_index\n主要语言:Python\nStars:50809\n最近更新时间:2026-07-13T07:49:18Z\nmain_features:[\"🚀 Overview\", \"💡 Contributing\", \"📄 Documentation\", \"💻 Example Usage\", \"A note on Verification of Build Assets\", \"📖 Citation\"]\nmetadata:{\"owner\": \"run-llama\", \"default_branch\": \"main\", \"topics\": [\"agents\", \"application\", \"data\", \"fine-tuning\", \"framework\", \"llamaindex\", \"llm\", \"multi-agents\", \"rag\", \"vector-database\"]}\n\n目录结构摘录:\n├── .github\n│ ├── ISSUE_TEMPLATE\n│ │ ├── config.yml\n│ │ ├── docs-form.yml\n│ │ ├── feature-form.yml\n│ │ ├── issue-form.yml\n│ │ └── question-form.yml\n│ ├── workflows\n│ │ ├── build_package.yml\n│ │ ├── close_new_integration_prs.yml\n│ │ ├── codeql.yml\n│ │ ├── core-typecheck.yml\n│ │ ├── coverage_check.yml\n│ │ ├── issue_classifier.yml\n│ │ ├── lint.yml\n│ │ ├── llama_dev_tests.yml\n│ │ ├── pre_release.yml\n│ │ ├── publish_sub_package.yml\n│ │ ├── release.yml\n│ │ ├── stale_bot.yml\n│ │ ├── sync-docs.yml\n│ │ └── unit_test.yml\n│ ├── dependabot.yml\n│ └── pull_request_template.md\n├── docs\n│ ├── api_reference\n│ │ ├── api_reference\n│ │ │ ├── _static\n│ │ │ │ └── assets\n│ │ │ │ ├── LlamaLogoBrowserTab.png\n│ │ │ │ └── LlamaSquareBlack.svg\n│ │ │ ├── agent\n│ │ │ │ └── index.md\n│ │ │ ├── callbacks\n│ │ │ │ ├── agentops.md\n│ │ │ │ ├── aim.md\n│ │ │ │ ├── argilla.md\n│ │ │ │ ├── arize_phoenix.md\n│ │ │ │ ├── honeyhive.md\n│ │ │ │ ├── index.md\n│ │ │ │ ├── langfuse.md\n│ │ │ │ ├── literalai.md\n│ │ │ │ ├── llama_debug.md\n│ │ │ │ ├── openinference.md\n│ │ │ │ ├── opik.md\n│ │ │ │ ├── promptlayer.md\n│ │ │ │ ├── token_counter.md\n│ │ │ │ ├── uptrain.md\n│ │ │ │ └── wandb.md\n│ │ │ ├── chat_engines\n│ │ │ │ ├── condense_plus_context.md\n│ │ │ │ ├── condense_question.md\n│ │ │ │ ├── context.md\n│ │ │ │ ├── index.md\n│ │ │ │ └── simple.md\n│ │ │ ├── embeddings\n│ │ │ │ ├── adapter.md\n│ │ │ │ ├── alephalpha.md\n│ │ │ │ ├── alibabacloud_aisearch.md\n│ │ │ │ ├── anyscale.md\n│ │ │ │ ├── autoembeddings.md\n│ │ │ │ ├── azure_inference.md\n│ │ │ │ ├── azure_openai.md\n│ │ │ │ ├── baseten.md\n│ │ │ │ ├── bedrock.md\n│ │ │ │ ├── clarifai.md\n│ │ │ │ ├── clip.md\n│ │ │ │ ├── cloudflare_workersai.md\n│ │ │ │ ├── cohere.md\n│ │ │ │ ├── dashscope.md\n│ │ │ │ ├── databricks.md\n│ │ │ │ ├── deepinfra.md\n│ │ │ │ ├── elasticsearch.md\n│ │ │ │ ├── fastembed.md\n│ │ │ │ ├── fireworks.md\n│ │ │ │ ├── gaudi.md\n│ │ │ │ ├── gigachat.md\n│ │ │ │ ├── google_genai.md\n│ │ │ │ ├── heroku.md\n│ │ │ │ ├── huggingface.md\n│ │ │ │ ├── huggingface_api.md\n│ │ │ │ ├── huggingface_openvino.md\n│ │ │ │ ├── huggingface_optimum.md\n│ │ │ │ ├── huggingface_optimum_intel.md\n│ │ │ │ ├── ibm.md\n│ │ │ │ ├── index.md\n│ │ │ │ ├── instructor.md\n│ │ │ │ ├── ipex_llm.md\n│ │ │ │ ├── isaacus.md\n│ │ │ │ ├── jinaai.md\n│ │ │ │ ├── langchain.md\n│ │ │ │ ├── litellm.md\n│ │ │ │ ├── llamafile.md\n│ │ │ │ ├── llm_rails.md\n│ │ │ │ ├── mistralai.md\n│ │ │ │ ├── mixedbreadai.md\n│ │ │ │ ├── modelscope.md\n│ │ │ │ ├── nebius.md\n│ │ │ │ ├── netmind.md\n│ │ │ │ ├── nomic.md\n│ │ │ │ ├── nvidia.md\n│ │ │ │ ├── oci_data_science.md\n│ │ │ │ ├── oci_genai.md\n│ │ │ │ ├── ollama.md\n│ │ │ │ ├── opea.md\n│ │ │ │ ├── openai.md\n│ │ │ │ ├── openai_like.md\n│ │ │ │ ├── openvino_genai.md\n│ │ │ │ ├── oracleai.md\n│ │ │ │ ├── premai.md\n│ │ │ │ ├── sagemaker_endpoint.md\n│ │ │ │ ├── siliconflow.md\n│ │ │ │ ├── text_embeddings_inference.md\n│ │ │ │ ├── textembed.md\n│ │ │ │ ├── together.md\n│ │ │ │ ├── upstage.md\n│ │ │ │ ├── vertex.md\n│ │ │ │ ├── vertex_endpoint.md\n│ │ │ │ ├── vllm.md\n│ │ │ │ ├── voyageai.md\n\nREADME 摘录:\n# 🗂️ LlamaIndex 🦙\n\n[](https://pypi.org/project/llama-index/)\n[](https://github.com/run-llama/llama_index/actions/workflows/build_package.yml)\n[](https://github.com/jerryjliu/llama_index/graphs/contributors)\n[](https://discord.gg/dGcwcsnxhU)\n[](https://x.com/llama_index)\n[](https://www.reddit.com/r/LlamaIndex/)\n[](https://www.phorm.ai/query?projectId=c5863b56-6703-4a5d-87b6-7e6031bf16b6)\n\nLlamaIndex OSS (by [LlamaIndex](https://llamaindex.ai?utm_medium=li_github&utm_source=github&utm_campaign=2026--)) is an open-source framework to build agentic applications. **[Parse](https://cloud.llamaindex.ai?utm_medium=li_github&utm_source=github&utm_campaign=2026--)** is our enterprise platform for agentic OCR, parsing, extraction, indexing and more. You can use LlamaParse with this framework or on its own; see [LlamaParse](#llamacloud-document-agent-platform) below for signup and product links.\n\n> ### 📚 **Documentation:**\n>\n> - [LlamaParse](https://developers.llamaindex.ai/python/cloud/llamaparse/?utm_medium=li_github&utm_source=github&utm_campaign=2026--)\n> - [LlamaIndex OSS](https://developers.llamaindex.ai/python/framework/?utm_medium=li_github&utm_source=github&utm_campaign=2026--)\n> - [LlamaAgents](https://developers.llamaindex.ai/python/llamaagents/overview/?utm_medium=li_github&utm_source=github&utm_campaign=2026--)\n\nBuilding with LlamaIndex typically involves working with LlamaIndex core and a chosen set of integrations (or plugins). There are two ways to start building with LlamaIndex in\nPython:\n\n1. **Starter**: [`llama-index`](https://pypi.org/project/llama-index/). A starter Python package that includes core LlamaIndex as well as a selection of integrations.\n\n2. **Customized**: [`llama-index-core`](https://pypi.org/project/llama-index-core/). Install core LlamaIndex and add your chosen LlamaIndex integration packages on [LlamaHub](https://llamahub.ai/)\n that are required for your application. There are over 300 LlamaIndex integration\n packages that work seamlessly with core, allowing you to build with your preferred\n LLM, embedding, and vector store providers.\n\nThe LlamaIndex Python library is namespaced such that import statements which\ninclude `core` imply that the core package is being used. In contrast, those\nstatements without `core` imply that an integration package is being used.\n\n### LlamaParse (document agent platform)\n\n**LlamaParse** is its own platform—focused on document agents and agentic OCR. It includes **Parse** (parsing), **LlamaAgents** (deployed document agents), **Extract** (structured extraction), and **Index** (ingest and RAG). You can use it with the LlamaIndex framework or standalone.\n\n- **[Sign up for LlamaParse](https://cloud.llamaindex.ai?utm_medium=li_github&utm_source=github&utm_campaign=2026--)** — Create an account and get your API key.\n- **Parse** — Agentic OCR and document parsing (130+ formats). [Docs](https://developers.llamaindex.ai/python/cloud/llamaparse/?utm_medium=li_github&utm_source=github&utm_campaign=2026--)\n- **Extract** — Structured data extraction from documents. [Docs](https://developers.llamaindex.ai/python/cloud/llamaextract/?utm_medium=li_github&utm_source=github&utm_campaign=2026--)\n- **Index** — Ingest, index, and RAG pipelines. [Docs](https://developers.llamaindex.ai/python/cloud/llamacloud/?utm_medium=li_github&utm_source=github&utm_campaign=2026--)\n- **Split** — Split large documents into subcategories. [Docs](https://developers.llamaindex.ai/python/cloud/split/getting_started/?utm_medium=li_github&utm_source=github&utm_campaign=2026--)\n- **Agents** — Build end-to-end document agents with `Workflows` and Agent Builder. [Docs](https://developers.llamaindex.ai/python/llamaagents/overview/?utm_medium=li_github&utm_source=github&utm_campaign=2026--)\n\n### Important Links\n\n[Documentation](https://developers.llamaindex.ai/python/framework/?utm_medium=li_github&utm_source=github&utm_campaign=2026--)\n\n[X (formerly Twitter)](https://x.com/llama_index)\n\n[LinkedIn](https://www.linkedin.com/company/llamaindex/)\n\n[Reddit](https://www.reddit.com/r/LlamaIndex/)\n\n[Discord](https://discord.gg/dGcwcsnxhU)\n\n## 🚀 Overview\n\n**NOTE**: This README is not updated as frequently as the documentation. Please check out the documentation above for the latest updates!\n\n### Context\n\n- LLMs are a phenomenal piece of technology for knowledge generation and reasoning. They are pre-trained on large amounts of publicly available data.\n- How do we best augment LLMs with our own private data?\n\nWe need a comprehensive toolkit to help perform this data augmentation for LLMs.\n\n### Proposed Solution\n\nThat's where **LlamaIndex** comes in. LlamaIndex is a \"data framework\" to help you build LLM apps. It provides the following tools:\n\n- Offers **data connectors** to ingest your existing data sources and data formats (APIs, PDFs, docs, SQL, etc.).\n- Provides ways to **structure your data** (indices, graphs) so that this data can be easily used with LLMs.\n- Provides an **advanced retrieval/query interface over your data**: Feed in any LLM input prompt, get back retrieved context and knowledge-augmented output.\n- Allows easy integrations with your outer application framework (e.g. with LangChain, Flask, Docker, ChatGPT, or anything else).\n\nLlamaIndex provides tools for both beginner users and advanced users. Our high-level API allows beginner users to use LlamaIndex to ingest and query their data in\n5 lines of code. Our lower-level APIs allow advanced users to customize and extend any module (data connectors, indices, retrievers, query engines, reranking modules),\nto fit their needs.\n\n## 💡 Contributing\n\nInterested in contributing? Contributions to LlamaIndex core as well as contributing\nintegrations that build on the core are both accepted and highly encouraged! See our [Contribution Guide](CONTRIBUTING.md) for more details.\n\nNew integrations should meaningfully integrate with existing LlamaIndex framework components. At the discretion of LlamaIndex maintainers, some integrations may be declined.\n\n## 📄 Documentation\n\nFull documentation can be found [here](https://developers.llamaindex.ai/python/framework/?utm_medium=li_github&utm_source=github&utm_campaign=2026--)\n\nPlease check it out for the most up-to-date tutorials, how-to guides, references, and other resources!\n\n## 💻 Example Usage\n\nExamples are in the `docs/examples` folder. Indices are in the `indices` folder (see list of indices below).\n\nTo build a simple vector store index using OpenAI:\n\nTo build a simple vector store index using non-OpenAI LLMs, e.g. LLMs hosted through Ollama:\n\nTo query:\n\nBy default, data is stored in-memory.\nTo persist to disk (under `./storage`):\n\nTo reload from disk:\n\n## A note on Verification of Build Assets\n\nBy default, `llama-index-core` includes a `_static` folder that contains the nltk and tiktoken cache that is included with the package installation. This ensures that you can easily run `llama-index` in environments with restrictive disk access permissions at runtime.\n\nTo verify that these files are safe and valid, we use the github `attest-build-provenance` action. This action will verify that the files in the `_static` folder are the same as the files in the `llama-index-core/llama_index/core/_static` folder.\n\nTo verify this, you can run the following script (pointing to your installed package):\n\n## 📖 Citation\n\nReference to cite if you use LlamaIndex in a paper:\n"
"readme_text":"<!--\n Licensed to the Apache Software Foundation (ASF) under one\n or more contributor license agreements. See the NOTICE file\n distributed with this work for additional information\n regarding copyright ownership. The ASF licenses this file\n to you under the Apache License, Version 2.0 (the\n\"License\"); you may not use this file except in compliance\n with the License. You may obtain a copy of the License at\n\n http://www.apache.org/licenses/LICENSE-2.0\n\n Unless required by applicable law or agreed to in writing,\n software distributed under the License is distributed on an\n\"AS IS\" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY\n KIND, either express or implied. See the License for the\n specific language governing permissions and limitations\n under the License.\n-->\n\n<!-- START Apache Airflow, please keep comment here to allow auto update of PyPI readme.md -->\n# Apache Airflow\n\n| Category | Badges |\n|------------|--------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------|\n| License | [](https://www.apache.org/licenses/LICENSE-2.0.txt) |\n| PyPI | [](https://badge.fury.io/py/apache-airflow) [](https://pypi.org/project/apache-airflow/) [](https://pypi.org/project/apache-airflow/) |\n| Containers | [](https://hub.docker.com/r/apache/airflow) [](https://hub.docker.com/r/apache/airflow) [](https://artifacthub.io/packages/search?repo=apache-airflow) |\n| Community | [](https://github.com/apache/airflow/graphs/contributors) [](https://s.apache.org/airflow-slack)  [](https://insights.linuxfoundation.org/project/apache-airflow) |\n| Dev tools | [](https://github.com/j178/prek) |\n\n| Version | Build Status |\n|---------|-----------------------------------------------------------------------------------------------------------------------------------------------------------------|\n| Main | [](https://github.com/apache/airflow/actions/workflows/ci-amd.yml) [](https://github.com/apache/airflow/actions/workflows/ci-arm.yml) |\n| 3.x | [](https://github.com/apache/airflow/actions/workflows/ci-amd.yml) [](https://github.com/apache/airflow/actions/workflows/ci-arm.yml) |\n\n\n\n<picture width=\"500\">\n <img\n src=\"https://github.com/apache/airflow/blob/19ebcac2395ef9a6b6ded3a2faa29dc960c1e635/docs/apache-airflow/img/logos/wordmark_1.png?raw=true\"\n alt=\"Apache Airflow logo\"\n />\n</picture>\n\n[Apache Airflow](https://airflow.apache.org/docs/apache-airflow/stable/) (or simply Airflow) is a platform to programmatically author, schedule, and monitor workflows.\n\nWhen workflows are defined as code, they become more maintainable, versionable, testable, and collaborative.\n\nUse Airflow to author workflows (Dags) that orchestrate tasks. The Airflow scheduler executes your tasks on an array of workers while following the specified dependencies. Rich command line utilities make performing complex surgeries on Dags a snap. The rich user interface makes it easy to visualize pipelines running in production, monitor progress, and troubleshoot issues when needed.\n\n<!-- END Apache Airflow, please keep comment here to allow auto update of PyPI readme.md -->\n<!-- START doctoc generated TOC please keep comment here to allow auto update -->\n<!-- DON'T EDIT THIS SECTION, INSTEAD RE-RUN doctoc TO UPDATE -->\n**Table of contents**\n\n- [Project Focus](#project-focus)\n- [Principles](#principles)\n- [Requirements](#requirements)\n- [Getting started](#getting-started)\n- [Installing from PyPI](#installing-from-pypi)\n- [Installation](#installation)\n- [Official source code](#official-source-code)\n- [Convenience packages](#convenience-packages)\n- [User Interface](#user-interface)\n- [Semantic versioning](#semantic-versioning)\n- [Version Life Cycle](#version-life-cycle)\n- [Support for Python and Kubernetes versions](#support-for-python-and-kubernetes-versions)\n- [Base OS support for reference Airflow images](#base-os-support-for-reference-airflow-images)\n- [Approach to dependencies of Airflow](#approach-to-dependencies-of-airflow)\n- [Contributing](#contributing)\n- [Community standards](#community-standards)\n- [Agent-assisted contribution (apache-magpie)](#agent-assisted-contribution-apache-magpie)\n- [Voting Policy](#voting-policy)\n- [Who uses Apache Airflow?](#who-uses-apache-airflow)\n- [Who maintains Apache Airflow?](#who-maintains-apache-airflow)\n- [What goes into the next release?](#what-goes-into-the-next-release)\n- [Can I use the Apache Airflow logo in my presentation?](#can-i-use-the-apache-airflow-logo-in-my-presentation)\n- [Links](#links)\n- [Sponsors](#sponsors)\n\n<!-- END doctoc generated TOC please keep comment here to allow auto update -->\n\n## Project Focus\n\nAirflow works best with workflows that are mostly static and slowly changing. When the Dag structure is similar from one run to the next, it clarifies the unit of work and continuity. Other similar projects include [Luigi](https://github.com/spotify/luigi), [Oozie](https://oozie.apache.org/) and [Azkaban](https://azkaban.github.io/).\n\nAirflow is commonly used to process data, but has the opinion that tasks should ideally be idempotent (i.e., results of the task will be the same, and will not create duplicated data in a destination system), and should not pass large quantities of data from one task to the next (though tasks can pass metadata using Airflow's [XCom feature](https://airflow.apache.org/docs/apache-airflow/stable/concepts/xcoms.html)). For high-volume, data-intensive tasks, a best practice is to delegate to external services specializing in that type of work.\n\nAirflow is not a streaming solution, but it is often used to process real-time data, pulling data off streams in batches.\n\n## Principles\n\n- **Dynamic**: Pipelines are defined in code, enabling dynamic dag generation and parameterization.\n- **Extensible**: The Airflow framework includes a wide range of built-in operators and can be extended to fit your needs.\n- **Flexible**: Airflow leverages the [**Jinja**](https://jinja.palletsprojects.com) templating engine, allowing rich customizations.\n\n<!-- START Requirements, please keep comment here to allow auto update of PyPI readme.md -->\n## Requirements\n\nApache Airflow is tested with:\n\n| | Main version (dev) | Stable version (3.3.0) | Deprecate version (2.11.2) |\n|------------|------------------------------------|-------------------------------------|------------------------------|\n| Python | 3.10, 3.11, 3.12, 3.13, 3.14 | 3.10, 3.11, 3.12, 3.13, 3.14 | 3.10, 3.11, 3.12 |\n| Platform | AMD64/ARM64 | AMD64/ARM64 | AMD64/ARM64(\\*) |\n| Kubernetes | 1.30, 1.31, 1.32, 1.33, 1.34, 1.35 | 1.30, 1.31, 1.32, 1.33, 1.34, 1.35 | 1.26, 1.27, 1.28, 1.29, 1.30 |\n| PostgreSQL | 14, 15, 16, 17, 18 | 14, 15, 16, 17, 18 | 12, 13, 14, 15, 16 |\n| MySQL | 8.0, 8.4, Innovation | 8.0, 8.4, Innovation | 8.0, Innovation |\n| SQLite | 3.15.0+ | 3.15.0+ | 3.15.0+ |\n\n\\* Experimental\n\n**Note**: MariaDB is not tested/recommended.\n\n**Note**: SQLite is used in Airflow tests. Do not use it in production. We recommend\nusing the latest stable version of SQLite for local development.\n\n**Note**: Airflow currently can be run on POSIX-compliant Operating Systems. For development, it is regularly\ntested on fairly modern Linux Distros and recent versions of macOS.\nOn Windows you can run it via WSL2 (Windows Subsystem for Linux 2) or via Linux Containers.\nThe work to add Windows support is tracked via [#10388](https://github.com/apache/airflow/issues/10388), but\nit is not a high priority. You should only use Linux-based distros as \"Production\" execution environment\nas this is the only environment that is supported. The only distro that is used in our CI tests and that\nis used in the [Community managed DockerHub image](https://hub.docker.com/p/apache/airflow) is\n`Debian Bookworm`.\n\n<!-- END Requirements, please keep comment here to allow auto update of PyPI readme.md -->\n<!-- START Getting started, please keep comment here to allow auto update of PyPI readme.md -->\n## Getting started\n\nVisit the official Airflow website documentation (latest **stable** release) for help with\n[installing Airflow](https://airflow.apache.org/docs/apache-airflow/stable/installation/),\n[getting started](https://airflow.apache.org/docs/apache-airflow/stable/start.html), or walking\nthrough a more complete [tutorial](https://airflow.apache.org/docs/apache-airflow/stable/tutorial/).\n\n> Note: If you're looking for documentation for the main branch (latest development branch): you can find it on [s.apache.org/airflow-docs](https://s.apache.org/airflow-docs/).\n\nFor more information on Airflow Improvement Proposals (AIPs), visit\nthe [Airflow Wiki](https://cwiki.apache.org/confluence/display/AIRFLOW/Airflow+Improvement+Proposals).\n\nDocumentation for dependent projects like provider distributions, Docker image, Helm Chart, you'll find it in [the documentation index](https://airflow.apache.org/docs/).\n\n<!-- END Getting started, please keep comment here to allow auto update of PyPI readme.md -->\n<!-- START Installing from PyPI, please keep comment here to allow auto update of PyPI readme.md -->\n\n## Installing from PyPI\n\nWe publish Apache Airflow as `apache-airflow` package in PyPI. Installing it however might be sometimes tricky\nbecause Airflow is a bit of both a library and application. Libraries usually keep their dependencies open, and\napplications usually pin them, but we should do neither and both simultaneously. We decided to keep\nour dependencies as open as possible (in `pyproject.toml`) so users can install different versions of libraries\nif needed. This means that `pip install apache-airflow` will not work from time to time or will\nproduce unusable Airflow installation.\n\nTo have repeatable installation, however, we keep a set of \"known-to-be-working\" constraint\nfiles in the orphan `constraints-main` and `constraints-2-0` branches. We keep those \"known-to-be-working\"\nconstraints files separately per major/minor Python version.\nYou can use them as constraint files when installing Airflow from PyPI. Note that you have to specify\ncorrect Airflow tag/version/branch and Python versions in the URL.\n\n1. Installing just Airflow:\n\n> Note: Only `pip` installation is currently officially supported.\n\nWhile it is possible to install Airflow with tools like [Poetry](https://python-poetry.org) or\n[pip-tools](https://pypi.org/project/pip-tools), they do not share the same workflow as\n`pip` - especially when it comes to constraint vs. requirements management.\nInstalling via `Poetry` or `pip-tools` is not currently supported.\n\nIf you wish to install Airflow using those tools, you should use the constraint files and convert\nthem to the appropriate format and workflow that your tool requires.\n\n\n```bash\npip install 'apache-airflow==3.3.0' \\\n --constraint \"https://raw.githubusercontent.com/apache/airflow/constraints-3.3.0/constraints-3.10.txt\"\n```\n\n2. Installing with extras (i.e., postgres, google)\n\n```bash\npip install 'apache-airflow[postgres,google]==3.3.0' \\\n --constraint \"https://raw.githubusercontent.com/apache/airflow/constraints-3.3.0/constraints-3.10.txt\"\n```\n\nFor information on installing provider distributions, check\n[providers](http://airflow.apache.org/docs/apache-airflow-providers/index.html).\n\n<!-- END Installing from PyPI, please keep comment here to allow auto update of PyPI readme.md -->\n\n## Installation\n\nFor comprehensive instructions on setting up your local development environment and installing Apache Airflow, please refer to the [INSTALLING.md](INSTALLING.md) file.\n\n<!-- START Official source code, please keep comment here to allow auto update of PyPI readme.md -->\n## Official source code\n\nApache Airflow is an [Apache Software Foundation](https://www.apache.org) (ASF) project,\nand our official source code releases:\n\n- Follow the [ASF Release Policy](https://www.apache.org/legal/release-policy.html)\n- Can be downloaded from [the ASF Distribution Directory](https://downloads.apache.org/airflow)\n- Are cryptographically signed by the release manager\n- Are officially voted on by the PMC members during the\n [Release Approval Process](https://www.apache.org/legal/release-policy.html#release-approval)\n\nFollowing the ASF rules, the source packages released must be sufficient for a user to build and test the\nrelease provided they have access to the appropriate platform and tools.\n\n<!-- END Official source code, please keep comment here to allow auto update of PyPI readme.md -->\n## Convenience packages\n\nThere are other ways of installing and using Airflow. Those are \"convenience\" methods - they are\nnot \"official releases\" as stated by the `ASF Release Policy`, but they can be used by the users\nwho do not want to build the software themselves.\n\nThose are - in the order of most common ways people install Airflow:\n\n- [PyPI releases](https://pypi.org/project/apache-airflow/) to install Airflow using standard `pip` tool\n- [Docker Images](https://hub.docker.com/r/apache/airflow) to install airflow via\n `docker` tool, use them in Kubernetes, Helm Charts, `docker-compose`, `docker swarm`, etc. You can\n read more about using, customizing, and extending the images in the\n [Latest docs](https://airflow.apache.org/docs/docker-stack/index.html), and\n learn details on the internals in the [images](https://airflow.apache.org/docs/docker-stack/index.html) document.\n- [Tags in GitHub](https://github.com/apache/airflow/tags) to retrieve the git project sources that\n were used to generate official source packages via git\n\nAll those artifacts are not official releases, but they are prepared using officially released sources.\nSome of those artifacts are \"development\" or \"pre-release\" ones, and they are clearly marked as such\nfollowing the ASF Policy.\n\n## User Interface\n\n- **Dags**: Overview of all Dags in your environment.\n\n \n\n- **Assets**: Overview of Assets with dependencies.\n\n \n\n- **Grid**: Grid representation of a Dag that spans across time.\n\n \n\n- **Graph**: Visualization of a Dag's dependencies and their current status for a specific run.\n\n \n\n- **Home**: Summary statistics of your Airflow environment.\n\n \n\n- **Backfill**: Backfilling a Dag for a specific date range.\n\n \n\n- **Code**: Quick way to view source code of a Dag.\n\n \n\n## Semantic versioning\n\nAs of Airflow 2.0.0, we support a strict [SemVer](https://semver.org/) approach for all packages released.\n\nThere are few specific rules that we agreed to that define details of versioning of the different\npackages:\n\n* **Airflow**: SemVer rules apply to core airflow only (excludes any changes to providers).\n Changing limits for versions of Airflow dependencies is not a breaking change on its own.\n* **Airflow Providers**: SemVer rules apply to changes in the particular provider's code only.\n SemVer MAJOR and MINOR versions for the packages are independent of the Airflow version.\n For example, `google 4.1.0` and `amazon 3.1.1` providers can happily be installed\n with `Airflow 2.1.2`. If there are limits of cross-dependencies between providers and Airflow packages,\n they are present in providers as `install_requires` limitations. We aim to keep backwards\n compatibility of providers with all previously released Airflow 2 versions but\n there will sometimes be breaking changes that might make some, or all\n providers, have minimum Airflow version specified.\n* **Airflow Helm Chart**: SemVer rules apply to changes in the chart only. SemVer MAJOR and MINOR\n versions for the chart are independent of the Airflow version. We aim to keep backwards\n compatibility of the Helm Chart with all released Airflow 2 versions, but some new features might\n only work starting from specific Airflow releases. We might however limit the Helm\n Chart to depend on minimal Airflow version.\n* **Airflow API clients**: Their versioning is independent from Airflow versions. They follow their own\n SemVer rules for breaking changes and new features - which for example allows to change the way we generate\n the clients.\n\n## Version Life Cycle\n\nApache Airflow version life cycle:\n\n<!-- This table is automatically updated by prek scripts/ci/prek/supported_versions.py -->\n<!-- Beginning of auto-generated table -->\n\n| Version | Current Patch/Minor | State | First Release | Limited Maintenance | EOL/Terminated |\n|-----------|-----------------------|-------------|-----------------|-----------------------|------------------|\n| 3 | 3.3.0 | Maintenance | Apr 22, 2025 | TBD | TBD |\n| 2 | 2.11.2 | EOL | Dec 17, 2020 | Oct 22, 2025 | Apr 22, 2026 |\n| 1.10 | 1.10.15 | EOL | Aug 27, 2018 | Dec 17, 2020 | June 17, 2021 |\n| 1.9 | 1.9.0 | EOL | Jan 03, 2018 | Aug 27, 2018 | Aug 27, 2018 |\n| 1.8 | 1.8.2 | EOL | Mar 19, 2017 | Jan 03, 2018 | Jan 03, 2018 |\n| 1.7 | 1.7.1.2 | EOL | Mar 28, 2016 | Mar 19, 2017 | Mar 19, 2017 |\n\n<!-- End of auto-generated table -->\n\nLimited support versions will be supported with security and critical bug fix only.\nEOL versions will not get any fixes nor support.\nWe always recommend that all users run the latest available minor release for whatever major version is in use.\nWe **highly** recommend upgrading to the latest Airflow major release at the earliest convenient time and before the EOL date.\n\n## Support for Python and Kubernetes versions\n\nAs of Airflow 2.0, we agreed to certain rules we follow for Python and Kubernetes support.\nThey are based on the official release schedule of Python and Kubernetes, nicely summarized in the\n[Python Developer's Guide](https://devguide.python.org/#status-of-python-branches) and\n[Kubernetes version skew policy](https://kubernetes.io/docs/setup/release/version-skew-policy/).\n\n1. We drop support for Python and Kubernetes versions when they reach EOL. Except for Kubernetes, a\n version stays supported by Airflow if two major cloud providers still provide support for it. We drop\n support for those EOL versions in main right after EOL date, and it is effectively removed when we release\n the first new MINOR (Or MAJOR if there is no new MINOR version) of Airflow. For example, for Python 3.10 it\n means that we will drop support in main right after 27.06.2023, and the first MAJOR or MINOR version of\n Airflow released after will not have it.\n\n2. We support a new version of Python/Kubernetes in main after they are officially released, as soon as we\n make them work in our CI pipeline (which might not be immediate due to dependencies catching up with\n new versions of Python mostly) we release new images/support in Airflow based on the working CI setup.\n\n3. This policy is best-effort which means there may be situations where we might terminate support earlier\n if circumstances require it.\n\n## Base OS support for reference Airflow images\n\nThe Airflow Community provides conveniently packaged container images that are published whenever\nwe publish an Apache Airflow release. Those images contain:\n\n* Base OS with necessary packages to install Airflow (stable Debian OS)\n* Base Python installation in versions supported at the time of release for the MINOR version of\n Airflow released (so there could be different versions for 2.3 and 2.2 line for example)\n* Libraries required to connect to supported Databases (again the set of databases supported depends\n on the MINOR version of Airflow)\n* Predefined set of popular providers (for details see the [Dockerfile](https://raw.githubusercontent.com/apache/airflow/main/Dockerfile)).\n* Possibility of building your own, custom image where the user can choose their own set of providers\n and libraries (see [Building the image](https://airflow.apache.org/docs/docker-stack/build.html))\n* In the future Airflow might also support a \"slim\" version without providers nor database clients installed\n\nThe version of the base OS image is the stable version of Debian. Airflow supports using all currently active\nstable versions - as soon as all Airflow dependencies support building, and we set up the CI pipeline for\nbuilding and testing the OS version. Approximately 6 months before the end-of-regular support of a\nprevious stable version of the OS, Airflow switches the images released to use the latest supported\nversion of the OS.\n\nFor example switch from ``Debian Bullseye`` to ``Debian Bookworm`` has been implemented\nbefore 2.8.0 release in October 2023 and ``Debian Bookworm`` will be the only option supported as of\nAirflow 2.10.0.\n\nUsers will continue to be able to build their images using stable Debian releases until the end of regular\nsupport and building and verifying of the images happens in our CI but no unit tests were executed using\nthis image in the `main` branch.\n\n## Approach to dependencies of Airflow\n\nAirflow has a lot of dependencies - direct and transitive, also Airflow is both - library and application,\ntherefore our policies to dependencies has to include both - stability of installation of application,\nbut also ability to install newer version of dependencies for those users who develop Dags. We developed\nthe approach where `constraints` are used to make sure airflow can be installed in a repeatable way, while\nwe do not limit our users to upgrade most of the dependencies. As a result we decided not to upper-bound\nversion of Airflow dependencies by default, unless we have good reasons to believe upper-bounding them is\nneeded because of importance of the dependency as well as risk it involves to upgrade specific dependency.\nWe also upper-bound the dependencies that we know cause problems.\n\nThe constraint mechanism of ours takes care about finding and upgrading all the non-upper bound dependencies\nautomatically (providing that all the tests pass). Our `main` build failures will indicate in case there\nare versions of dependencies that break our tests - indicating that we should either upper-bind them or\nthat we should fix our code/tests to account for the upstream changes from those dependencies.\n\nWhenever we upper-bound such a dependency, we should always comment why we are doing it - i.e. we should have\na good reason why dependency is upper-bound. And we should also mention what is the condition to remove the\nbinding.\n\n### Approach for dependencies for Airflow Core\n\nThose dependencies are maintained in ``pyproject.toml``.\n\nThere are few dependencies that we decided are important enough to upper-bound them by default, as they are\nknown to follow predictable versioning scheme, and we know that new versions of those are very likely to\nbring breaking changes. We commit to regularly review and attempt to upgrade to the newer versions of\nthe dependencies as they are released, but this is manual process.\n\nThe important dependencies are:\n\n* `SQLAlchemy`: upper-bound to specific MINOR version (SQLAlchemy is known to remove deprecations and\n introduce breaking changes especially that support for different Databases varies and changes at\n various speed)\n* `Alembic`: it is important to handle our migrations in predictable and performant way. It is developed\n together with SQLAlchemy. Our experience with Alembic is that it very stable in MINOR version\n* `Flask`: We are using Flask as the back-bone of our web UI and API. We know major version of Flask\n are very likely to introduce breaking changes across those so limiting it to MAJOR version makes sense\n* `werkzeug`: the library is known to cause problems in new versions. It is tightly coupled with Flask\n libraries, and we should update them together\n* `celery`: Celery is a crucial component of Airflow as it used for CeleryExecutor (and similar). Celery\n [follows SemVer](https://docs.celeryq.dev/en/stable/contributing.html?highlight=semver#versions), so\n we should upper-bound it to the next MAJOR version. Also, when we bump the upper version of the library,\n we should make sure Celery Provider minimum Airflow version is updated.\n* `kubernetes`: Kubernetes is a crucial component of Airflow as it is used for the KubernetesExecutor\n (and similar). Kubernetes Python library [follows SemVer](https://github.com/kubernetes-client/python#compatibility),\n so we should upper-bound it to the next MAJOR version. Also, when we bump the upper version of the library,\n we should make sure Kubernetes Provider minimum Airflow version is updated.\n\n### Approach for dependencies in Airflow Providers and extras\n\nThe main part of the Airflow is the Airflow Core, but the power of Airflow also comes from a number of\nproviders that extend the core functionality and are released separately, even if we keep them (for now)\nin the same monorepo for convenience. You can read more about the providers in the\n[Providers documentation](https://airflow.apache.org/docs/apache-airflow-providers/index.html). We also\nhave set of policies implemented for maintaining and releasing community-managed providers as well\nas the approach for community vs. 3rd party providers in the [providers](https://github.com/apache/airflow/blob/main/PROVIDERS.rst) document.\n\nThose `extras` and `providers` dependencies are maintained in `provider.yaml` of each provider.\n\nBy default, we should not upper-bound dependencies for providers, however each provider's maintainer\nmight decide to add additional limits (and justify them with comment).\n\n<!-- START Contributing, please keep comment here to allow auto update of PyPI readme.md -->\n\n## Contributing\n\nWant to help build Apache Airflow? Check out our [contributors' guide](https://github.com/apache/airflow/blob/main/contributing-docs/README.rst) for a comprehensive overview of how to contribute, including setup instructions, coding standards, and pull request guidelines.\n\nIf you can't wait to contribute, and want to get started asap, check out the [contribution quickstart](https://github.com/apache/airflow/blob/main/contributing-docs/03a_contributors_quick_start_beginners.rst) here!\n\nOfficial Docker (container) images for Apache Airflow are described in [images](https://github.com/apache/airflow/blob/main/dev/breeze/doc/ci/02_images.md).\n\n<!-- END Contributing, please keep comment here to allow auto update of PyPI readme.md -->\n\n## Community standards\n\nEveryone interacting with the Apache Airflow project — on GitHub, the\nmailing lists, Slack, the CWiki, or anywhere else — is expected to\nfollow the [Code of Conduct](CODE_OF_CONDUCT.md).\n\nWhen repeated Code of Conduct breaches, spamming, abuse of project\nresources, or other sustained disruptive behaviour cannot be resolved\nthrough normal review and mentoring, the project applies the\n[Community escalation process](COMMUNITY_ESCALATION.md). It describes\nthe steps maintainers and the PMC may take — from direct feedback,\nthrough closing PRs, up to PMC-level or ASF-Infrastructure-level\nblocks and reporting accounts to GitHub — and how affected\ncontributors can appeal a decision by emailing the PMC at\n`private@airflow.apache.org`.\n\n## Agent-assisted contribution (apache-magpie)\n\nThis repo adopts the [`apache/magpie`](https://github.com/apache/magpie)\nframework via a snapshot mechanism. The framework provides\nmaintainer-facing PR-management skills (`pr-management-triage`,\n`pr-management-code-review`, `pr-management-stats`, `pr-management-mentor`)\nthat are exposed as agent skills in agent harnesses such as Claude Code.\n\nThe framework is **not** vendored — it lives as a gitignored snapshot\nunder `.apache-magpie/`, fetched on demand from the version pinned in\nthe committed [`.apache-magpie.lock`](.apache-magpie.lock). The only\nframework artefact committed to this repo is the `magpie-setup` skill\nat [`.github/skills/magpie-setup/`](.github/skills/magpie-setup/);\neverything else is a gitignored symlink the setup skill wires up.\n\nA fresh clone needs the snapshot populated before any framework skill\nis invocable. In your agent harness, run:\n\n```text\n/magpie-setup\n```\n\n(or follow [`.claude/skills/magpie-setup/`](.claude/skills/magpie-setup/))\nto fetch the snapshot per the committed lock, scaffold the gitignored\nsymlinks, and install the post-checkout hook that re-creates them on\neach worktree checkout.\n\nAdopter-specific modifications to framework workflows live in\n[`.apache-magpie-overrides/`](.apache-magpie-overrides/) (committed) —\nnever edit the snapshot directly. Framework changes go via PR to\n[`apache/magpie`](https://github.com/apache/magpie).\n\n<!-- START Who uses Apache Airflow, please keep comment here to allow auto update of PyPI readme.md -->\n\n## Voting Policy\n\n* Commits need a +1 vote from a committer who is not the author\n* When we do AIP voting, both PMC member's and committer's `+1s` are considered a binding vote.\n\n## Who uses Apache Airflow?\n\nWe know about around 500 organizations that are using Apache Airflow (but there are likely many more)\n[in the wild](https://github.com/apache/airflow/blob/main/INTHEWILD.md).\n\nIf you use Airflow - feel free to make a PR to add your organisation to the list.\n\n<!-- END Who uses Apache Airflow, please keep comment here to allow auto update of PyPI readme.md -->\n<!-- START Who maintains Apache Airflow, please keep comment here to allow auto update of PyPI readme.md -->\n\n## Who maintains Apache Airflow?\n\nAirflow is the work of the [community](https://github.com/apache/airflow/graphs/contributors),\nbut the [core committers/maintainers](https://people.apache.org/committers-by-project.html#airflow)\nare responsible for reviewing and merging PRs as well as steering conversations around new feature requests.\nIf you would like to become a maintainer, please review the Apache Airflow\n[committer requirements](https://github.com/apache/airflow/blob/main/COMMITTERS.rst#guidelines-to-become-an-airflow-committer).\n\n<!-- END Who maintains Apache Airflow, please keep comment here to allow auto update of PyPI readme.md -->\n\n## What goes into the next release?\n\nOften you will see an issue that is assigned to specific milestone with Airflow version, or a PR that gets merged\nto the main branch and you might wonder which release the merged PR(s) will be released in or which release the fixed\nissues will be in. The answer to this is as usual - it depends on various scenarios. The answer is different for PRs and Issues.\n\nTo add a bit of context, we are following the [Semver](https://semver.org/) versioning scheme as described in\n[Airflow release process](https://airflow.apache.org/docs/apache-airflow/stable/release-process.html). More\ndetails are explained in detail in this README under the [Semantic versioning](#semantic-versioning) chapter, but\nin short, we have `MAJOR.MINOR.PATCH` versions of Airflow.\n\n* `MAJOR` version is incremented in case of breaking changes\n* `MINOR` version is incremented when there are new features added\n* `PATCH` version is incremented when there are only bug-fixes and doc-only changes\n\nGenerally we release `MINOR` versions of Airflow from a branch that is named after the MINOR version. For example\n`2.7.*` releases are released from `v2-7-stable` branch, `2.8.*` releases are released from `v2-8-stable`\nbranch, etc.\n\n1. Most of the time in our release cycle, when the branch for next `MINOR` branch is not yet created, all\nPRs merged to `main` (unless they get reverted), will find their way to the next `MINOR` release. For example\nif the last release is `2.7.3` and `v2-8-stable` branch is not created yet, the next `MINOR` release\nis `2.8.0` and all PRs merged to main will be released in `2.8.0`. However, some PRs (bug-fixes and\ndoc-only changes) when merged, can be cherry-picked to current `MINOR` branch and released in the\nnext `PATCHLEVEL` release. For example, if `2.8.1` is already released and we are working on `2.9.0dev`, then\nmarking a PR with `2.8.2` milestone means that it will be cherry-picked to `v2-8-test` branch and\nreleased in `2.8.2rc1`, and eventually in `2.8.2`.\n\n2. When we prepare for the next `MINOR` release, we cut new `v2-*-test` and `v2-*-stable` branch\nand prepare `alpha`, `beta` releases for the next `MINOR` version, the PRs merged to main will still be\nreleased in the next `MINOR` release until `rc` version is cut. This is happening because the `v2-*-test`\nand `v2-*-stable` branches are rebased on top of main when next `beta` and `rc` releases are prepared.\nFor example, when we cut `2.10.0beta1` version, anything merged to main before `2.10.0rc1` is released,\nwill find its way to 2.10.0rc1.\n\n3. Then, once we prepare the first RC candidate for the MINOR release, we stop moving the `v2-*-test` and\n`v2-*-stable` branches and the PRs merged to main will be released in the next `MINOR` release.\nHowever, some PRs (bug-fixes and doc-only changes) when merged, can be cherry-picked to current `MINOR`\nbranch and released in the next `PATCHLEVEL` release - for example when the last released version from `v2-10-stable`\nbranch is `2.10.0rc1`, some of the PRs from main can be marked as `2.10.0` milestone by committers,\nthe release manager will try to cherry-pick them into the release branch.\nIf successful, they will be released in `2.10.0rc2` and subsequently in `2.10.0`. This also applies to\nsubsequent `PATCHLEVEL` versions. When for example `2.10.1` is already released, marking a PR with\n`2.10.2` milestone will mean that it will be cherry-picked to `v2-10-stable` branch and released in `2.10.2rc1`\nand eventually in `2.10.2`.\n\nThe final decision about cherry-picking is made by the release manager.\n\nMarking issues with a milestone is a bit different. Maintainers do not mark issues with a milestone usually,\nnormally they are only marked in PRs. If PR linked to the issue (and \"fixing it\") gets merged and released\nin a specific version following the process described above, the issue will be automatically closed, no\nmilestone will be set for the issue, you need to check the PR that fixed the issue to see which version\nit was released in.\n\nHowever, sometimes maintainers mark issues with specific milestone, which means that the\nissue is important to become a candidate to take a look when the release is being prepared. Since this is an\nOpen-Source project, where basically all contributors volunteer their time, there is no guarantee that specific\nissue will be fixed in specific version. We do not want to hold the release because some issue is not fixed,\nso in such case release manager will reassign such unfixed issues to the next milestone in case they are not\nfixed in time for the current release. Therefore, the milestone for issue is more of an intent that it should be\nlooked at, than promise it will be fixed in the version.\n\nMore context and **FAQ** about the patchlevel release can be found in the\n[What goes into the next release](dev/WHAT_GOES_INTO_THE_NEXT_RELEASE.md) document in the `dev` folder of the\nrepository.\n\n## Can I use the Apache Airflow logo in my presentation?\n\nYes! Be sure to abide by the Apache Foundation [trademark policies](https://www.apache.org/foundation/marks/#books) and the Apache Airflow [Brandbook](https://cwiki.apache.org/confluence/display/AIRFLOW/Brandbook). The most up-to-date logos are found in [this repo](https://github.com/apache/airflow/tree/main/airflow-core/docs/img/logos/) and on the Apache Software Foundation [website](https://www.apache.org/logos/about.html).\n\n## Links\n\n- [Documentation](https://airflow.apache.org/docs/apache-airflow/stable/)\n- [Chat](https://s.apache.org/airflow-slack)\n- [Community Information](https://airflow.apache.org/community/)\n\n## Sponsors\n\nThe CI infrastructure for Apache Airflow has been sponsored by:\n\n<!-- Ordered by most recently \"funded\" -->\n\n<a href=\"https://astronomer.io\"><img src=\"https://assets2.astronomer.io/logos/logoForLIGHTbackground.png\" alt=\"astronomer.io\" width=\"250px\"></a>\n<a href=\"https://aws.amazon.com/opensource/\"><img src=\"https://github.com/apache/airflow/blob/main/providers/amazon/docs/integration-logos/AWS-Cloud-alt_light-bg@4x.png?raw=true\" alt=\"AWS OpenSource\" width=\"130px\"></a>",
"readme_text":"<p align=\"center\">\n <a href=\"https://fastapi.tiangolo.com\"><img src=\"https://fastapi.tiangolo.com/img/logo-margin/logo-teal.png\" alt=\"FastAPI\"></a>\n</p>\n<p align=\"center\">\n <em>FastAPI framework, high performance, easy to learn, fast to code, ready for production</em>\n</p>\n<p align=\"center\">\n<a href=\"https://github.com/fastapi/fastapi/actions?query=workflow%3ATest+event%3Apush+branch%3Amaster\">\n <img src=\"https://github.com/fastapi/fastapi/actions/workflows/test.yml/badge.svg?event=push&branch=master\" alt=\"Test\">\n</a>\n<a href=\"https://coverage-badge.samuelcolvin.workers.dev/redirect/fastapi/fastapi\">\n <img src=\"https://coverage-badge.samuelcolvin.workers.dev/fastapi/fastapi.svg\" alt=\"Coverage\">\n</a>\n<a href=\"https://pypi.org/project/fastapi\">\n <img src=\"https://img.shields.io/pypi/v/fastapi?color=%2334D058&label=pypi%20package\" alt=\"Package version\">\n</a>\n<a href=\"https://pypi.org/project/fastapi\">\n <img src=\"https://img.shields.io/pypi/pyversions/fastapi.svg?color=%2334D058\" alt=\"Supported Python versions\">\n</a>\n</p>\n\n---\n\n**Documentation**: [https://fastapi.tiangolo.com](https://fastapi.tiangolo.com)\n\n**Source Code**: [https://github.com/fastapi/fastapi](https://github.com/fastapi/fastapi)\n\n---\n\nFastAPI is a modern, fast (high-performance), web framework for building APIs with Python based on standard Python type hints.\n\nThe key features are:\n\n* **Fast**: Very high performance, on par with **NodeJS** and **Go** (thanks to Starlette and Pydantic). [One of the fastest Python frameworks available](#performance).\n* **Fast to code**: Increase the speed to develop features by about 200% to 300%. *\n* **Fewer bugs**: Reduce about 40% of human (developer) induced errors. *\n* **Intuitive**: Great editor support. <dfn title=\"also known as auto-complete, autocompletion, IntelliSense\">Completion</dfn> everywhere. Less time debugging.\n* **Easy**: Designed to be easy to use and learn. Less time reading docs.\n* **Short**: Minimize code duplication. Multiple features from each parameter declaration. Fewer bugs.\n* **Robust**: Get production-ready code. With automatic interactive documentation.\n* **Standards-based**: Based on (and fully compatible with) the open standards for APIs: [OpenAPI](https://github.com/OAI/OpenAPI-Specification) (previously known as Swagger) and [JSON Schema](https://json-schema.org/).\n\n<small>* estimation based on tests conducted by an internal development team, building production applications.</small>\n\n## Sponsors\n\n<!-- sponsors -->\n### Keystone Sponsor\n\n<a href=\"https://fastapicloud.com\" target=\"_blank\" title=\"FastAPI Cloud. By the same team behind FastAPI. You code. We Cloud.\"><img src=\"https://fastapi.tiangolo.com/img/sponsors/fastapicloud.png\"></a>\n\n### Gold Sponsors\n\n<a href=\"https://blockbee.io?ref=fastapi\" target=\"_blank\" title=\"BlockBee Cryptocurrency Payment Gateway\"><img src=\"https://fastapi.tiangolo.com/img/sponsors/blockbee.png\"></a>\n<a href=\"https://www.propelauth.com/?utm_source=fastapi&utm_campaign=1223&utm_medium=mainbadge\" target=\"_blank\" title=\"Auth, user management and more for your B2B product\"><img src=\"https://fastapi.tiangolo.com/img/sponsors/propelauth.png\"></a>\n<a href=\"https://docs.render.com/deploy-fastapi?utm_source=deploydoc&utm_medium=referral&utm_campaign=fastapi\" target=\"_blank\" title=\"Deploy & scale any full-stack web app on Render. Focus on building apps, not infra.\"><img src=\"https://fastapi.tiangolo.com/img/sponsors/render.svg\"></a>\n<a href=\"https://www.coderabbit.ai/?utm_source=fastapi&utm_medium=badge&utm_campaign=fastapi\" target=\"_blank\" title=\"Cut Code Review Time & Bugs in Half with CodeRabbit\"><img src=\"https://fastapi.tiangolo.com/img/sponsors/coderabbit.png\"></a>\n<a href=\"https://subtotal.com/?utm_source=fastapi&utm_medium=sponsorship&utm_campaign=open-source\" target=\"_blank\" title=\"The Gold Standard in Retail Account Linking\"><img src=\"https://fastapi.tiangolo.com/img/sponsors/subtotal.svg\"></a>\n<a href=\"https://docs.railway.com/guides/fastapi?utm_medium=integration&utm_source=docs&utm_campaign=fastapi\" target=\"_blank\" title=\"Deploy enterprise applications at startup speed\"><img src=\"https://fastapi.tiangolo.com/img/sponsors/railway.png\"></a>\n<a href=\"https://serpapi.com/?utm_source=fastapi_website\" target=\"_blank\" title=\"SerpApi: Web Search API\"><img src=\"https://fastapi.tiangolo.com/img/sponsors/serpapi.png\"></a>\n<a href=\"https://www.greptile.com/?utm_source=fastapi&utm_medium=sponsorship&utm_campaign=fastapi_sponsor_page\" target=\"_blank\" title=\"Greptile: The AI Code Reviewer\"><img src=\"https://fastapi.tiangolo.com/img/sponsors/greptile.png\"></a>\n\n### Silver Sponsors\n\n<a href=\"https://databento.com/?utm_source=fastapi&utm_medium=sponsor&utm_content=display\" target=\"_blank\" title=\"Pay as you go for market data\"><img src=\"https://fastapi.tiangolo.com/img/sponsors/databento.svg\"></a>\n<a href=\"https://www.svix.com/\" target=\"_blank\" title=\"Svix - Webhooks as a service\"><img src=\"https://fastapi.tiangolo.com/img/sponsors/svix.svg\"></a>\n<a href=\"https://www.permit.io/blog/implement-authorization-in-fastapi?utm_source=github&utm_medium=referral&utm_campaign=fastapi\" target=\"_blank\" title=\"Fine-Grained Authorization for FastAPI\"><img src=\"https://fastapi.tiangolo.com/img/sponsors/permit.png\"></a>\n<a href=\"https://dribia.com/en/\" target=\"_blank\" title=\"Dribia - Data Science within your reach\"><img src=\"https://fastapi.tiangolo.com/img/sponsors/dribia.png\"></a>\n<a href=\"https://www.bairesdev.com/\" target=\"_blank\" title=\"BairesDev | Nearshore Software Development & Staff Augmentation Company\"><img src=\"https://fastapi.tiangolo.com/img/sponsors/bairesdev.svg\"></a>\n<a href=\"https://tutorcruncher.com/?utm_source=fastapi\" target=\"_blank\" title=\"TutorCruncher\"><img src=\"https://fastapi.tiangolo.com/img/sponsors/tutorcruncher.png\"></a>\n\n<!-- /sponsors -->\n\n[Other sponsors](https://fastapi.tiangolo.com/fastapi-people/#sponsors)\n\n## Opinions\n\n\n\n<div class=\"only-github\" markdown=\"1\">\n\n\"_[...] I'm using **FastAPI** a ton these days. [...] I'm actually planning to use it for all of my team's **ML services at Microsoft**. Some of them are getting integrated into the core **Windows** product and some **Office** products._\"\n\n<div style=\"text-align: right; margin-right: 10%;\">Kabir Khan - <strong>Microsoft</strong> <a href=\"https://github.com/fastapi/fastapi/pull/26\"><small>(ref)</small></a></div>\n\n---\n\n\"_We adopted the **FastAPI** library to spawn a **REST** server that can be queried to obtain **predictions**. [for Ludwig]_\"\n\n<div style=\"text-align: right; margin-right: 10%;\">Piero Molino, Yaroslav Dudin, and Sai Sumanth Miryala - <strong>Uber</strong> <a href=\"https://eng.uber.com/ludwig-v0-2/\"><small>(ref)</small></a></div>\n\n---\n\n\"_**Netflix** is pleased to announce the open-source release of our **crisis management** orchestration framework: **Dispatch**! [built with **FastAPI**]_\"\n\n<div style=\"text-align: right; margin-right: 10%;\">Kevin Glisson, Marc Vilanova, Forest Monsen - <strong>Netflix</strong> <a href=\"https://netflixtechblog.com/introducing-dispatch-da4b8a2a8072\"><small>(ref)</small></a></div>\n\n---\n\n\"_If anyone is looking to build a production Python API, I would highly recommend **FastAPI**. It is **beautifully designed**, **simple to use** and **highly scalable**, it has become a **key component** in our API first development strategy and is driving many automations and services such as our Virtual TAC Engineer._\"\n\n<div style=\"text-align: right; margin-right: 10%;\">Deon Pillsbury - <strong>Cisco</strong> <a href=\"https://www.linkedin.com/posts/deonpillsbury_cisco-cx-python-activity-6963242628536487936-trAp/\"><small>(ref)</small></a></div>\n\n---\n\n</div>\n\n## FastAPI Conf\n\n[**FastAPI Conf '26**](https://fastapiconf.com) is happening on **October 28, 2026** in **Amsterdam, NL**. All about FastAPI, right from the source. 🎤\n\n<a class=\"fastapi-feature-banner\" href=\"https://fastapiconf.com\"><img src=\"https://fastapi.tiangolo.com/img/fastapi-conf.jpeg\" alt=\"FastAPI Conf '26 - October 28, 2026 - Amsterdam, NL\"></a>\n\n## FastAPI mini documentary\n\nThere's a [FastAPI mini documentary](https://www.youtube.com/watch?v=mpR8ngthqiE) released at the end of 2025, you can watch it online:\n\n<a class=\"fastapi-feature-banner\" href=\"https://www.youtube.com/watch?v=mpR8ngthqiE\"><img src=\"https://fastapi.tiangolo.com/img/fastapi-documentary.jpg\" alt=\"FastAPI Mini Documentary\"></a>\n\n## **Typer**, the FastAPI of CLIs\n\n<a href=\"https://typer.tiangolo.com\"><img src=\"https://typer.tiangolo.com/img/logo-margin/logo-margin-vector.svg\" style=\"width: 20%;\"></a>\n\nIf you are building a <abbr title=\"Command Line Interface\">CLI</abbr> app to be used in the terminal instead of a web API, check out [**Typer**](https://typer.tiangolo.com/).\n\n**Typer** is FastAPI's little sibling. And it's intended to be the **FastAPI of CLIs**. ⌨️ 🚀\n\n## Requirements\n\nFastAPI stands on the shoulders of giants:\n\n* [Starlette](https://www.starlette.dev/) for the web parts.\n* [Pydantic](https://docs.pydantic.dev/) for the data parts.\n\n## Installation\n\nCreate and activate a [virtual environment](https://fastapi.tiangolo.com/virtual-environments/) and then install FastAPI:\n\n<div class=\"termy\">\n\n```console\n$ pip install \"fastapi[standard]\"\n\n---> 100%\n```\n\n</div>\n\n**Note**: Make sure you put `\"fastapi[standard]\"` in quotes to ensure it works in all terminals.\n\n## Example\n\n### Create it\n\nCreate a file `main.py` with:\n\n```Python\nfrom fastapi import FastAPI\n\napp = FastAPI()\n\n\n@app.get(\"/\")\ndef read_root():\n return {\"Hello\": \"World\"}\n\n\n@app.get(\"/items/{item_id}\")\ndef read_item(item_id: int, q: str | None = None):\n return {\"item_id\": item_id, \"q\": q}\n```\n\n<details markdown=\"1\">\n<summary>Or use <code>async def</code>...</summary>\n\nIf your code uses `async` / `await`, use `async def`:\n\n```Python hl_lines=\"7 12\"\nfrom fastapi import FastAPI\n\napp = FastAPI()\n\n\n@app.get(\"/\")\nasync def read_root():\n return {\"Hello\": \"World\"}\n\n\n@app.get(\"/items/{item_id}\")\nasync def read_item(item_id: int, q: str | None = None):\n return {\"item_id\": item_id, \"q\": q}\n```\n\n**Note**:\n\nIf you don't know, check the _\"In a hurry?\"_ section about [`async` and `await` in the docs](https://fastapi.tiangolo.com/async/#in-a-hurry).\n\n</details>\n\n### Run it\n\nRun the server with:\n\n<div class=\"termy\">\n\n```console\n$ fastapi dev\n\n ╭────────── FastAPI CLI - Development mode ───────────╮\n │ │\n │ Serving at: http://127.0.0.1:8000 │\n │ │\n │ API docs: http://127.0.0.1:8000/docs │\n │ │\n │ Running in development mode, for production use: │\n │ │\n │ fastapi run │\n │ │\n ╰─────────────────────────────────────────────────────╯\n\nINFO: Will watch for changes in these directories: ['/home/user/code/awesomeapp']\nINFO: Uvicorn running on http://127.0.0.1:8000 (Press CTRL+C to quit)\nINFO: Started reloader process [2248755] using WatchFiles\nINFO: Started server process [2248757]\nINFO: Waiting for application startup.\nINFO: Application startup complete.\n```\n\n</div>\n\n<details markdown=\"1\">\n<summary>About the command <code>fastapi dev</code>...</summary>\n\nThe command `fastapi dev` reads your `main.py` file automatically, detects the **FastAPI** app in it, and starts a server using [Uvicorn](https://www.uvicorn.dev).\n\nBy default, `fastapi dev` will start with auto-reload enabled for local development.\n\nYou can read more about it in the [FastAPI CLI docs](https://fastapi.tiangolo.com/fastapi-cli/).\n\n</details>\n\n### Check it\n\nOpen your browser at [http://127.0.0.1:8000/items/5?q=somequery](http://127.0.0.1:8000/items/5?q=somequery).\n\nYou will see the JSON response as:\n\n```JSON\n{\"item_id\": 5, \"q\": \"somequery\"}\n```\n\nYou already created an API that:\n\n* Receives HTTP requests in the _paths_ `/` and `/items/{item_id}`.\n* Both _paths_ take `GET` <em>operations</em> (also known as HTTP _methods_).\n* The _path_ `/items/{item_id}` has a _path parameter_ `item_id` that should be an `int`.\n* The _path_ `/items/{item_id}` has an optional `str` _query parameter_ `q`.\n\n### Interactive API docs\n\nNow go to [http://127.0.0.1:8000/docs](http://127.0.0.1:8000/docs).\n\nYou will see the automatic interactive API documentation (provided by [Swagger UI](https://github.com/swagger-api/swagger-ui)):\n\n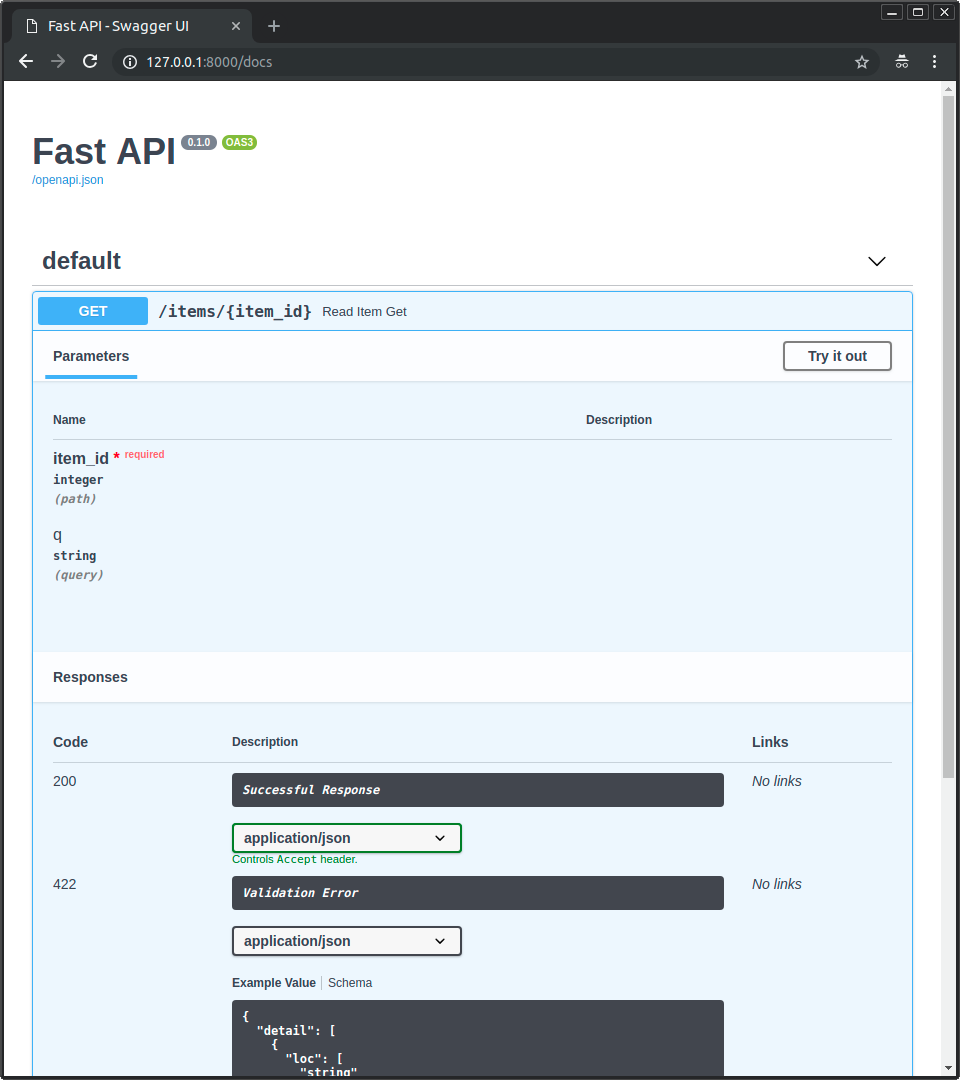\n\n### Alternative API docs\n\nAnd now, go to [http://127.0.0.1:8000/redoc](http://127.0.0.1:8000/redoc).\n\nYou will see the alternative automatic documentation (provided by [ReDoc](https://github.com/Rebilly/ReDoc)):\n\n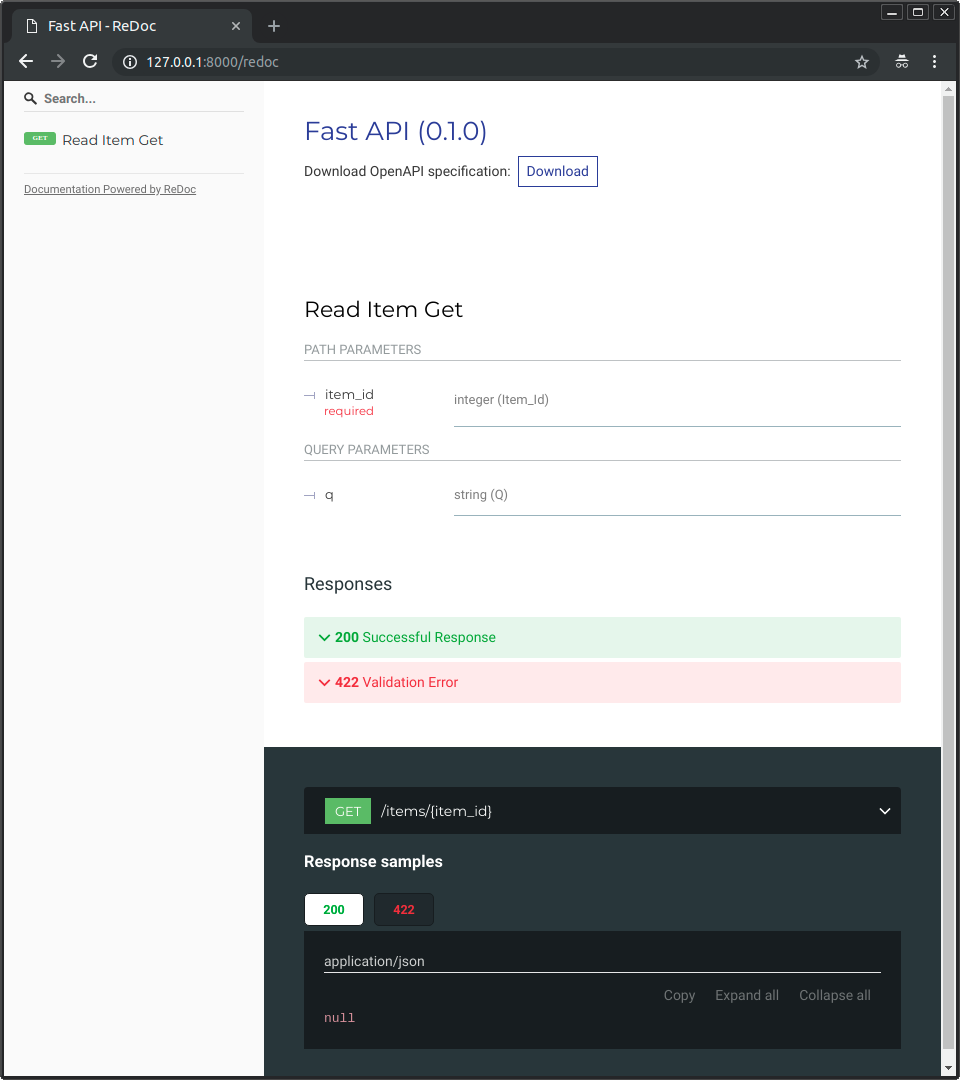\n\n## Example upgrade\n\nNow modify the file `main.py` to receive a body from a `PUT` request.\n\nDeclare the body using standard Python types, thanks to Pydantic.\n\n```Python hl_lines=\"2 7-10 23-25\"\nfrom fastapi import FastAPI\nfrom pydantic import BaseModel\n\napp = FastAPI()\n\n\nclass Item(BaseModel):\n name: str\n price: float\n is_offer: bool | None = None\n\n\n@app.get(\"/\")\ndef read_root():\n return {\"Hello\": \"World\"}\n\n\n@app.get(\"/items/{item_id}\")\ndef read_item(item_id: int, q: str | None = None):\n return {\"item_id\": item_id, \"q\": q}\n\n\n@app.put(\"/items/{item_id}\")\ndef update_item(item_id: int, item: Item):\n return {\"item_name\": item.name, \"item_id\": item_id}\n```\n\nThe `fastapi dev` server should reload automatically.\n\n### Interactive API docs upgrade\n\nNow go to [http://127.0.0.1:8000/docs](http://127.0.0.1:8000/docs).\n\n* The interactive API documentation will be automatically updated, including the new body:\n\n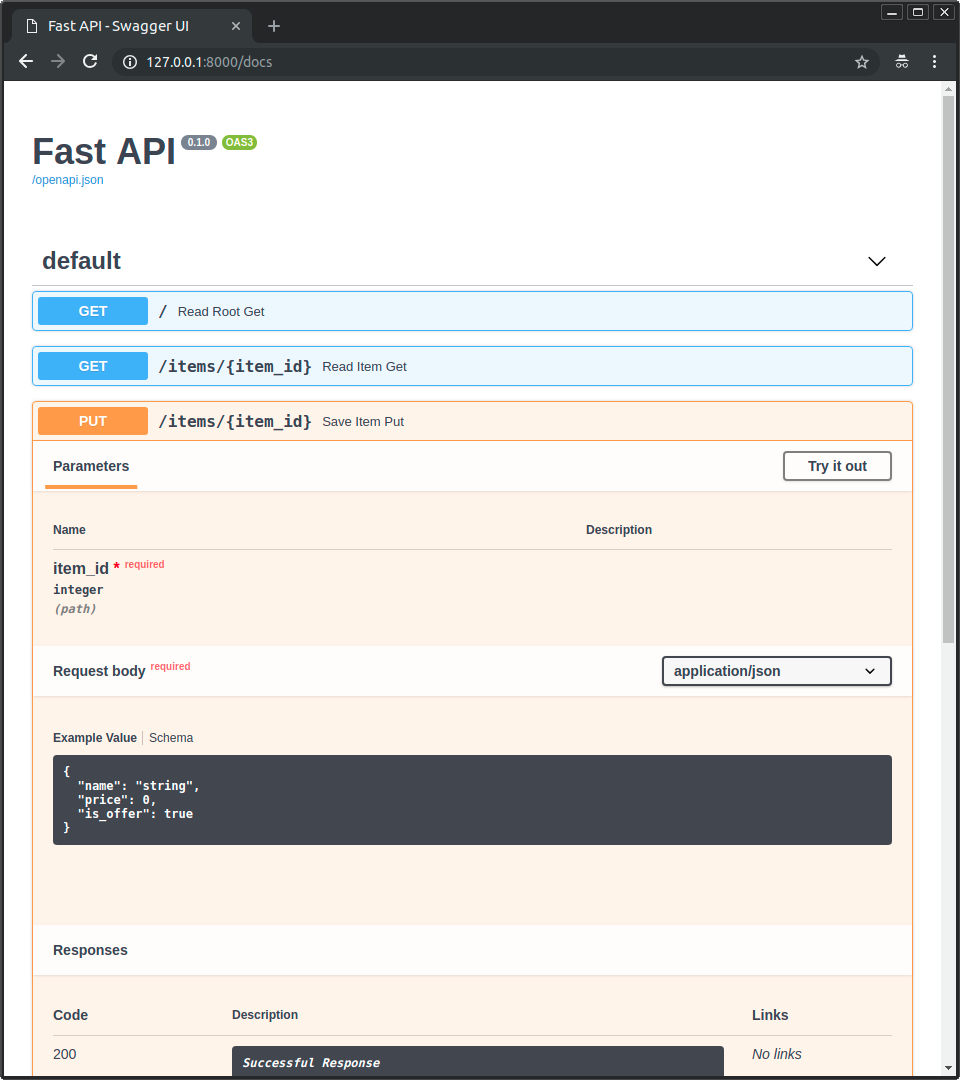\n\n* Click on the button \"Try it out\", it allows you to fill the parameters and directly interact with the API:\n\n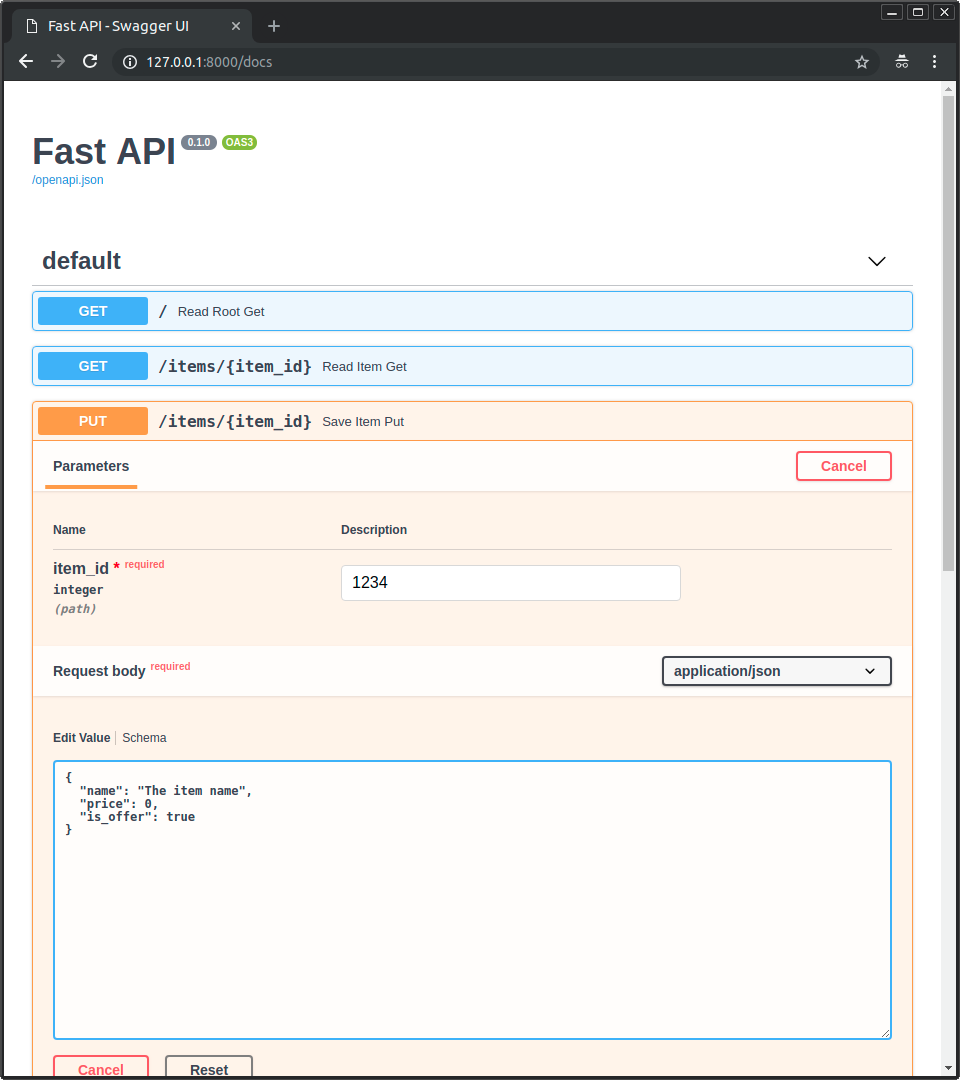\n\n* Then click on the \"Execute\" button, the user interface will communicate with your API, send the parameters, get the results and show them on the screen:\n\n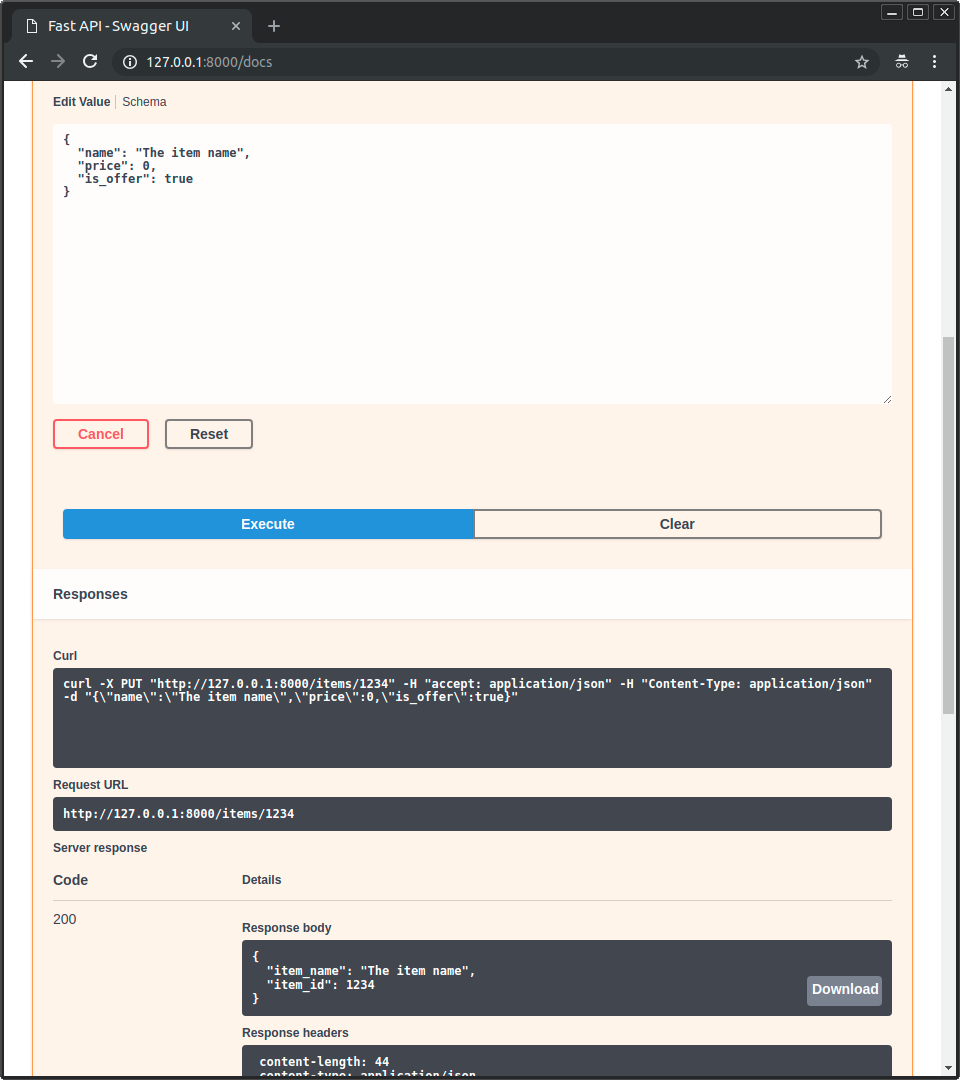\n\n### Alternative API docs upgrade\n\nAnd now, go to [http://127.0.0.1:8000/redoc](http://127.0.0.1:8000/redoc).\n\n* The alternative documentation will also reflect the new query parameter and body:\n\n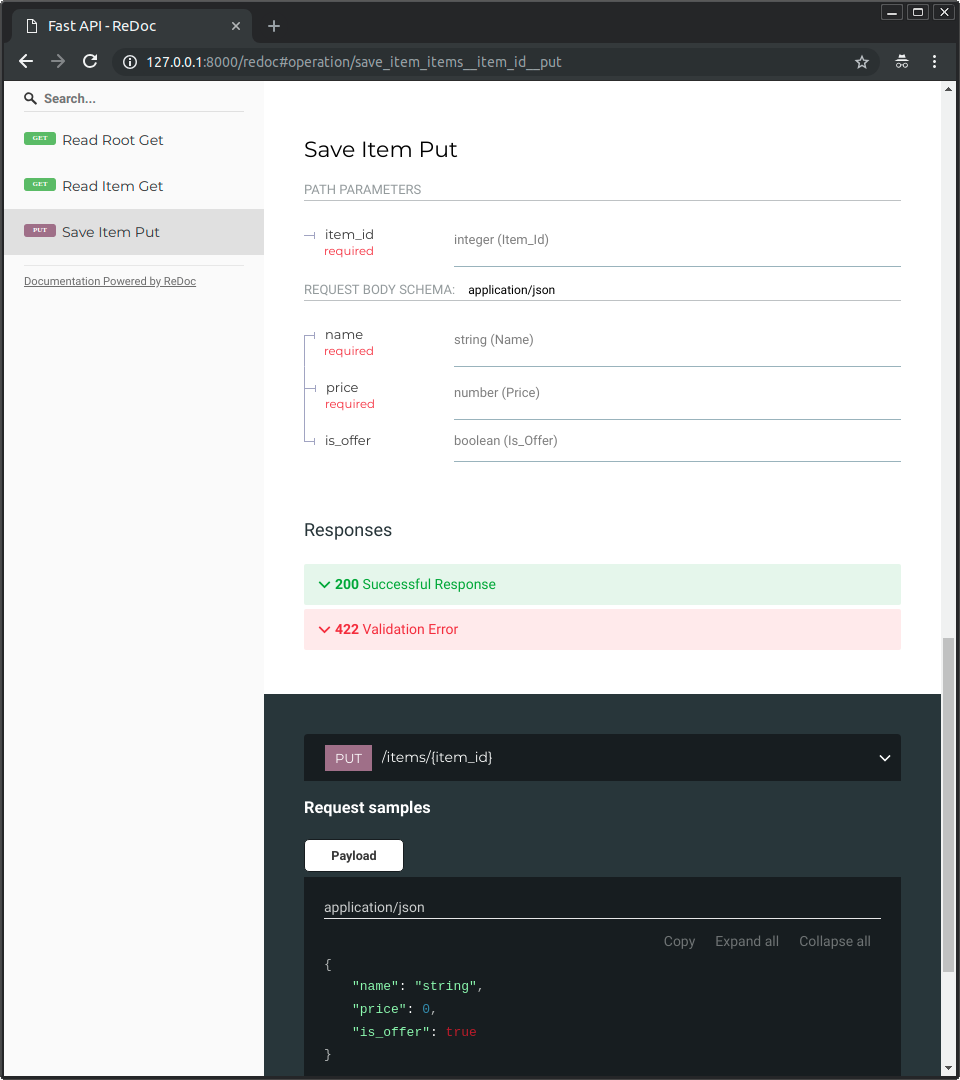\n\n### Recap\n\nIn summary, you declare **once** the types of parameters, body, etc. as function parameters.\n\nYou do that with standard modern Python types.\n\nYou don't have to learn a new syntax, the methods or classes of a specific library, etc.\n\nJust standard **Python**.\n\nFor example, for an `int`:\n\n```Python\nitem_id: int\n```\n\nor for a more complex `Item` model:\n\n```Python\nitem: Item\n```\n\n...and with that single declaration you get:\n\n* Editor support, including:\n * Completion.\n * Type checks.\n* Validation of data:\n * Automatic and clear errors when the data is invalid.\n * Validation even for deeply nested JSON objects.\n* <dfn title=\"also known as: serialization, parsing, marshalling\">Conversion</dfn> of input data: coming from the network to Python data and types. Reading from:\n * JSON.\n * Path parameters.\n * Query parameters.\n * Cookies.\n * Headers.\n * Forms.\n * Files.\n* <dfn title=\"also known as: serialization, parsing, marshalling\">Conversion</dfn> of output data: converting from Python data and types to network data (as JSON):\n * Convert Python types (`str`, `int`, `float`, `bool`, `list`, etc).\n * `datetime` objects.\n * `UUID` objects.\n * Database models.\n * ...and many more.\n* Automatic interactive API documentation, including 2 alternative user interfaces:\n * Swagger UI.\n * ReDoc.\n\n---\n\nComing back to the previous code example, **FastAPI** will:\n\n* Validate that there is an `item_id` in the path for `GET` and `PUT` requests.\n* Validate that the `item_id` is of type `int` for `GET` and `PUT` requests.\n * If it is not, the client will see a useful, clear error.\n* Check if there is an optional query parameter named `q` (as in `http://127.0.0.1:8000/items/foo?q=somequery`) for `GET` requests.\n * As the `q` parameter is declared with `= None`, it is optional.\n * Without the `None` it would be required (as is the body in the case with `PUT`).\n* For `PUT` requests to `/items/{item_id}`, read the body as JSON:\n * Check that it has a required attribute `name` that should be a `str`.\n * Check that it has a required attribute `price` that has to be a `float`.\n * Check that it has an optional attribute `is_offer`, that should be a `bool`, if present.\n * All this would also work for deeply nested JSON objects.\n* Convert from and to JSON automatically.\n* Document everything with OpenAPI, that can be used by:\n * Interactive documentation systems.\n * Automatic client code generation systems, for many languages.\n* Provide 2 interactive documentation web interfaces directly.\n\n---\n\nWe just scratched the surface, but you already get the idea of how it all works.\n\nTry changing the line with:\n\n```Python\n return {\"item_name\": item.name, \"item_id\": item_id}\n```\n\n...from:\n\n```Python\n ... \"item_name\": item.name ...\n```\n\n...to:\n\n```Python\n ... \"item_price\": item.price ...\n```\n\n...and see how your editor will auto-complete the attributes and know their types:\n\n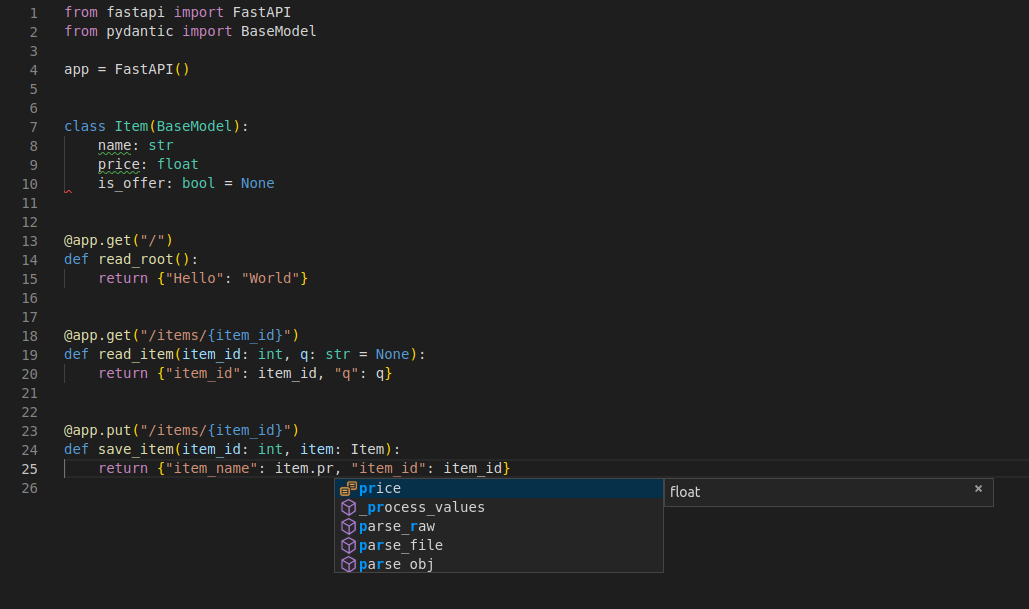\n\nFor a more complete example including more features, see the <a href=\"https://fastapi.tiangolo.com/tutorial/\">Tutorial - User Guide</a>.\n\n**Spoiler alert**: the tutorial - user guide includes:\n\n* Declaration of **parameters** from other different places such as: **headers**, **cookies**, **form fields** and **files**.\n* How to set **validation constraints** such as `maximum_length` or `regex`.\n* A very powerful and easy to use **<dfn title=\"also known as components, resources, providers, services, injectables\">Dependency Injection</dfn>** system.\n* Security and authentication, including support for **OAuth2** with **JWT tokens** and **HTTP Basic** auth.\n* More advanced (but equally easy) techniques for declaring **deeply nested JSON models** (thanks to Pydantic).\n* **GraphQL** integration with [Strawberry](https://strawberry.rocks) and other libraries.\n* Many extra features (thanks to Starlette) such as:\n * **WebSockets**\n * extremely easy tests based on HTTPX and `pytest`\n * **CORS**\n * **Cookie Sessions**\n * ...and more.\n\n### Deploy your app (optional)\n\nYou can optionally deploy your FastAPI app to [FastAPI Cloud](https://fastapicloud.com) with a single command. 🚀\n\n<div class=\"termy\">\n\n```console\n$ fastapi deploy\n\nDeploying to FastAPI Cloud...\n\n✅ Deployment successful!\n\n🐔 Ready the chicken! Your app is ready at https://myapp.fastapicloud.dev\n```\n\n</div>\n\nThe CLI will automatically detect your FastAPI application and deploy it to the cloud. If you are not logged in, your browser will open to complete the authentication process.\n\nThat's it! Now you can access your app at that URL. ✨\n\n#### About FastAPI Cloud\n\n**[FastAPI Cloud](https://fastapicloud.com)** is built by the same author and team behind **FastAPI**.\n\nIt streamlines the process of **building**, **deploying**, and **accessing** an API with minimal effort.\n\nIt brings the same **developer experience** of building apps with FastAPI to **deploying** them to the cloud. 🎉\n\nFastAPI Cloud is the primary sponsor and funding provider for the *FastAPI and friends* open source projects. ✨\n\n#### Deploy to other cloud providers\n\nFastAPI is open source and based on standards. You can deploy FastAPI apps to any cloud provider you choose.\n\nFollow your cloud provider's guides to deploy FastAPI apps with them. 🤓\n\n## Performance\n\nIndependent TechEmpower benchmarks show **FastAPI** applications running under Uvicorn as [one of the fastest Python frameworks available](https://www.techempower.com/benchmarks/#section=test&runid=7464e520-0dc2-473d-bd34-dbdfd7e85911&hw=ph&test=query&l=zijzen-7), only below Starlette and Uvicorn themselves (used internally by FastAPI). (*)\n\nTo understand more about it, see the section [Benchmarks](https://fastapi.tiangolo.com/benchmarks/).\n\n## Dependencies\n\nFastAPI depends on Pydantic and Starlette.\n\n### `standard` Dependencies\n\nWhen you install FastAPI with `pip install \"fastapi[standard]\"` it comes with the `standard` group of optional dependencies:\n\nUsed by Pydantic:\n\n* [`email-validator`](https://github.com/JoshData/python-email-validator) - for email validation.\n\nUsed by Starlette:\n\n* [`httpx`](https://www.python-httpx.org) - Required if you want to use the `TestClient`.\n* [`jinja2`](https://jinja.palletsprojects.com) - Required if you want to use the default template configuration.\n* [`python-multipart`](https://github.com/Kludex/python-multipart) - Required if you want to support form <dfn title=\"converting the string that comes from an HTTP request into Python data\">\"parsing\"</dfn>, with `request.form()`.\n\nUsed by FastAPI:\n\n* [`uvicorn`](https://www.uvicorn.dev) - for the server that loads and serves your application. This includes `uvicorn[standard]`, which includes some dependencies (e.g. `uvloop`) needed for high performance serving.\n* `fastapi-cli[standard]` - to provide the `fastapi` command.\n * This includes `fastapi-cloud-cli`, which allows you to deploy your FastAPI application to [FastAPI Cloud](https://fastapicloud.com).\n\n### Without `standard` Dependencies\n\nIf you don't want to include the `standard` optional dependencies, you can install with `pip install fastapi` instead of `pip install \"fastapi[standard]\"`.\n\n### Without `fastapi-cloud-cli`\n\nIf you want to install FastAPI with the standard dependencies but without the `fastapi-cloud-cli`, you can install with `pip install \"fastapi[standard-no-fastapi-cloud-cli]\"`.\n\n### Additional Optional Dependencies\n\nThere are some additional dependencies you might want to install.\n\nAdditional optional Pydantic dependencies:\n\n* [`pydantic-settings`](https://docs.pydantic.dev/latest/usage/pydantic_settings/) - for settings management.\n* [`pydantic-extra-types`](https://docs.pydantic.dev/latest/usage/types/extra_types/extra_types/) - for extra types to be used with Pydantic.\n\nAdditional optional FastAPI dependencies:\n\n* [`orjson`](https://github.com/ijl/orjson) - Required if you want to use `ORJSONResponse`.\n* [`ujson`](https://github.com/esnme/ultrajson) - Required if you want to use `UJSONResponse`.\n\n## License\n\nThis project is licensed under the terms of the MIT license.",
"readme_text":"<!---\nCopyright 2020 The HuggingFace Team. All rights reserved.\n\nLicensed under the Apache License, Version 2.0 (the \"License\");\nyou may not use this file except in compliance with the License.\nYou may obtain a copy of the License at\n\n http://www.apache.org/licenses/LICENSE-2.0\n\nUnless required by applicable law or agreed to in writing, software\ndistributed under the License is distributed on an \"AS IS\" BASIS,\nWITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.\nSee the License for the specific language governing permissions and\nlimitations under the License.\n-->\n\n<p align=\"center\">\n <picture>\n <source media=\"(prefers-color-scheme: dark)\" srcset=\"https://huggingface.co/datasets/huggingface/documentation-images/raw/main/transformers-logo-dark.svg\">\n <source media=\"(prefers-color-scheme: light)\" srcset=\"https://huggingface.co/datasets/huggingface/documentation-images/raw/main/transformers-logo-light.svg\">\n <img alt=\"Hugging Face Transformers Library\" src=\"https://huggingface.co/datasets/huggingface/documentation-images/raw/main/transformers-logo-light.svg\" width=\"352\" height=\"59\" style=\"max-width: 100%;\">\n </picture>\n <br/>\n <br/>\n</p>\n\n<p align=\"center\">\n <a href=\"https://huggingface.com/models\"><img alt=\"Checkpoints on Hub\" src=\"https://img.shields.io/endpoint?url=https://huggingface.co/api/shields/models&color=brightgreen\"></a>\n <a href=\"https://circleci.com/gh/huggingface/transformers\"><img alt=\"Build\" src=\"https://img.shields.io/circleci/build/github/huggingface/transformers/main\"></a>\n <a href=\"https://github.com/huggingface/transformers/blob/main/LICENSE\"><img alt=\"GitHub\" src=\"https://img.shields.io/github/license/huggingface/transformers.svg?color=blue\"></a>\n <a href=\"https://huggingface.co/docs/transformers/index\"><img alt=\"Documentation\" src=\"https://img.shields.io/website/http/huggingface.co/docs/transformers/index.svg?down_color=red&down_message=offline&up_message=online\"></a>\n <a href=\"https://github.com/huggingface/transformers/releases\"><img alt=\"GitHub release\" src=\"https://img.shields.io/github/release/huggingface/transformers.svg\"></a>\n <a href=\"https://github.com/huggingface/transformers/blob/main/CODE_OF_CONDUCT.md\"><img alt=\"Contributor Covenant\" src=\"https://img.shields.io/badge/Contributor%20Covenant-v2.0%20adopted-ff69b4.svg\"></a>\n <a href=\"https://zenodo.org/badge/latestdoi/155220641\"><img src=\"https://zenodo.org/badge/155220641.svg\" alt=\"DOI\"></a>\n</p>\n\n<h4 align=\"center\">\n <p>\n <b>English</b> |\n <a href=\"https://github.com/huggingface/transformers/blob/main/i18n/README_zh-hans.md\">简体中文</a> |\n <a href=\"https://github.com/huggingface/transformers/blob/main/i18n/README_zh-hant.md\">繁體中文</a> |\n <a href=\"https://github.com/huggingface/transformers/blob/main/i18n/README_ko.md\">한국어</a> |\n <a href=\"https://github.com/huggingface/transformers/blob/main/i18n/README_es.md\">Español</a> |\n <a href=\"https://github.com/huggingface/transformers/blob/main/i18n/README_ja.md\">日本語</a> |\n <a href=\"https://github.com/huggingface/transformers/blob/main/i18n/README_hd.md\">हिन्दी</a> |\n <a href=\"https://github.com/huggingface/transformers/blob/main/i18n/README_ru.md\">Русский</a> |\n <a href=\"https://github.com/huggingface/transformers/blob/main/i18n/README_pt-br.md\">Português</a> |\n <a href=\"https://github.com/huggingface/transformers/blob/main/i18n/README_te.md\">తెలుగు</a> |\n <a href=\"https://github.com/huggingface/transformers/blob/main/i18n/README_fr.md\">Français</a> |\n <a href=\"https://github.com/huggingface/transformers/blob/main/i18n/README_de.md\">Deutsch</a> |\n <a href=\"https://github.com/huggingface/transformers/blob/main/i18n/README_it.md\">Italiano</a> |\n <a href=\"https://github.com/huggingface/transformers/blob/main/i18n/README_vi.md\">Tiếng Việt</a> |\n <a href=\"https://github.com/huggingface/transformers/blob/main/i18n/README_ar.md\">العربية</a> |\n <a href=\"https://github.com/huggingface/transformers/blob/main/i18n/README_ur.md\">اردو</a> |\n <a href=\"https://github.com/huggingface/transformers/blob/main/i18n/README_bn.md\">বাংলা</a> |\n <a href=\"https://github.com/huggingface/transformers/blob/main/i18n/README_fa.md\">فارسی</a> |\n <a href=\"https://github.com/huggingface/transformers/blob/main/i18n/README_tr.md\">Türkçe</a> |\n </p>\n</h4>\n\n<h3 align=\"center\">\n <p>State-of-the-art pretrained models for inference and training</p>\n</h3>\n\n<h3 align=\"center\">\n <img src=\"https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/transformers/transformers_as_a_model_definition.png\"/>\n</h3>\n\nTransformers acts as the model-definition framework for state-of-the-art machine learning with text, computer\nvision, audio, video, and multimodal models, for both inference and training.\n\nIt centralizes the model definition so that this definition is agreed upon across the ecosystem. `transformers` is the\npivot across frameworks: if a model definition is supported, it will be compatible with the majority of training\nframeworks (Axolotl, Unsloth, DeepSpeed, FSDP, PyTorch-Lightning, ...), inference engines (vLLM, SGLang, TGI, ...),\nand adjacent modeling libraries (llama.cpp, mlx, ...) which leverage the model definition from `transformers`.\n\nWe pledge to help support new state-of-the-art models and democratize their usage by having their model definition be\nsimple, customizable, and efficient.\n\nThere are over 1M+ Transformers [model checkpoints](https://huggingface.co/models?library=transformers&sort=trending) on the [Hugging Face Hub](https://huggingface.co/models) you can use.\n\nExplore the [Hub](https://huggingface.co/) today to find a model and use Transformers to help you get started right away.\n\n## Installation\n\nTransformers works with Python 3.10+, and [PyTorch](https://pytorch.org/get-started/locally/) 2.4+.\n\nCreate and activate a virtual environment with [venv](https://docs.python.org/3/library/venv.html) or [uv](https://docs.astral.sh/uv/), a fast Rust-based Python package and project manager.\n\n```py\n# venv\npython -m venv .my-env\nsource .my-env/bin/activate\n# uv\nuv venv .my-env\nsource .my-env/bin/activate\n```\n\nInstall Transformers in your virtual environment.\n\n```py\n# pip\npip install \"transformers[torch]\"\n\n# uv\nuv pip install \"transformers[torch]\"\n```\n\nInstall Transformers from source if you want the latest changes in the library or are interested in contributing. However, the *latest* version may not be stable. Feel free to open an [issue](https://github.com/huggingface/transformers/issues) if you encounter an error.\n\n```shell\ngit clone https://github.com/huggingface/transformers.git\ncd transformers\n\n# pip\npip install '.[torch]'\n\n# uv\nuv pip install '.[torch]'\n```\n\n## Quickstart\n\nGet started with Transformers right away with the [Pipeline](https://huggingface.co/docs/transformers/pipeline_tutorial) API. The `Pipeline` is a high-level inference class that supports text, audio, vision, and multimodal tasks. It handles preprocessing the input and returns the appropriate output.\n\nInstantiate a pipeline and specify model to use for text generation. The model is downloaded and cached so you can easily reuse it again. Finally, pass some text to prompt the model.\n\n```py\nfrom transformers import pipeline\n\npipeline = pipeline(task=\"text-generation\", model=\"Qwen/Qwen2.5-1.5B\")\npipeline(\"the secret to baking a really good cake is \")\n[{'generated_text': 'the secret to baking a really good cake is 1) to use the right ingredients and 2) to follow the recipe exactly. the recipe for the cake is as follows: 1 cup of sugar, 1 cup of flour, 1 cup of milk, 1 cup of butter, 1 cup of eggs, 1 cup of chocolate chips. if you want to make 2 cakes, how much sugar do you need? To make 2 cakes, you will need 2 cups of sugar.'}]\n```\n\nTo chat with a model, the usage pattern is the same. The only difference is you need to construct a chat history (the input to `Pipeline`) between you and the system.\n\n> [!TIP]\n> You can also chat with a model directly from the command line, as long as [`transformers serve` is running](https://huggingface.co/docs/transformers/main/en/serving).\n> ```shell\n> transformers chat Qwen/Qwen2.5-0.5B-Instruct\n> ```\n\n```py\nimport torch\nfrom transformers import pipeline\n\nchat = [\n {\"role\": \"system\", \"content\": \"You are a sassy, wise-cracking robot as imagined by Hollywood circa 1986.\"},\n {\"role\": \"user\", \"content\": \"Hey, can you tell me any fun things to do in New York?\"}\n]\n\npipeline = pipeline(task=\"text-generation\", model=\"meta-llama/Meta-Llama-3-8B-Instruct\", dtype=torch.bfloat16, device_map=\"auto\")\nresponse = pipeline(chat, max_new_tokens=512)\nprint(response[0][\"generated_text\"][-1][\"content\"])\n```\n\nExpand the examples below to see how `Pipeline` works for different modalities and tasks.\n\n<details>\n<summary>Automatic speech recognition</summary>\n\n```py\nfrom transformers import pipeline\n\npipeline = pipeline(task=\"automatic-speech-recognition\", model=\"openai/whisper-large-v3\")\npipeline(\"https://huggingface.co/datasets/Narsil/asr_dummy/resolve/main/mlk.flac\")\n{'text': ' I have a dream that one day this nation will rise up and live out the true meaning of its creed.'}\n```\n\n</details>\n\n<details>\n<summary>Image classification</summary>\n\n<h3 align=\"center\">\n <a><img src=\"https://huggingface.co/datasets/Narsil/image_dummy/raw/main/parrots.png\"></a>\n</h3>\n\n```py\nfrom transformers import pipeline\n\npipeline = pipeline(task=\"image-classification\", model=\"facebook/dinov2-small-imagenet1k-1-layer\")\npipeline(\"https://huggingface.co/datasets/Narsil/image_dummy/raw/main/parrots.png\")\n[{'label': 'macaw', 'score': 0.997848391532898},\n {'label': 'sulphur-crested cockatoo, Kakatoe galerita, Cacatua galerita',\n 'score': 0.0016551691805943847},\n {'label': 'lorikeet', 'score': 0.00018523589824326336},\n {'label': 'African grey, African gray, Psittacus erithacus',\n 'score': 7.85409429227002e-05},\n {'label': 'quail', 'score': 5.502637941390276e-05}]\n```\n\n</details>\n\n<details>\n<summary>Visual question answering</summary>\n\n<h3 align=\"center\">\n <a><img src=\"https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/transformers/tasks/idefics-few-shot.jpg\"></a>\n</h3>\n\n```py\nfrom transformers import pipeline\n\npipeline = pipeline(task=\"visual-question-answering\", model=\"Salesforce/blip-vqa-base\")\npipeline(\n image=\"https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/transformers/tasks/idefics-few-shot.jpg\",\n question=\"What is in the image?\",\n)\n[{'answer': 'statue of liberty'}]\n```\n\n</details>\n\n## Why should I use Transformers?\n\n1. Easy-to-use state-of-the-art models:\n - High performance on natural language understanding & generation, computer vision, audio, video, and multimodal tasks.\n - Low barrier to entry for researchers, engineers, and developers.\n - Few user-facing abstractions with just three classes to learn.\n - A unified API for using all our pretrained models.\n\n1. Lower compute costs, smaller carbon footprint:\n - Share trained models instead of training from scratch.\n - Reduce compute time and production costs.\n - Hundreds of model architectures with 1M+ pretrained checkpoints across all modalities.\n\n1. Choose the right framework for every part of a model's lifetime:\n - Train state-of-the-art models in 3 lines of code.\n - Move a single model between PyTorch/JAX/TF2.0 frameworks at will.\n - Pick the right framework for training, evaluation, and production.\n\n1. Easily customize a model or an example to your needs:\n - We provide examples for each architecture to reproduce the results published by its original authors.\n - Model internals are exposed as consistently as possible.\n - Model files can be used independently of the library for quick experiments.\n\n<a target=\"_blank\" href=\"https://huggingface.co/enterprise\">\n <img alt=\"Hugging Face Enterprise Hub\" src=\"https://github.com/user-attachments/assets/247fb16d-d251-4583-96c4-d3d76dda4925\">\n</a><br>\n\n## When shouldn't I use Transformers?\n\n- This library is not a modular toolbox of building blocks for neural nets. The code in the model files is not refactored with additional abstractions on purpose, so that researchers can quickly iterate on each of the models without diving into additional abstractions/files.\n- The training API is optimized to work with PyTorch models provided by Transformers. For generic machine learning loops, you should use another library like [Accelerate](https://huggingface.co/docs/accelerate).\n- The [example scripts](https://github.com/huggingface/transformers/tree/main/examples) are only *examples*. They may not necessarily work out-of-the-box on your specific use case and you'll need to adapt the code for it to work.\n\n## 100 projects using Transformers\n\nTransformers is more than a toolkit to use pretrained models, it's a community of projects built around it and the\nHugging Face Hub. We want Transformers to enable developers, researchers, students, professors, engineers, and anyone\nelse to build their dream projects.\n\nIn order to celebrate Transformers 100,000 stars, we wanted to put the spotlight on the\ncommunity with the [awesome-transformers](./awesome-transformers.md) page which lists 100\nincredible projects built with Transformers.\n\nIf you own or use a project that you believe should be part of the list, please open a PR to add it!\n\n## Example models\n\nYou can test most of our models directly on their [Hub model pages](https://huggingface.co/models).\n\nExpand each modality below to see a few example models for various use cases.\n\n<details>\n<summary>Audio</summary>\n\n- Audio classification with [CLAP](https://huggingface.co/laion/clap-htsat-fused)\n- Automatic speech recognition with [Parakeet](https://huggingface.co/nvidia/parakeet-ctc-1.1b#transcribing-using-transformers-%F0%9F%A4%97), [Whisper](https://huggingface.co/openai/whisper-large-v3-turbo), [GLM-ASR](https://huggingface.co/zai-org/GLM-ASR-Nano-2512) and [Moonshine-Streaming](https://huggingface.co/UsefulSensors/moonshine-streaming-medium)\n- Keyword spotting with [Wav2Vec2](https://huggingface.co/superb/wav2vec2-base-superb-ks)\n- Speech to speech generation with [Moshi](https://huggingface.co/kyutai/moshiko-pytorch-bf16)\n- Text to audio with [MusicGen](https://huggingface.co/facebook/musicgen-large)\n- Text to speech with [CSM](https://huggingface.co/sesame/csm-1b)\n\n</details>\n\n<details>\n<summary>Computer vision</summary>\n\n- Automatic mask generation with [SAM](https://huggingface.co/facebook/sam-vit-base)\n- Depth estimation with [DepthPro](https://huggingface.co/apple/DepthPro-hf)\n- Image classification with [DINO v2](https://huggingface.co/facebook/dinov2-base)\n- Keypoint detection with [SuperPoint](https://huggingface.co/magic-leap-community/superpoint)\n- Keypoint matching with [SuperGlue](https://huggingface.co/magic-leap-community/superglue_outdoor)\n- Object detection with [RT-DETRv2](https://huggingface.co/PekingU/rtdetr_v2_r50vd)\n- Pose Estimation with [VitPose](https://huggingface.co/usyd-community/vitpose-base-simple)\n- Universal segmentation with [OneFormer](https://huggingface.co/shi-labs/oneformer_ade20k_swin_large)\n- Video classification with [VideoMAE](https://huggingface.co/MCG-NJU/videomae-large)\n\n</details>\n\n<details>\n<summary>Multimodal</summary>\n\n- Audio or text to text with [Voxtral](https://huggingface.co/mistralai/Voxtral-Mini-3B-2507), [Audio Flamingo](https://huggingface.co/nvidia/audio-flamingo-3-hf)\n- Document question answering with [LayoutLMv3](https://huggingface.co/microsoft/layoutlmv3-base)\n- Image or text to text with [Qwen-VL](https://huggingface.co/Qwen/Qwen2.5-VL-3B-Instruct)\n- Image captioning [BLIP-2](https://huggingface.co/Salesforce/blip2-opt-2.7b)\n- OCR-based document understanding with [GOT-OCR2](https://huggingface.co/stepfun-ai/GOT-OCR-2.0-hf)\n- Table question answering with [TAPAS](https://huggingface.co/google/tapas-base)\n- Unified multimodal understanding and generation with [Emu3](https://huggingface.co/BAAI/Emu3-Gen)\n- Vision to text with [Llava-OneVision](https://huggingface.co/llava-hf/llava-onevision-qwen2-0.5b-ov-hf)\n- Visual question answering with [Llava](https://huggingface.co/llava-hf/llava-1.5-7b-hf)\n- Visual referring expression segmentation with [Kosmos-2](https://huggingface.co/microsoft/kosmos-2-patch14-224)\n\n</details>\n\n<details>\n<summary>NLP</summary>\n\n- Masked word completion with [ModernBERT](https://huggingface.co/answerdotai/ModernBERT-base)\n- Named entity recognition with [Gemma](https://huggingface.co/google/gemma-2-2b)\n- Question answering with [Mixtral](https://huggingface.co/mistralai/Mixtral-8x7B-v0.1)\n- Summarization with [BART](https://huggingface.co/facebook/bart-large-cnn)\n- Translation with [T5](https://huggingface.co/google-t5/t5-base)\n- Text generation with [Llama](https://huggingface.co/meta-llama/Llama-3.2-1B)\n- Text classification with [Qwen](https://huggingface.co/Qwen/Qwen2.5-0.5B)\n\n</details>\n\n## Citation\n\nWe now have a [paper](https://aclanthology.org/2020.emnlp-demos.6/) you can cite for the 🤗 Transformers library:\n```bibtex\n@inproceedings{wolf-etal-2020-transformers,\n title = \"Transformers: State-of-the-Art Natural Language Processing\",\n author = \"Thomas Wolf and Lysandre Debut and Victor Sanh and Julien Chaumond and Clement Delangue and Anthony Moi and Pierric Cistac and Tim Rault and Rémi Louf and Morgan Funtowicz and Joe Davison and Sam Shleifer and Patrick von Platen and Clara Ma and Yacine Jernite and Julien Plu and Canwen Xu and Teven Le Scao and Sylvain Gugger and Mariama Drame and Quentin Lhoest and Alexander M. Rush\",\n booktitle = \"Proceedings of the 2020 Conference on Empirical Methods in Natural Language Processing: System Demonstrations\",\n month = oct,\n year = \"2020\",\n address = \"Online\",\n publisher = \"Association for Computational Linguistics\",\n url = \"https://aclanthology.org/2020.emnlp-demos.6/\",\n pages = \"38--45\"\n}\n```",
"readme_text":"<div align=\"center\">\n <a href=\"https://docs.langchain.com/oss/python/langchain/overview\">\n <picture>\n <source media=\"(prefers-color-scheme: dark)\" srcset=\".github/images/logo-dark.svg\">\n <source media=\"(prefers-color-scheme: light)\" srcset=\".github/images/logo-light.svg\">\n <img alt=\"LangChain Logo\" src=\".github/images/logo-dark.svg\" width=\"50%\">\n </picture>\n </a>\n</div>\n\n<div align=\"center\">\n <h3>The agent engineering platform.</h3>\n</div>\n\n<div align=\"center\">\n <a href=\"https://opensource.org/licenses/MIT\" target=\"_blank\"><img src=\"https://img.shields.io/pypi/l/langchain\" alt=\"PyPI - License\"></a>\n <a href=\"https://pypistats.org/packages/langchain\" target=\"_blank\"><img src=\"https://img.shields.io/pepy/dt/langchain\" alt=\"PyPI - Downloads\"></a>\n <a href=\"https://pypi.org/project/langchain/#history\" target=\"_blank\"><img src=\"https://img.shields.io/pypi/v/langchain?label=%20\" alt=\"Version\"></a>\n <a href=\"https://x.com/langchain_oss\" target=\"_blank\"><img src=\"https://img.shields.io/twitter/url/https/twitter.com/langchain_oss.svg?style=social&label=Follow%20%40LangChain\" alt=\"Twitter / X\"></a>\n</div>\n\n<br>\n\nLangChain is a framework for building agents and LLM-powered applications. It helps you chain together interoperable components and third-party integrations to simplify AI application development — all while future-proofing decisions as the underlying technology evolves.\n\n> [!TIP]\n> Just getting started? Check out **[Deep Agents](http://docs.langchain.com/oss/python/deepagents/)** — a higher-level package built on LangChain for agents that have built-in capabilites for common usage patterns such as planning, subagents, file system usage, and more.\n\n## Quickstart\n\n```bash\nuv add langchain\n```\n\n```python\nfrom langchain.chat_models import init_chat_model\n\nmodel = init_chat_model(\"openai:gpt-5.5\")\nresult = model.invoke(\"Hello, world!\")\n```\n\nIf you're looking for more advanced customization or agent orchestration, check out [LangGraph](https://github.com/langchain-ai/langgraph), our framework for building controllable agent workflows.\n\nFor an equivalent JS/TS library, check out [LangChain.js](https://github.com/langchain-ai/langchainjs).\n\n> [!TIP]\n> For developing, debugging, and deploying AI agents and LLM applications, see [LangSmith](https://docs.langchain.com/langsmith/home).\n\n## LangChain ecosystem\n\nWhile the LangChain framework can be used standalone, it also integrates seamlessly with any LangChain product, giving developers a full suite of tools when building LLM applications.\n\n- **[Deep Agents](http://docs.langchain.com/oss/python/deepagents/)** — Build agents that can plan, use subagents, and leverage file systems for complex tasks\n- **[LangGraph](https://docs.langchain.com/oss/python/langgraph/overview)** — Build agents that can reliably handle complex tasks with our low-level agent orchestration framework\n- **[Integrations](https://docs.langchain.com/oss/python/integrations/providers/overview)** — Chat & embedding models, tools & toolkits, and more\n- **[LangSmith](https://www.langchain.com/langsmith)** — Agent evals, observability, and debugging for LLM apps\n- **[LangSmith Deployment](https://docs.langchain.com/langsmith/deployments)** — Deploy and scale agents with a purpose-built platform for long-running, stateful workflows\n\n## Why use LangChain?\n\nLangChain helps developers build applications powered by LLMs through a standard interface for models, embeddings, vector stores, and more.\n\n- **Real-time data augmentation** — Easily connect LLMs to diverse data sources and external/internal systems, drawing from LangChain's vast library of integrations with model providers, tools, vector stores, retrievers, and more\n- **Model interoperability** — Swap models in and out as your engineering team experiments to find the best choice for your application's needs. As the industry frontier evolves, adapt quickly — LangChain's abstractions keep you moving without losing momentum\n- **Rapid prototyping** — Quickly build and iterate on LLM applications with LangChain's modular, component-based architecture. Test different approaches and workflows without rebuilding from scratch, accelerating your development cycle\n- **Production-ready features** — Deploy reliable applications with built-in support for monitoring, evaluation, and debugging through integrations like LangSmith. Scale with confidence using battle-tested patterns and best practices\n- **Vibrant community and ecosystem** — Leverage a rich ecosystem of integrations, templates, and community-contributed components. Benefit from continuous improvements and stay up-to-date with the latest AI developments through an active open-source community\n- **Flexible abstraction layers** — Work at the level of abstraction that suits your needs — from high-level chains for quick starts to low-level components for fine-grained control. LangChain grows with your application's complexity\n\n---\n\n## Resources\n\n- [Documentation](https://docs.langchain.com/oss/python/langchain/overview) — conceptual overviews and guides\n- [LangChain ecosystem overview](https://docs.langchain.com/oss/python/concepts/products) — how LangChain, LangGraph, and Deep Agents fit together\n- [API reference](https://reference.langchain.com/python) — complete reference for all public classes, functions, and types\n- [Discussions](https://forum.langchain.com/c/oss-product-help-lc-and-lg/langchain/14) — community forum for technical questions, ideas, and feedback\n- [LangChain Academy](https://academy.langchain.com/) — comprehensive, free courses on LangChain libraries and products, made by the LangChain team\n- [Contributing Guide](https://docs.langchain.com/oss/python/contributing/overview) — how to contribute and find good first issues\n- [Code of Conduct](https://github.com/langchain-ai/langchain/?tab=coc-ov-file) — community guidelines and standards",
"readme_text":"# Visual Studio Code - Open Source (\"Code - OSS\")\n[](https://github.com/microsoft/vscode/issues?q=is%3Aopen+is%3Aissue+label%3Afeature-request+sort%3Areactions-%2B1-desc)\n[](https://github.com/microsoft/vscode/issues?utf8=✓&q=is%3Aissue+is%3Aopen+label%3Abug)\n[](https://gitter.im/Microsoft/vscode)\n\n## The Repository\n\nThis repository (\"`Code - OSS`\") is where we (Microsoft) develop the [Visual Studio Code](https://code.visualstudio.com) product together with the community. Not only do we work on code and issues here, but we also publish our [roadmap](https://github.com/microsoft/vscode/wiki/Roadmap), [monthly iteration plans](https://github.com/microsoft/vscode/wiki/Iteration-Plans), and our [endgame plans](https://github.com/microsoft/vscode/wiki/Running-the-Endgame). This source code is available to everyone under the standard [MIT license](https://github.com/microsoft/vscode/blob/main/LICENSE.txt).\n\n## Visual Studio Code\n\n<p align=\"center\">\n <img alt=\"VS Code in action\" src=\"https://github.com/user-attachments/assets/56af271c-949d-454c-a3ea-16188c063414\">\n</p>\n\n[Visual Studio Code](https://code.visualstudio.com) is a distribution of the `Code - OSS` repository with Microsoft-specific customizations released under a traditional [Microsoft product license](https://code.visualstudio.com/License/).\n\n[Visual Studio Code](https://code.visualstudio.com) combines the simplicity of a code editor with what developers need for their core edit-build-debug cycle. It provides comprehensive code editing, navigation, and understanding support along with lightweight debugging, a rich extensibility model, and lightweight integration with existing tools.\n\nVisual Studio Code is updated monthly with new features and bug fixes. You can download it for Windows, macOS, and Linux on [Visual Studio Code's website](https://code.visualstudio.com/Download). To get the latest releases every day, install the [Insiders build](https://code.visualstudio.com/insiders).\n\n## Contributing\n\nThere are many ways in which you can participate in this project, for example:\n\n* [Submit bugs and feature requests](https://github.com/microsoft/vscode/issues), and help us verify as they are checked in\n* Review [source code changes](https://github.com/microsoft/vscode/pulls)\n* Review the [documentation](https://github.com/microsoft/vscode-docs) and make pull requests for anything from typos to new content.\n\nIf you are interested in fixing issues and contributing directly to the code base,\nplease see the document [How to Contribute](https://github.com/microsoft/vscode/wiki/How-to-Contribute), which covers the following:\n\n* [How to build and run from source](https://github.com/microsoft/vscode/wiki/How-to-Contribute)\n* [The development workflow, including debugging and running tests](https://github.com/microsoft/vscode/wiki/How-to-Contribute#debugging)\n* [Coding guidelines](https://github.com/microsoft/vscode/wiki/Coding-Guidelines)\n* [Submitting pull requests](https://github.com/microsoft/vscode/wiki/How-to-Contribute#pull-requests)\n* [Finding an issue to work on](https://github.com/microsoft/vscode/wiki/How-to-Contribute#where-to-contribute)\n* [Contributing to translations](https://aka.ms/vscodeloc)\n\n## Feedback\n\n* Ask a question on [Stack Overflow](https://stackoverflow.com/questions/tagged/vscode)\n* [Request a new feature](CONTRIBUTING.md)\n* Upvote [popular feature requests](https://github.com/microsoft/vscode/issues?q=is%3Aopen+is%3Aissue+label%3Afeature-request+sort%3Areactions-%2B1-desc)\n* [File an issue](https://github.com/microsoft/vscode/issues)\n* Connect with the extension author community on [GitHub Discussions](https://github.com/microsoft/vscode-discussions/discussions) or [Slack](https://aka.ms/vscode-dev-community)\n* Follow [@code](https://x.com/code) and let us know what you think!\n\nSee our [wiki](https://github.com/microsoft/vscode/wiki/Feedback-Channels) for a description of each of these channels and information on some other available community-driven channels.\n\n## Related Projects\n\nMany of the core components and extensions to VS Code live in their own repositories on GitHub. For example, the [node debug adapter](https://github.com/microsoft/vscode-node-debug) and the [mono debug adapter](https://github.com/microsoft/vscode-mono-debug) repositories are separate from each other. For a complete list, please visit the [Related Projects](https://github.com/microsoft/vscode/wiki/Related-Projects) page on our [wiki](https://github.com/microsoft/vscode/wiki).\n\n## Bundled Extensions\n\nVS Code includes a set of built-in extensions located in the [extensions](extensions) folder, including grammars and snippets for many languages. Extensions that provide rich language support (inline suggestions, Go to Definition) for a language have the suffix `language-features`. For example, the `json` extension provides coloring for `JSON` and the `json-language-features` extension provides rich language support for `JSON`.\n\n## Development Container\n\nThis repository includes a Visual Studio Code Dev Containers / GitHub Codespaces development container.\n\n* For [Dev Containers](https://aka.ms/vscode-remote/download/containers), use the **Dev Containers: Clone Repository in Container Volume...** command which creates a Docker volume for better disk I/O on macOS and Windows.\n * If you already have VS Code and Docker installed, you can also click [here](https://vscode.dev/redirect?url=vscode://ms-vscode-remote.remote-containers/cloneInVolume?url=https://github.com/microsoft/vscode) to get started. This will cause VS Code to automatically install the Dev Containers extension if needed, clone the source code into a container volume, and spin up a dev container for use.\n\n* For Codespaces, install the [GitHub Codespaces](https://marketplace.visualstudio.com/items?itemName=GitHub.codespaces) extension in VS Code, and use the **Codespaces: Create New Codespace** command.\n\nDocker / the Codespace should have at least **4 cores and 6 GB of RAM (8 GB recommended)** to run a full build. See the [development container README](.devcontainer/README.md) for more information.\n\n## Code of Conduct\n\nThis project has adopted the [Microsoft Open Source Code of Conduct](https://opensource.microsoft.com/codeofconduct/). For more information see the [Code of Conduct FAQ](https://opensource.microsoft.com/codeofconduct/faq/) or contact [opencode@microsoft.com](mailto:opencode@microsoft.com) with any additional questions or comments.\n\n## License\n\nCopyright (c) Microsoft Corporation. All rights reserved.\n\nLicensed under the [MIT](LICENSE.txt) license.",
"readme_text":"<picture>\n <source media=\"(prefers-color-scheme: dark)\" srcset=\"https://github.com/pytorch/pytorch/raw/main/docs/source/_static/img/pytorch-logo-light.png\" />\n <source media=\"(prefers-color-scheme: light)\" srcset=\"https://github.com/pytorch/pytorch/raw/main/docs/source/_static/img/pytorch-logo-dark.png\" />\n <img src=\"https://github.com/pytorch/pytorch/raw/main/docs/source/_static/img/pytorch-logo-dark.png\" alt=\"PyTorch logo\" />\n</picture>\n\n--------------------------------------------------------------------------------\n\nPyTorch is a Python package that provides two high-level features:\n- Tensor computation (like NumPy) with strong GPU acceleration\n- Deep neural networks built on a tape-based autograd system\n\nYou can reuse your favorite Python packages such as NumPy, SciPy, and Cython to extend PyTorch when needed.\n\nOur trunk health (Continuous Integration signals) can be found at [hud.pytorch.org](https://hud.pytorch.org/ci/pytorch/pytorch/main).\n\n<!-- toc -->\n\n- [More About PyTorch](#more-about-pytorch)\n - [A GPU-Ready Tensor Library](#a-gpu-ready-tensor-library)\n - [Dynamic Neural Networks: Tape-Based Autograd](#dynamic-neural-networks-tape-based-autograd)\n - [Python First](#python-first)\n - [Imperative Experiences](#imperative-experiences)\n - [Fast and Lean](#fast-and-lean)\n - [Extensions Without Pain](#extensions-without-pain)\n- [Installation](#installation)\n - [Binaries](#binaries)\n - [NVIDIA Jetson Platforms](#nvidia-jetson-platforms)\n - [From Source](#from-source)\n - [Prerequisites](#prerequisites)\n - [NVIDIA CUDA Support](#nvidia-cuda-support)\n - [AMD ROCm Support](#amd-rocm-support)\n - [Intel GPU Support](#intel-gpu-support)\n - [Get the PyTorch Source](#get-the-pytorch-source)\n - [Install Dependencies](#install-dependencies)\n - [Install PyTorch](#install-pytorch)\n - [Adjust Build Options (Optional)](#adjust-build-options-optional)\n - [Docker Image](#docker-image)\n - [Using pre-built images](#using-pre-built-images)\n - [Building the image yourself](#building-the-image-yourself)\n - [Building the Documentation](#building-the-documentation)\n - [Troubleshooting CI Errors](#troubleshooting-ci-errors)\n - [Building a PDF](#building-a-pdf)\n - [Previous Versions](#previous-versions)\n- [Getting Started](#getting-started)\n- [Resources](#resources)\n- [Communication](#communication)\n- [Releases and Contributing](#releases-and-contributing)\n- [The Team](#the-team)\n- [License](#license)\n\n<!-- tocstop -->\n\n## More About PyTorch\n\n[Learn the basics of PyTorch](https://pytorch.org/tutorials/beginner/basics/intro.html)\n\nAt a granular level, PyTorch is a library that consists of the following components:\n\n| Component | Description |\n| ---- | --- |\n| [**torch**](https://pytorch.org/docs/stable/torch.html) | A Tensor library like NumPy, with strong GPU support |\n| [**torch.autograd**](https://pytorch.org/docs/stable/autograd.html) | A tape-based automatic differentiation library that supports all differentiable Tensor operations in torch |\n| [**torch.jit**](https://pytorch.org/docs/stable/jit.html) | A compilation stack (TorchScript) to create serializable and optimizable models from PyTorch code |\n| [**torch.nn**](https://pytorch.org/docs/stable/nn.html) | A neural networks library deeply integrated with autograd designed for maximum flexibility |\n| [**torch.multiprocessing**](https://pytorch.org/docs/stable/multiprocessing.html) | Python multiprocessing, but with magical memory sharing of torch Tensors across processes. Useful for data loading and Hogwild training |\n| [**torch.utils**](https://pytorch.org/docs/stable/data.html) | DataLoader and other utility functions for convenience |\n\nUsually, PyTorch is used either as:\n\n- A replacement for NumPy to use the power of GPUs.\n- A deep learning research platform that provides maximum flexibility and speed.\n\nElaborating Further:\n\n### A GPU-Ready Tensor Library\n\nIf you use NumPy, then you have used Tensors (a.k.a. ndarray).\n\n\n\nPyTorch provides Tensors that can live either on the CPU or the GPU and accelerates the\ncomputation by a huge amount.\n\nWe provide a wide variety of tensor routines to accelerate and fit your scientific computation needs\nsuch as slicing, indexing, mathematical operations, linear algebra, reductions.\nAnd they are fast!\n\n### Dynamic Neural Networks: Tape-Based Autograd\n\nPyTorch has a unique way of building neural networks: using and replaying a tape recorder.\n\nMost frameworks such as TensorFlow, Theano, Caffe, and CNTK have a static view of the world.\nOne has to build a neural network and reuse the same structure again and again.\nChanging the way the network behaves means that one has to start from scratch.\n\nWith PyTorch, we use a technique called reverse-mode auto-differentiation, which allows you to\nchange the way your network behaves arbitrarily with zero lag or overhead. Our inspiration comes\nfrom several research papers on this topic, as well as current and past work such as\n[torch-autograd](https://github.com/twitter/torch-autograd),\n[autograd](https://github.com/HIPS/autograd),\n[Chainer](https://chainer.org), etc.\n\nWhile this technique is not unique to PyTorch, it's one of the fastest implementations of it to date.\nYou get the best of speed and flexibility for your crazy research.\n\n\n\n### Python First\n\nPyTorch is not a Python binding into a monolithic C++ framework.\nIt is built to be deeply integrated into Python.\nYou can use it naturally like you would use [NumPy](https://www.numpy.org/) / [SciPy](https://www.scipy.org/) / [scikit-learn](https://scikit-learn.org) etc.\nYou can write your new neural network layers in Python itself, using your favorite libraries\nand use packages such as [Cython](https://cython.org/) and [Numba](http://numba.pydata.org/).\nOur goal is to not reinvent the wheel where appropriate.\n\n### Imperative Experiences\n\nPyTorch is designed to be intuitive, linear in thought, and easy to use.\nWhen you execute a line of code, it gets executed. There isn't an asynchronous view of the world.\nWhen you drop into a debugger or receive error messages and stack traces, understanding them is straightforward.\nThe stack trace points to exactly where your code was defined.\nWe hope you never spend hours debugging your code because of bad stack traces or asynchronous and opaque execution engines.\n\n### Fast and Lean\n\nPyTorch has minimal framework overhead. We integrate acceleration libraries\nsuch as [Intel MKL](https://software.intel.com/mkl) and NVIDIA ([cuDNN](https://developer.nvidia.com/cudnn), [NCCL](https://developer.nvidia.com/nccl)) to maximize speed.\nAt the core, its CPU and GPU Tensor and neural network backends\nare mature and have been tested for years.\n\nHence, PyTorch is quite fast — whether you run small or large neural networks.\n\nThe memory usage in PyTorch is extremely efficient compared to Torch or some of the alternatives.\nWe've written custom memory allocators for the GPU to make sure that\nyour deep learning models are maximally memory efficient.\nThis enables you to train bigger deep learning models than before.\n\n### Extensions Without Pain\n\nWriting new neural network modules, or interfacing with PyTorch's Tensor API, was designed to be straightforward\nand with minimal abstractions.\n\nYou can write new neural network layers in Python using the torch API\n[or your favorite NumPy-based libraries such as SciPy](https://pytorch.org/tutorials/advanced/numpy_extensions_tutorial.html).\n\nIf you want to write your layers in C/C++, we provide a convenient extension API that is efficient and with minimal boilerplate.\nNo wrapper code needs to be written. You can see [a tutorial here](https://pytorch.org/tutorials/advanced/cpp_extension.html) and [an example here](https://github.com/pytorch/extension-cpp).\n\n\n## Installation\n\n### Binaries\nCommands to install binaries via Conda or pip wheels are on our website: [https://pytorch.org/get-started/locally/](https://pytorch.org/get-started/locally/)\n\n\n#### NVIDIA Jetson Platforms\n\nPython wheels for NVIDIA's Jetson Nano, Jetson TX1/TX2, Jetson Xavier NX/AGX, and Jetson AGX Orin are provided [here](https://forums.developer.nvidia.com/t/pytorch-for-jetson-version-1-10-now-available/72048) and the L4T container is published [here](https://catalog.ngc.nvidia.com/orgs/nvidia/containers/l4t-pytorch)\n\nThey require JetPack 4.2 and above, and [@dusty-nv](https://github.com/dusty-nv) and [@ptrblck](https://github.com/ptrblck) are maintaining them.\n\n\n### From Source\n\n#### Prerequisites\nIf you are installing from source, you will need:\n- Python 3.10 or later\n- A compiler that fully supports C++20, such as clang or gcc (gcc 11.3.0 or newer is required, on Linux)\n- Visual Studio or Visual Studio Build Tool (Windows only)\n- At least 10 GB of free disk space\n- 30-60 minutes for the initial build (subsequent rebuilds are much faster)\n\n\\* PyTorch CI uses Visual C++ BuildTools, which come with Visual Studio Enterprise,\nProfessional, or Community Editions. You can also install the build tools from\nhttps://visualstudio.microsoft.com/visual-cpp-build-tools/. The build tools *do not*\ncome with Visual Studio Code by default.\n\nAn example of environment setup is shown below:\n\n* Linux:\n\n```bash\n$ source <CONDA_INSTALL_DIR>/bin/activate\n$ conda create -y -n <CONDA_NAME>\n$ conda activate <CONDA_NAME>\n```\n* Windows:\n\n```bash\n$ source <CONDA_INSTALL_DIR>\\Scripts\\activate.bat\n$ conda create -y -n <CONDA_NAME>\n$ conda activate <CONDA_NAME>\n$ call \"C:\\Program Files\\Microsoft Visual Studio\\<VERSION>\\Community\\VC\\Auxiliary\\Build\\vcvarsall.bat\" x64\n```\n\nA conda environment is not required. You can also do a PyTorch build in a\nstandard virtual environment, e.g., created with tools like `uv`, provided\nyour system has installed all the necessary dependencies unavailable as pip\npackages (e.g., CUDA, MKL.)\n\n##### NVIDIA CUDA Support\nIf you want to compile with CUDA support, [select a supported version of CUDA from our support matrix](https://pytorch.org/get-started/locally/), then install the following:\n- [NVIDIA CUDA](https://developer.nvidia.com/cuda-downloads)\n- [NVIDIA cuDNN](https://developer.nvidia.com/cudnn) v9.0 or above\n- [Compiler](https://gist.github.com/ax3l/9489132) compatible with CUDA\n\nNote: You could refer to the [cuDNN Support Matrix](https://docs.nvidia.com/deeplearning/cudnn/backend/latest/reference/support-matrix.html) for cuDNN versions with the various supported CUDA, CUDA driver, and NVIDIA hardware.\n\nIf you want to disable CUDA support, export the environment variable `USE_CUDA=0`.\nOther potentially useful environment variables may be found in `setup.py`. If\nCUDA is installed in a non-standard location, set PATH so that the nvcc you\nwant to use can be found (e.g., `export PATH=/usr/local/cuda-12.8/bin:$PATH`).\n\nIf you are building for NVIDIA's Jetson platforms (Jetson Nano, TX1, TX2, AGX Xavier), Instructions to install PyTorch for Jetson Nano are [available here](https://devtalk.nvidia.com/default/topic/1049071/jetson-nano/pytorch-for-jetson-nano/)\n\n##### AMD ROCm Support\nIf you want to compile with ROCm support, install\n- [AMD ROCm](https://rocm.docs.amd.com/en/latest/deploy/linux/quick_start.html) 4.0 and above installation\n- ROCm is currently supported only for Linux systems.\n\nBy default the build system expects ROCm to be installed in `/opt/rocm`. If ROCm is installed in a different directory, the `ROCM_PATH` environment variable must be set to the ROCm installation directory. The build system automatically detects the AMD GPU architecture. Optionally, the AMD GPU architecture can be explicitly set with the `PYTORCH_ROCM_ARCH` environment variable [AMD GPU architecture](https://rocm.docs.amd.com/projects/install-on-linux/en/latest/reference/system-requirements.html#supported-gpus)\n\nIf you want to disable ROCm support, export the environment variable `USE_ROCM=0`.\nOther potentially useful environment variables may be found in `setup.py`.\n\n##### Intel GPU Support\nIf you want to compile with Intel GPU support, follow these\n- [PyTorch Prerequisites for Intel GPUs](https://www.intel.com/content/www/us/en/developer/articles/tool/pytorch-prerequisites-for-intel-gpu.html) instructions.\n- Intel GPU is supported for Linux and Windows.\n\nIf you want to disable Intel GPU support, export the environment variable `USE_XPU=0`.\nOther potentially useful environment variables may be found in `setup.py`.\n\n#### Get the PyTorch Source\n\n```bash\ngit clone https://github.com/pytorch/pytorch\ncd pytorch\n# if you are updating an existing checkout\ngit submodule sync\ngit submodule update --init --recursive\n```\n\n#### Install Dependencies\n\n**Common**\n\n```bash\n# Run this command from the PyTorch directory after cloning the source code using the “Get the PyTorch Source“ section above\npip install --group dev\n```\n\n**On Linux**\n\n```bash\npip install mkl-static mkl-include\n# CUDA only: Add LAPACK support for the GPU if needed\n# magma installation: run with active conda environment. specify CUDA version to install\n.ci/docker/common/install_magma_conda.sh 12.4\n\n# (optional) If using torch.compile with inductor/triton, install the matching version of triton\n# Run from the pytorch directory after cloning\n# For Intel GPU support, please explicitly `export USE_XPU=1` before running command.\nmake triton\n```\n\n**On Windows**\n\n```bash\npip install mkl-static mkl-include\n# Add these packages if torch.distributed is needed.\n# Distributed package support on Windows is a prototype feature and is subject to changes.\nconda install -c conda-forge libuv=1.51\n```\n\n#### Install PyTorch\n\n**On Linux**\n\nIf you're compiling for AMD ROCm then first run this command:\n\n```bash\n# Only run this if you're compiling for ROCm\npython tools/amd_build/build_amd.py\n```\n\nInstall PyTorch\n\n```bash\n# the CMake prefix for conda environment\nexport CMAKE_PREFIX_PATH=\"${CONDA_PREFIX:-'$(dirname $(which conda))/../'}:${CMAKE_PREFIX_PATH}\"\npython -m pip install --no-build-isolation -v -e .\n\n# the CMake prefix for non-conda environment, e.g. Python venv\n# call following after activating the venv\nexport CMAKE_PREFIX_PATH=\"${VIRTUAL_ENV}:${CMAKE_PREFIX_PATH}\"\n```\n\n**On macOS**\n\n```bash\npython -m pip install --no-build-isolation -v -e .\n```\n\n**On Windows**\n\nIf you want to build legacy python code, please refer to [Building on legacy code and CUDA](https://github.com/pytorch/pytorch/blob/main/CONTRIBUTING.md#building-on-legacy-code-and-cuda)\n\n**CPU-only builds**\n\nIn this mode PyTorch computations will run on your CPU, not your GPU.\n\n```cmd\npython -m pip install --no-build-isolation -v -e .\n```\n\nNote on OpenMP: The desired OpenMP implementation is Intel OpenMP (iomp). In order to link against iomp, you'll need to manually download the library and set up the building environment by tweaking `CMAKE_INCLUDE_PATH` and `LIB`. The instruction [here](https://docs.pytorch.org/docs/main/notes/windows.html#building-from-source) is an example for setting up both MKL and Intel OpenMP. Without these configurations for CMake, Microsoft Visual C OpenMP runtime (vcomp) will be used.\n\n**CUDA based build**\n\nIn this mode PyTorch computations will leverage your GPU via CUDA for faster number crunching\n\n[NVTX](https://docs.nvidia.com/gameworks/content/gameworkslibrary/nvtx/nvidia_tools_extension_library_nvtx.htm) is needed to build PyTorch with CUDA.\nNVTX is a part of CUDA distributive, where it is called \"Nsight Compute\". To install it onto an already installed CUDA run CUDA installation once again and check the corresponding checkbox.\nMake sure that CUDA with Nsight Compute is installed after Visual Studio.\n\nCurrently, VS 2017 / 2019, and Ninja are supported as the generator of CMake. If `ninja.exe` is detected in `PATH`, then Ninja will be used as the default generator, otherwise, it will use VS 2017 / 2019.\n<br/> If Ninja is selected as the generator, the latest MSVC will get selected as the underlying toolchain.\n\nAdditional libraries such as\n[Magma](https://developer.nvidia.com/magma), [oneDNN, a.k.a. MKLDNN or DNNL](https://github.com/oneapi-src/oneDNN), and [Sccache](https://github.com/mozilla/sccache) are often needed. Please refer to the [installation-helper](https://github.com/pytorch/pytorch/tree/main/.ci/pytorch/win-test-helpers/installation-helpers) to install them.\n\nYou can refer to the [build_pytorch.bat](https://github.com/pytorch/pytorch/blob/main/.ci/pytorch/win-test-helpers/build_pytorch.bat) script for some other environment variables configurations\n\n```cmd\ncmd\n\n:: Set the environment variables after you have downloaded and unzipped the mkl package,\n:: else CMake would throw an error as `Could NOT find OpenMP`.\nset CMAKE_INCLUDE_PATH={Your directory}\\mkl\\include\nset LIB={Your directory}\\mkl\\lib;%LIB%\n\n:: Read the content in the previous section carefully before you proceed.\n:: [Optional] If you want to override the underlying toolset used by Ninja and Visual Studio with CUDA, please run the following script block.\n:: \"Visual Studio 2019 Developer Command Prompt\" will be run automatically.\n:: Make sure you have CMake >= 3.12 before you do this when you use the Visual Studio generator.\nset CMAKE_GENERATOR_TOOLSET_VERSION=14.27\nset DISTUTILS_USE_SDK=1\nfor /f \"usebackq tokens=*\" %i in (`\"%ProgramFiles(x86)%\\Microsoft Visual Studio\\Installer\\vswhere.exe\" -version [15^,17^) -products * -latest -property installationPath`) do call \"%i\\VC\\Auxiliary\\Build\\vcvarsall.bat\" x64 -vcvars_ver=%CMAKE_GENERATOR_TOOLSET_VERSION%\n\n:: [Optional] If you want to override the CUDA host compiler\nset CUDAHOSTCXX=C:\\Program Files (x86)\\Microsoft Visual Studio\\2019\\Community\\VC\\Tools\\MSVC\\14.27.29110\\bin\\HostX64\\x64\\cl.exe\n\npython -m pip install --no-build-isolation -v -e .\n```\n\n**Intel GPU builds**\n\nIn this mode PyTorch with Intel GPU support will be built.\n\nPlease make sure [the common prerequisites](#prerequisites) as well as [the prerequisites for Intel GPU](#intel-gpu-support) are properly installed and the environment variables are configured prior to starting the build. For build tool support, `Visual Studio 2022` is required.\n\nThen PyTorch can be built with the command:\n\n```cmd\n:: CMD Commands:\n:: Set the CMAKE_PREFIX_PATH to help find corresponding packages\n:: %CONDA_PREFIX% only works after `conda activate custom_env`\n\nif defined CMAKE_PREFIX_PATH (\n set \"CMAKE_PREFIX_PATH=%CONDA_PREFIX%\\Library;%CMAKE_PREFIX_PATH%\"\n) else (\n set \"CMAKE_PREFIX_PATH=%CONDA_PREFIX%\\Library\"\n)\n\npython -m pip install --no-build-isolation -v -e .\n```\n\n##### Adjust Build Options (Optional)\n\nYou can adjust the configuration of cmake variables optionally (without building first), by doing\nthe following. For example, adjusting the pre-detected directories for CuDNN or BLAS can be done\nwith such a step.\n\nOn Linux\n\n```bash\nexport CMAKE_PREFIX_PATH=\"${CONDA_PREFIX:-'$(dirname $(which conda))/../'}:${CMAKE_PREFIX_PATH}\"\nCMAKE_ONLY=1 python setup.py build\nccmake build # or cmake-gui build\n```\n\nOn macOS\n\n```bash\nexport CMAKE_PREFIX_PATH=\"${CONDA_PREFIX:-'$(dirname $(which conda))/../'}:${CMAKE_PREFIX_PATH}\"\nMACOSX_DEPLOYMENT_TARGET=11.0 CMAKE_ONLY=1 python setup.py build\nccmake build # or cmake-gui build\n```\n\n### Docker Image\n\n#### Using pre-built images\n\nYou can also pull a pre-built docker image from Docker Hub and run with docker v23.0+\n\n```bash\ndocker run --gpus all --rm -ti --ipc=host pytorch/pytorch:latest\n```\n\nPlease note that PyTorch uses shared memory to share data between processes, so if torch multiprocessing is used (e.g.\nfor multithreaded data loaders) the default shared memory segment size that container runs with is not enough, and you\nshould increase shared memory size either with `--ipc=host` or `--shm-size` command line options to `nvidia-docker run`.\n\n#### Building the image yourself\n\n**NOTE:** Must be built with a Docker version >= 23.0\n\nThe Dockerfile is supplied to build images with CUDA 12.1 support and cuDNN v9.\nYou can pass `PYTHON_VERSION=x.y` make variable to specify which Python version is to be used by Miniconda, or leave it\nunset to use the default, as the Dockerfile uses system Python.\n\n```bash\nmake -f docker.Makefile\n# images are tagged as docker.io/${your_docker_username}/pytorch\n```\n\nYou can also pass the `CMAKE_VARS=\"...\"` environment variable to specify additional CMake variables to be passed to CMake during the build.\nSee [setup.py](./setup.py) for the list of available variables.\n\n```bash\nmake -f docker.Makefile\n```\n\n### Building the Documentation\n\nTo build documentation in various formats, you will need [Sphinx](http://www.sphinx-doc.org)\nand the `pytorch_sphinx_theme2`.\n\nBefore you build the documentation locally, ensure `torch` is\ninstalled in your environment. For small fixes, you can install the\nnightly version as described in [Getting Started](https://pytorch.org/get-started/locally/).\n\nFor more complex fixes, such as adding a new module and docstrings for\nthe new module, you might need to install torch [from source](#from-source).\nSee [Docstring Guidelines](https://github.com/pytorch/pytorch/wiki/Docstring-Guidelines)\nfor docstring conventions.\n\n```bash\ncd docs/\npip install -r requirements.txt\nmake html\nmake serve\n```\n\nRun `make` to get a list of all available output formats.\n\nIf you get a katex error run `npm install katex`. If it persists, try\n`npm install -g katex`\n\n> [!NOTE]\n> If you see a numpy incompatibility error, run:\n> ```\n> pip install 'numpy<2'\n> ```\n\n\n#### Troubleshooting CI Errors\nYour build may show errors you didn't have locally - here's how to find the errors relevant to the docs.\n\nIf the build has any errors, you will see something like this on the PR:\n\n<img width=\"781\" height=\"400\" alt=\"Monosnap Update installation instructions for doc build · Pull Request #169534 · pytorch:pytorch 2025-12-18 18-22-53\" src=\"https://github.com/user-attachments/assets/49a3dfe7-81c2-4246-852b-bc3f807e95af\" />\n\nAny doc-related errors will occur in jobs that include \"doc\" somewhere in the title. It doesn't look like any of these jobs are relevant to our docs.\n\n\nLet's take a look anyway. Click on the job to see the logs:\n\n<img width=\"1187\" height=\"668\" alt=\"Monosnap Update installation instructions for doc build · pytorch:pytorch@7380336 2025-12-18 18-24-15\" src=\"https://github.com/user-attachments/assets/117df543-8356-4323-8e1c-ef02a95554ba\" />\n\nAnd we can be sure that this job does not involve docs.\n\nLooking at this build, we can see these jobs are relevant to our docs - and they didn't have any errors:\n\n<img width=\"777\" height=\"395\" alt=\"Check the docs jobs\" src=\"https://github.com/user-attachments/assets/5d7c196b-2d40-49ad-87e3-f57de6e14a5b\" />\n\nYou might also see a comment on the PR like this:\n\n<img width=\"651\" height=\"246\" alt=\"PR Comment\" src=\"https://github.com/user-attachments/assets/27e0120a-ba33-4b1c-b4a5-bf3064520586\" />\n\nWe can see that some of these issues are relevant to our docs.\n\nOpen the logs by clicking on the `gh` link:\n\n<img width=\"873\" height=\"360\" alt=\"View Logs\" src=\"https://github.com/user-attachments/assets/ab5b862f-8026-489c-b95e-a6cd4257e4b7\" />\n\nAnd here we can see there is a doc-related error:\n\n<img width=\"1117\" height=\"433\" alt=\"Doc Error\" src=\"https://github.com/user-attachments/assets/0a275921-736d-43a7-ab0f-3e8854d43280\" />\n\nYou can always find the relevant doc builds by going to the `Checks` tab on your PR, and scrolling down to `pull`.\n\n<img width=\"481\" height=\"561\" alt=\"checks\" src=\"https://github.com/user-attachments/assets/eef18f2b-7134-4e2e-bd90-bcdc12800132\" />\n\nYou can either click through or toggle the accordion to see all of the jobs here, where you can see the docs jobs highlighted:\n\n<img width=\"570\" height=\"611\" alt=\"jobs\" src=\"https://github.com/user-attachments/assets/f62812ca-caee-421b-863c-54f38fd28d46\" />\n\nIf you click through, you'll see the doc jobs at the bottom, like this:\n\n<img width=\"354\" height=\"312\" alt=\"View Docs jobs\" src=\"https://github.com/user-attachments/assets/8fadb935-5314-4c4b-a1b5-133781754f03\" />\n\n\n#### Building a PDF\n\nTo compile a PDF of all PyTorch documentation, ensure you have\n`texlive` and LaTeX installed. On macOS, you can install them using:\n\n```\nbrew install --cask mactex\n```\n\nTo create the PDF:\n\n1. Run:\n\n ```\n make latexpdf\n ```\n\n This will generate the necessary files in the `build/latex` directory.\n\n2. Navigate to this directory and execute:\n\n ```\n make LATEXOPTS=\"-interaction=nonstopmode\"\n ```\n\n This will produce a `pytorch.pdf` with the desired content. Run this\n command one more time so that it generates the correct table\n of contents and index.\n\n> [!NOTE]\n> To view the Table of Contents, switch to the **Table of Contents**\n> view in your PDF viewer.\n\n\n### Previous Versions\n\nInstallation instructions and binaries for previous PyTorch versions may be found\non [our website](https://pytorch.org/get-started/previous-versions).\n\n\n## Getting Started\n\nPointers to get you started:\n- [Tutorials: get you started with understanding and using PyTorch](https://pytorch.org/tutorials/)\n- [Examples: easy to understand PyTorch code across all domains](https://github.com/pytorch/examples)\n- [The API Reference](https://pytorch.org/docs/)\n- [Glossary](https://github.com/pytorch/pytorch/blob/main/GLOSSARY.md)\n\n## Resources\n\n* [PyTorch.org](https://pytorch.org/)\n* [PyTorch Tutorials](https://pytorch.org/tutorials/)\n* [PyTorch Examples](https://github.com/pytorch/examples)\n* [PyTorch Models](https://pytorch.org/hub/)\n* [Intro to Deep Learning with PyTorch from Udacity](https://www.udacity.com/course/deep-learning-pytorch--ud188)\n* [Intro to Machine Learning with PyTorch from Udacity](https://www.udacity.com/course/intro-to-machine-learning-nanodegree--nd229)\n* [Deep Neural Networks with PyTorch from Coursera](https://www.coursera.org/learn/deep-neural-networks-with-pytorch)\n* [PyTorch Twitter](https://twitter.com/PyTorch)\n* [PyTorch Blog](https://pytorch.org/blog/)\n* [PyTorch YouTube](https://www.youtube.com/channel/UCWXI5YeOsh03QvJ59PMaXFw)\n\n## Communication\n* Forums: Discuss implementations, research, etc. https://discuss.pytorch.org\n* GitHub Issues: Bug reports, feature requests, install issues, RFCs, thoughts, etc.\n* Slack: The [PyTorch Slack](https://pytorch.slack.com/) hosts a primary audience of moderate to experienced PyTorch users and developers for general chat, online discussions, collaboration, etc. If you are a beginner looking for help, the primary medium is [PyTorch Forums](https://discuss.pytorch.org). If you need a slack invite, please fill this form: https://goo.gl/forms/PP1AGvNHpSaJP8to1\n* Newsletter: No-noise, a one-way email newsletter with important announcements about PyTorch. You can sign-up here: https://eepurl.com/cbG0rv\n* Facebook Page: Important announcements about PyTorch. https://www.facebook.com/pytorch\n* For brand guidelines, please visit our website at [pytorch.org](https://pytorch.org/)\n\n## Releases and Contributing\n\nTypically, PyTorch has three minor releases a year. Please let us know if you encounter a bug by [filing an issue](https://github.com/pytorch/pytorch/issues).\n\nWe appreciate all contributions. If you are planning to contribute back bug-fixes, please do so without any further discussion.\n\nIf you plan to contribute new features, utility functions, or extensions to the core, please first open an issue and discuss the feature with us.\nSending a PR without discussion might end up resulting in a rejected PR because we might be taking the core in a different direction than you might be aware of.\n\nTo learn more about making a contribution to PyTorch, please see our [Contribution page](CONTRIBUTING.md). For more information about PyTorch releases, see [Release page](RELEASE.md).\n\n## The Team\n\nPyTorch is a community-driven project with several skillful engineers and researchers contributing to it.\n\nPyTorch is currently maintained by [Soumith Chintala](http://soumith.ch), [Gregory Chanan](https://github.com/gchanan), [Dmytro Dzhulgakov](https://github.com/dzhulgakov), [Edward Yang](https://github.com/ezyang), [Alban Desmaison](https://github.com/albanD), [Piotr Bialecki](https://github.com/ptrblck) and [Nikita Shulga](https://github.com/malfet) with major contributions coming from hundreds of talented individuals in various forms and means.\nA non-exhaustive but growing list needs to mention: [Trevor Killeen](https://github.com/killeent), [Sasank Chilamkurthy](https://github.com/chsasank), [Sergey Zagoruyko](https://github.com/szagoruyko), [Adam Lerer](https://github.com/adamlerer), [Francisco Massa](https://github.com/fmassa), [Alykhan Tejani](https://github.com/alykhantejani), [Luca Antiga](https://github.com/lantiga), [Alban Desmaison](https://github.com/albanD), [Andreas Koepf](https://github.com/andreaskoepf), [James Bradbury](https://github.com/jekbradbury), [Zeming Lin](https://github.com/ebetica), [Yuandong Tian](https://github.com/yuandong-tian), [Guillaume Lample](https://github.com/glample), [Marat Dukhan](https://github.com/Maratyszcza), [Natalia Gimelshein](https://github.com/ngimel), [Christian Sarofeen](https://github.com/csarofeen), [Martin Raison](https://github.com/martinraison), [Edward Yang](https://github.com/ezyang), [Zachary Devito](https://github.com/zdevito). <!-- codespell:ignore -->\n\nNote: This project is unrelated to [hughperkins/pytorch](https://github.com/hughperkins/pytorch) with the same name. Hugh is a valuable contributor to the Torch community and has helped with many things Torch and PyTorch.\n\n## License\n\nPyTorch has a BSD-style license, as found in the [LICENSE](LICENSE) file.",
"readme_text":"# 🗂️ LlamaIndex 🦙\n\n[](https://pypi.org/project/llama-index/)\n[](https://github.com/run-llama/llama_index/actions/workflows/build_package.yml)\n[](https://github.com/jerryjliu/llama_index/graphs/contributors)\n[](https://discord.gg/dGcwcsnxhU)\n[](https://x.com/llama_index)\n[](https://www.reddit.com/r/LlamaIndex/)\n[](https://www.phorm.ai/query?projectId=c5863b56-6703-4a5d-87b6-7e6031bf16b6)\n\nLlamaIndex OSS (by [LlamaIndex](https://llamaindex.ai?utm_medium=li_github&utm_source=github&utm_campaign=2026--)) is an open-source framework to build agentic applications. **[Parse](https://cloud.llamaindex.ai?utm_medium=li_github&utm_source=github&utm_campaign=2026--)** is our enterprise platform for agentic OCR, parsing, extraction, indexing and more. You can use LlamaParse with this framework or on its own; see [LlamaParse](#llamacloud-document-agent-platform) below for signup and product links.\n\n> ### 📚 **Documentation:**\n>\n> - [LlamaParse](https://developers.llamaindex.ai/python/cloud/llamaparse/?utm_medium=li_github&utm_source=github&utm_campaign=2026--)\n> - [LlamaIndex OSS](https://developers.llamaindex.ai/python/framework/?utm_medium=li_github&utm_source=github&utm_campaign=2026--)\n> - [LlamaAgents](https://developers.llamaindex.ai/python/llamaagents/overview/?utm_medium=li_github&utm_source=github&utm_campaign=2026--)\n\nBuilding with LlamaIndex typically involves working with LlamaIndex core and a chosen set of integrations (or plugins). There are two ways to start building with LlamaIndex in\nPython:\n\n1. **Starter**: [`llama-index`](https://pypi.org/project/llama-index/). A starter Python package that includes core LlamaIndex as well as a selection of integrations.\n\n2. **Customized**: [`llama-index-core`](https://pypi.org/project/llama-index-core/). Install core LlamaIndex and add your chosen LlamaIndex integration packages on [LlamaHub](https://llamahub.ai/)\n that are required for your application. There are over 300 LlamaIndex integration\n packages that work seamlessly with core, allowing you to build with your preferred\n LLM, embedding, and vector store providers.\n\nThe LlamaIndex Python library is namespaced such that import statements which\ninclude `core` imply that the core package is being used. In contrast, those\nstatements without `core` imply that an integration package is being used.\n\n```python\n# typical pattern\nfrom llama_index.core.xxx import ClassABC # core submodule xxx\nfrom llama_index.xxx.yyy import (\n SubclassABC,\n) # integration yyy for submodule xxx\n\n# concrete example\nfrom llama_index.core.llms import LLM\nfrom llama_index.llms.openai import OpenAI\n```\n\n### LlamaParse (document agent platform)\n\n**LlamaParse** is its own platform—focused on document agents and agentic OCR. It includes **Parse** (parsing), **LlamaAgents** (deployed document agents), **Extract** (structured extraction), and **Index** (ingest and RAG). You can use it with the LlamaIndex framework or standalone.\n\n- **[Sign up for LlamaParse](https://cloud.llamaindex.ai?utm_medium=li_github&utm_source=github&utm_campaign=2026--)** — Create an account and get your API key.\n- **Parse** — Agentic OCR and document parsing (130+ formats). [Docs](https://developers.llamaindex.ai/python/cloud/llamaparse/?utm_medium=li_github&utm_source=github&utm_campaign=2026--)\n- **Extract** — Structured data extraction from documents. [Docs](https://developers.llamaindex.ai/python/cloud/llamaextract/?utm_medium=li_github&utm_source=github&utm_campaign=2026--)\n- **Index** — Ingest, index, and RAG pipelines. [Docs](https://developers.llamaindex.ai/python/cloud/llamacloud/?utm_medium=li_github&utm_source=github&utm_campaign=2026--)\n- **Split** — Split large documents into subcategories. [Docs](https://developers.llamaindex.ai/python/cloud/split/getting_started/?utm_medium=li_github&utm_source=github&utm_campaign=2026--)\n- **Agents** — Build end-to-end document agents with `Workflows` and Agent Builder. [Docs](https://developers.llamaindex.ai/python/llamaagents/overview/?utm_medium=li_github&utm_source=github&utm_campaign=2026--)\n\n### Important Links\n\n[Documentation](https://developers.llamaindex.ai/python/framework/?utm_medium=li_github&utm_source=github&utm_campaign=2026--)\n\n[X (formerly Twitter)](https://x.com/llama_index)\n\n[LinkedIn](https://www.linkedin.com/company/llamaindex/)\n\n[Reddit](https://www.reddit.com/r/LlamaIndex/)\n\n[Discord](https://discord.gg/dGcwcsnxhU)\n\n## 🚀 Overview\n\n**NOTE**: This README is not updated as frequently as the documentation. Please check out the documentation above for the latest updates!\n\n### Context\n\n- LLMs are a phenomenal piece of technology for knowledge generation and reasoning. They are pre-trained on large amounts of publicly available data.\n- How do we best augment LLMs with our own private data?\n\nWe need a comprehensive toolkit to help perform this data augmentation for LLMs.\n\n### Proposed Solution\n\nThat's where **LlamaIndex** comes in. LlamaIndex is a \"data framework\" to help you build LLM apps. It provides the following tools:\n\n- Offers **data connectors** to ingest your existing data sources and data formats (APIs, PDFs, docs, SQL, etc.).\n- Provides ways to **structure your data** (indices, graphs) so that this data can be easily used with LLMs.\n- Provides an **advanced retrieval/query interface over your data**: Feed in any LLM input prompt, get back retrieved context and knowledge-augmented output.\n- Allows easy integrations with your outer application framework (e.g. with LangChain, Flask, Docker, ChatGPT, or anything else).\n\nLlamaIndex provides tools for both beginner users and advanced users. Our high-level API allows beginner users to use LlamaIndex to ingest and query their data in\n5 lines of code. Our lower-level APIs allow advanced users to customize and extend any module (data connectors, indices, retrievers, query engines, reranking modules),\nto fit their needs.\n\n## 💡 Contributing\n\nInterested in contributing? Contributions to LlamaIndex core as well as contributing\nintegrations that build on the core are both accepted and highly encouraged! See our [Contribution Guide](CONTRIBUTING.md) for more details.\n\nNew integrations should meaningfully integrate with existing LlamaIndex framework components. At the discretion of LlamaIndex maintainers, some integrations may be declined.\n\n## 📄 Documentation\n\nFull documentation can be found [here](https://developers.llamaindex.ai/python/framework/?utm_medium=li_github&utm_source=github&utm_campaign=2026--)\n\nPlease check it out for the most up-to-date tutorials, how-to guides, references, and other resources!\n\n## 💻 Example Usage\n\n```sh\n# custom selection of integrations to work with core\npip install llama-index-core\npip install llama-index-llms-openai\npip install llama-index-llms-ollama\npip install llama-index-embeddings-huggingface\n```\n\nExamples are in the `docs/examples` folder. Indices are in the `indices` folder (see list of indices below).\n\nTo build a simple vector store index using OpenAI:\n\n```python\nimport os\n\nos.environ[\"OPENAI_API_KEY\"] = \"YOUR_OPENAI_API_KEY\"\n\nfrom llama_index.core import VectorStoreIndex, SimpleDirectoryReader\n\ndocuments = SimpleDirectoryReader(\"YOUR_DATA_DIRECTORY\").load_data()\nindex = VectorStoreIndex.from_documents(documents)\n```\n\nTo build a simple vector store index using non-OpenAI LLMs, e.g. LLMs hosted through Ollama:\n\n```python\nfrom llama_index.core import Settings, VectorStoreIndex, SimpleDirectoryReader\nfrom llama_index.embeddings.huggingface import HuggingFaceEmbedding\nfrom llama_index.llms.ollama import Ollama\nfrom transformers import AutoTokenizer\n\n# set the LLM\nSettings.llm = Ollama(\n model=\"llama-3.1:latest\",\n request_timeout=360.0,\n)\n\n# set tokenizer to match LLM\nSettings.tokenizer = AutoTokenizer.from_pretrained(\n\"meta-llama/Llama-3.1-8B-Instruct\"\n)\n\n# set the embed model\nSettings.embed_model = HuggingFaceEmbedding(\n model_name=\"BAAI/bge-small-en-v1.5\"\n)\n\ndocuments = SimpleDirectoryReader(\"YOUR_DATA_DIRECTORY\").load_data()\nindex = VectorStoreIndex.from_documents(\n documents,\n)\n```\n\nTo query:\n\n```python\nquery_engine = index.as_query_engine()\nquery_engine.query(\"YOUR_QUESTION\")\n```\n\nBy default, data is stored in-memory.\nTo persist to disk (under `./storage`):\n\n```python\nindex.storage_context.persist()\n```\n\nTo reload from disk:\n\n```python\nfrom llama_index.core import StorageContext, load_index_from_storage\n\n# rebuild storage context\nstorage_context = StorageContext.from_defaults(persist_dir=\"./storage\")\n# load index\nindex = load_index_from_storage(storage_context)\n```\n\n## A note on Verification of Build Assets\n\nBy default, `llama-index-core` includes a `_static` folder that contains the nltk and tiktoken cache that is included with the package installation. This ensures that you can easily run `llama-index` in environments with restrictive disk access permissions at runtime.\n\nTo verify that these files are safe and valid, we use the github `attest-build-provenance` action. This action will verify that the files in the `_static` folder are the same as the files in the `llama-index-core/llama_index/core/_static` folder.\n\nTo verify this, you can run the following script (pointing to your installed package):\n\n```bash\n#!/bin/bash\nSTATIC_DIR=\"venv/lib/python3.13/site-packages/llama_index/core/_static\"\nREPO=\"run-llama/llama_index\"\n\nfind \"$STATIC_DIR\" -type f | while read -r file; do\n echo \"Verifying: $file\"\n gh attestation verify \"$file\" -R \"$REPO\" || echo \"Failed to verify: $file\"\ndone\n```\n\n## 📖 Citation\n\nReference to cite if you use LlamaIndex in a paper:\n\n```\n@software{Liu_LlamaIndex_2022,\nauthor = {Liu, Jerry},\ndoi = {10.5281/zenodo.1234},\nmonth = {11},\ntitle = {{LlamaIndex}},\nurl = {https://github.com/jerryjliu/llama_index},\nyear = {2022}\n}\n```",
"readme_text":".. -*- mode: rst -*-\n\n|GitHubActions| |Codecov| |CircleCI| |Nightly wheels| |Ruff| |PythonVersion| |PyPI| |DOI| |Benchmark|\n\n\n.. |GitHubActions| image:: https://github.com/scikit-learn/scikit-learn/actions/workflows/unit-tests.yml/badge.svg?\n :target: https://github.com/scikit-learn/scikit-learn/actions/workflows/unit-tests.yml?query=branch%3Amain\n\n.. |CircleCI| image:: https://circleci.com/gh/scikit-learn/scikit-learn/tree/main.svg?style=shield\n :target: https://circleci.com/gh/scikit-learn/scikit-learn\n\n.. |Codecov| image:: https://codecov.io/gh/scikit-learn/scikit-learn/branch/main/graph/badge.svg?token=Pk8G9gg3y9\n :target: https://codecov.io/gh/scikit-learn/scikit-learn\n\n.. |Nightly wheels| image:: https://github.com/scikit-learn/scikit-learn/actions/workflows/wheels.yml/badge.svg?event=schedule\n :target: https://github.com/scikit-learn/scikit-learn/actions?query=workflow%3A%22Wheel+builder%22+event%3Aschedule\n\n.. |Ruff| image:: https://img.shields.io/badge/code%20style-ruff-000000.svg?\n :target: https://github.com/astral-sh/ruff\n\n.. |PythonVersion| image:: https://img.shields.io/pypi/pyversions/scikit-learn.svg?\n :target: https://pypi.org/project/scikit-learn/\n\n.. |PyPI| image:: https://img.shields.io/pypi/v/scikit-learn\n :target: https://pypi.org/project/scikit-learn\n\n.. |DOI| image:: https://zenodo.org/badge/DOI/10.5281/zenodo.17880109.svg?\n :target: https://zenodo.org/badge/latestdoi/21369/scikit-learn/scikit-learn\n\n.. |Benchmark| image:: https://img.shields.io/badge/Benchmarked%20by-asv-blue\n :target: https://scikit-learn.org/scikit-learn-benchmarks\n\n.. |PythonMinVersion| replace:: 3.11\n.. |NumPyMinVersion| replace:: 1.24.1\n.. |SciPyMinVersion| replace:: 1.10.0\n.. |JoblibMinVersion| replace:: 1.4.0\n.. |NarwhalsMinVersion| replace:: 2.0.1\n.. |ThreadpoolctlMinVersion| replace:: 3.5.0\n.. |MatplotlibMinVersion| replace:: 3.6.1\n.. |Scikit-ImageMinVersion| replace:: 0.22.0\n.. |PandasMinVersion| replace:: 1.5.0\n.. |SeabornMinVersion| replace:: 0.13.0\n.. |PytestMinVersion| replace:: 7.1.2\n.. |PlotlyMinVersion| replace:: 5.22.0\n\n.. image:: https://raw.githubusercontent.com/scikit-learn/scikit-learn/main/doc/logos/scikit-learn-logo.png\n :target: https://scikit-learn.org/\n\n**scikit-learn** is a Python module for machine learning built on top of\nSciPy and is distributed under the 3-Clause BSD license.\n\nThe project was started in 2007 by David Cournapeau as a Google Summer\nof Code project, and since then many volunteers have contributed. See\nthe `About us <https://scikit-learn.org/dev/about.html#authors>`__ page\nfor a list of core contributors.\n\nIt is currently maintained by a team of volunteers.\n\nWebsite: https://scikit-learn.org\n\nInstallation\n------------\n\nDependencies\n~~~~~~~~~~~~\n\nscikit-learn requires:\n\n- Python (>= |PythonMinVersion|)\n- NumPy (>= |NumPyMinVersion|)\n- SciPy (>= |SciPyMinVersion|)\n- Narwhals (>= |NarwhalsMinVersion|)\n- joblib (>= |JoblibMinVersion|)\n- threadpoolctl (>= |ThreadpoolctlMinVersion|)\n\n=======\n\nScikit-learn plotting capabilities (i.e., functions start with ``plot_`` and\nclasses end with ``Display``) require Matplotlib (>= |MatplotlibMinVersion|).\nFor running the examples Matplotlib >= |MatplotlibMinVersion| is required.\nA few examples require scikit-image >= |Scikit-ImageMinVersion|, a few examples\nrequire pandas >= |PandasMinVersion|, some examples require seaborn >=\n|SeabornMinVersion| and Plotly >= |PlotlyMinVersion|.\n\nUser installation\n~~~~~~~~~~~~~~~~~\n\nIf you already have a working installation of NumPy and SciPy,\nthe easiest way to install scikit-learn is using ``pip``::\n\n pip install -U scikit-learn\n\nor ``conda``::\n\n conda install -c conda-forge scikit-learn\n\nThe documentation includes more detailed `installation instructions <https://scikit-learn.org/stable/install.html>`_.\n\n\nChangelog\n---------\n\nSee the `changelog <https://scikit-learn.org/dev/whats_new.html>`__\nfor a history of notable changes to scikit-learn.\n\nDevelopment\n-----------\n\nWe welcome new contributors of all experience levels. The scikit-learn\ncommunity goals are to be helpful, welcoming, and effective. The\n`Development Guide <https://scikit-learn.org/stable/developers/index.html>`_\nhas detailed information about contributing code, documentation, tests, and\nmore. We've included some basic information in this README.\n\nImportant links\n~~~~~~~~~~~~~~~\n\n- Official source code repo: https://github.com/scikit-learn/scikit-learn\n- Download releases: https://pypi.org/project/scikit-learn/\n- Issue tracker: https://github.com/scikit-learn/scikit-learn/issues\n\nSource code\n~~~~~~~~~~~\n\nYou can check the latest sources with the command::\n\n git clone https://github.com/scikit-learn/scikit-learn.git\n\nContributing\n~~~~~~~~~~~~\n\nTo learn more about making a contribution to scikit-learn, please see our\n`Contributing guide\n<https://scikit-learn.org/dev/developers/contributing.html>`_.\n\nTesting\n~~~~~~~\n\nAfter installation, you can launch the test suite from outside the source\ndirectory (you will need to have ``pytest`` >= |PytestMinVersion| installed)::\n\n pytest sklearn\n\nSee the web page https://scikit-learn.org/dev/developers/contributing.html#testing-and-improving-test-coverage\nfor more information.\n\n Random number generation can be controlled during testing by setting\n the ``SKLEARN_SEED`` environment variable.\n\nSubmitting a Pull Request\n~~~~~~~~~~~~~~~~~~~~~~~~~\n\nBefore opening a Pull Request, have a look at the\nfull Contributing page to make sure your code complies\nwith our guidelines: https://scikit-learn.org/stable/developers/index.html\n\nProject History\n---------------\n\nThe project was started in 2007 by David Cournapeau as a Google Summer\nof Code project, and since then many volunteers have contributed. See\nthe `About us <https://scikit-learn.org/dev/about.html#authors>`__ page\nfor a list of core contributors.\n\nThe project is currently maintained by a team of volunteers.\n\n**Note**: `scikit-learn` was previously referred to as `scikits.learn`.\n\nHelp and Support\n----------------\n\nDocumentation\n~~~~~~~~~~~~~\n\n- HTML documentation (stable release): https://scikit-learn.org\n- HTML documentation (development version): https://scikit-learn.org/dev/\n- FAQ: https://scikit-learn.org/stable/faq.html\n\nCommunication\n~~~~~~~~~~~~~\n\nMain Channels\n^^^^^^^^^^^^^\n\n- **Website**: https://scikit-learn.org\n- **Blog**: https://blog.scikit-learn.org\n- **Mailing list**: https://mail.python.org/mailman/listinfo/scikit-learn\n\nDeveloper & Support\n^^^^^^^^^^^^^^^^^^^^^^\n\n- **GitHub Discussions**: https://github.com/scikit-learn/scikit-learn/discussions\n- **Stack Overflow**: https://stackoverflow.com/questions/tagged/scikit-learn\n- **Discord**: https://discord.gg/h9qyrK8Jc8\n\nSocial Media Platforms\n^^^^^^^^^^^^^^^^^^^^^^\n\n- **LinkedIn**: https://www.linkedin.com/company/scikit-learn\n- **YouTube**: https://www.youtube.com/channel/UCJosFjYm0ZYVUARxuOZqnnw/playlists\n- **Facebook**: https://www.facebook.com/scikitlearnofficial/\n- **Instagram**: https://www.instagram.com/scikitlearnofficial/\n- **TikTok**: https://www.tiktok.com/@scikit.learn\n- **Bluesky**: https://bsky.app/profile/scikit-learn.org\n- **Mastodon**: https://mastodon.social/@sklearn@fosstodon.org\n\nResources\n^^^^^^^^^\n\n- **Calendar**: https://blog.scikit-learn.org/calendar/\n- **Logos & Branding**: https://github.com/scikit-learn/scikit-learn/tree/main/doc/logos\n\nCitation\n~~~~~~~~\n\nIf you use scikit-learn in a scientific publication, we would appreciate citations: https://scikit-learn.org/stable/about.html#citing-scikit-learn",
"readme_text":"<br>\n\n<img src=\"https://user-images.githubusercontent.com/7164864/217935870-c0bc60a3-6fc0-4047-b011-7b4c59488c91.png\" alt=\"Streamlit logo\" style=\"margin-top:50px\"></img>\n\n# Welcome to Streamlit 👋\n\n**A faster way to build and share data apps.**\n\n## What is Streamlit?\n\nStreamlit lets you transform Python scripts into interactive web apps in minutes, instead of weeks. Build dashboards, generate reports, or create chat apps. Once you’ve created an app, you can use our [Community Cloud platform](https://streamlit.io/cloud) to deploy, manage, and share your app.\n\n### Why choose Streamlit?\n\n- **Simple and Pythonic:** Write beautiful, easy-to-read code.\n- **Fast, interactive prototyping:** Let others interact with your data and provide feedback quickly.\n- **Live editing:** See your app update instantly as you edit your script.\n- **Open-source and free:** Join a vibrant community and contribute to Streamlit's future.\n\n## Installation\n\nOpen a terminal and run:\n\n```bash\n$ pip install streamlit\n$ streamlit hello\n```\n\nIf this opens our sweet _Streamlit Hello_ app in your browser, you're all set! If not, head over to [our docs](https://docs.streamlit.io/get-started) for specific installs.\n\nThe app features a bunch of examples of what you can do with Streamlit. Jump to the [quickstart](#quickstart) section to understand how that all works.\n\n<img src=\"https://user-images.githubusercontent.com/7164864/217936487-1017784e-68ec-4e0d-a7f6-6b97525ddf88.gif\" alt=\"Streamlit Hello\" width=500 href=\"none\"></img>\n\n## Quickstart\n\n### A little example\n\nCreate a new file named `streamlit_app.py` in your project directory with the following code:\n```python\nimport streamlit as st\nx = st.slider(\"Select a value\")\nst.write(x, \"squared is\", x * x)\n```\n\nNow run it to open the app!\n```\n$ streamlit run streamlit_app.py\n```\n\n<img src=\"https://user-images.githubusercontent.com/7164864/215172915-cf087c56-e7ae-449a-83a4-b5fa0328d954.gif\" width=300 alt=\"Little example\"></img>\n\n### Give me more!\n\nStreamlit comes in with [a ton of additional powerful elements](https://docs.streamlit.io/develop/api-reference) to spice up your data apps and delight your viewers. Some examples:\n\n<table border=\"0\">\n <tr>\n <td>\n <a target=\"_blank\" href=\"https://docs.streamlit.io/develop/api-reference/widgets\">\n <img src=\"https://user-images.githubusercontent.com/7164864/217936099-12c16f8c-7fe4-44b1-889a-1ac9ee6a1b44.png\" style=\"max-height:150px; width:auto; display:block;\">\n </a>\n </td>\n <td>\n <a target=\"_blank\" href=\"https://docs.streamlit.io/develop/api-reference/data/st.dataframe\">\n <img src=\"https://user-images.githubusercontent.com/7164864/215110064-5eb4e294-8f30-4933-9563-0275230e52b5.gif\" style=\"max-height:150px; width:auto; display:block;\">\n </a>\n </td>\n <td>\n <a target=\"_blank\" href=\"https://docs.streamlit.io/develop/api-reference/charts\">\n <img src=\"https://user-images.githubusercontent.com/7164864/215174472-bca8a0d7-cf4b-4268-9c3b-8c03dad50bcd.gif\" style=\"max-height:150px; width:auto; display:block;\">\n </a>\n </td>\n <td>\n <a target=\"_blank\" href=\"https://docs.streamlit.io/develop/api-reference/layout\">\n <img src=\"https://user-images.githubusercontent.com/7164864/217936149-a35c35be-0d96-4c63-8c6a-1c4b52aa8f60.png\" style=\"max-height:150px; width:auto; display:block;\">\n </a>\n </td>\n <td>\n <a target=\"_blank\" href=\"https://docs.streamlit.io/develop/concepts/multipage-apps\">\n <img src=\"https://user-images.githubusercontent.com/7164864/215173883-eae0de69-7c1d-4d78-97d0-3bc1ab865e5b.gif\" style=\"max-height:150px; width:auto; display:block;\">\n </a>\n </td>\n <td>\n <a target=\"_blank\" href=\"https://streamlit.io/gallery\">\n <img src=\"https://user-images.githubusercontent.com/7164864/215109229-6ae9111f-e5c1-4f0b-b3a2-87a79268ccc9.gif\" style=\"max-height:150px; width:auto; display:block;\">\n </a>\n </td>\n </tr>\n <tr>\n <td>Input widgets</td>\n <td>Dataframes</td>\n <td>Charts</td>\n <td>Layout</td>\n <td>Multi-page apps</td>\n <td>Fun</td>\n </tr>\n</table>\n\n\nOur vibrant creators community also extends Streamlit capabilities using 🧩 [Streamlit Components](https://streamlit.io/components).\n\n## Get inspired\n\nThere's so much you can build with Streamlit:\n- 🤖 [LLMs & chatbot apps](https://streamlit.io/gallery?category=llms)\n- 🧬 [Science & technology apps](https://streamlit.io/gallery?category=science-technology)\n- 💬 [NLP & language apps](https://streamlit.io/gallery?category=nlp-language)\n- 🏦 [Finance & business apps](https://streamlit.io/gallery?category=finance-business)\n- 🗺 [Geography & society apps](https://streamlit.io/gallery?category=geography-society)\n- and more!\n\n**Check out [our gallery!](https://streamlit.io/gallery)** 🎈\n\n## Community Cloud\n\nDeploy, manage and share your apps for free using our [Community Cloud](https://streamlit.io/cloud)! Sign-up [here](https://share.streamlit.io/signup). <br><br>\n<img src=\"https://user-images.githubusercontent.com/7164864/214965336-64500db3-0d79-4a20-8052-2dda883902d2.gif\" width=\"400\"></img>\n\n## Resources\n\n- Explore our [docs](https://docs.streamlit.io) to learn how Streamlit works.\n- Ask questions and get help in our [community forum](https://discuss.streamlit.io).\n- Read our [blog](https://blog.streamlit.io) for tips from developers and creators.\n- Extend Streamlit's capabilities by installing or creating your own [Streamlit Components](https://streamlit.io/components).\n- Help others find and play with your app by using the Streamlit GitHub badge in your repository:\n```markdown\n[](URL_TO_YOUR_APP)\n```\n[](https://share.streamlit.io/streamlit/roadmap)\n\n## Contribute\n\n🎉 Thanks for your interest in helping improve Streamlit! 🎉\n\nBefore contributing, please read our guidelines here: https://github.com/streamlit/streamlit/blob/develop/CONTRIBUTING.md\n\n## License\n\nStreamlit is completely free and open-source and licensed under the [Apache 2.0](https://www.apache.org/licenses/LICENSE-2.0) license.",
"readme_text":"<!-- markdownlint-disable MD001 MD041 -->\n<p align=\"center\">\n <picture>\n <source media=\"(prefers-color-scheme: dark)\" srcset=\"https://raw.githubusercontent.com/vllm-project/vllm/main/docs/assets/logos/vllm-logo-text-dark.png\">\n <img alt=\"vLLM\" src=\"https://raw.githubusercontent.com/vllm-project/vllm/main/docs/assets/logos/vllm-logo-text-light.png\" width=55%>\n </picture>\n</p>\n\n<h3 align=\"center\">\nEasy, fast, and cheap LLM serving for everyone\n</h3>\n\n<p align=\"center\">\n| <a href=\"https://docs.vllm.ai\"><b>Documentation</b></a> | <a href=\"https://blog.vllm.ai/\"><b>Blog</b></a> | <a href=\"https://arxiv.org/abs/2309.06180\"><b>Paper</b></a> | <a href=\"https://x.com/vllm_project\"><b>Twitter/X</b></a> | <a href=\"https://discuss.vllm.ai\"><b>User Forum</b></a> | <a href=\"https://slack.vllm.ai\"><b>Developer Slack</b></a> |\n</p>\n\n🔥 We have built a vLLM website to help you get started with vLLM. Please visit [vllm.ai](https://vllm.ai) to learn more.\nFor events, please visit [vllm.ai/events](https://vllm.ai/events) to join us.\n\n---\n\n## About\n\nvLLM is a fast and easy-to-use library for LLM inference and serving.\n\nOriginally developed in the [Sky Computing Lab](https://sky.cs.berkeley.edu) at UC Berkeley, vLLM has grown into one of the most active open-source AI projects built and maintained by a diverse community of many dozens of academic institutions and companies from over 2000 contributors.\n\nvLLM is fast with:\n\n- State-of-the-art serving throughput\n- Efficient management of attention key and value memory with [**PagedAttention**](https://blog.vllm.ai/2023/06/20/vllm.html)\n- Continuous batching of incoming requests, chunked prefill, prefix caching\n- Fast and flexible model execution with piecewise and full CUDA/HIP graphs\n- Quantization: FP8, MXFP8/MXFP4, NVFP4, INT8, INT4, GPTQ/AWQ, GGUF, compressed-tensors, ModelOpt, TorchAO, and [more](https://docs.vllm.ai/en/latest/features/quantization/index.html)\n- Optimized attention kernels including FlashAttention, FlashInfer, TRTLLM-GEN, FlashMLA, and Triton\n- Optimized GEMM/MoE kernels for various precisions using CUTLASS, TRTLLM-GEN, CuTeDSL\n- Speculative decoding including n-gram, suffix, EAGLE, DFlash\n- Automatic kernel generation and graph-level transformations using torch.compile\n- Disaggregated prefill, decode, and encode\n\nvLLM is flexible and easy to use with:\n\n- Seamless integration with popular Hugging Face models\n- High-throughput serving with various decoding algorithms, including *parallel sampling*, *beam search*, and more\n- Tensor, pipeline, data, expert, and context parallelism for distributed inference\n- Streaming outputs\n- Generation of structured outputs using xgrammar or guidance\n- Tool calling and reasoning parsers\n- OpenAI-compatible API server, plus Anthropic Messages API and gRPC support\n- Efficient multi-LoRA support for dense and MoE layers\n- Support for NVIDIA GPUs, AMD GPUs, and x86/ARM/PowerPC CPUs. Additionally, diverse hardware plugins such as Google TPUs, Intel Gaudi, IBM Spyre, Huawei Ascend, Rebellions NPU, Apple Silicon, MetaX GPU, and more.\n\nvLLM seamlessly supports 200+ model architectures on Hugging Face, including:\n\n- Decoder-only LLMs (e.g., Llama, Qwen, Gemma)\n- Mixture-of-Expert LLMs (e.g., Mixtral, DeepSeek-V3, Qwen-MoE, GPT-OSS)\n- Hybrid attention and state-space models (e.g., Mamba, Qwen3.5)\n- Multi-modal models (e.g., LLaVA, Qwen-VL, Pixtral)\n- Embedding and retrieval models (e.g., E5-Mistral, GTE, ColBERT)\n- Reward and classification models (e.g., Qwen-Math)\n\nFind the full list of supported models [here](https://docs.vllm.ai/en/latest/models/supported_models.html).\n\n## Getting Started\n\nInstall vLLM with [`uv`](https://docs.astral.sh/uv/) (recommended) or `pip`:\n\n```bash\nuv pip install vllm\n```\n\nOr [build from source](https://docs.vllm.ai/en/latest/getting_started/installation/gpu/index.html#build-wheel-from-source) for development.\n\nVisit our [documentation](https://docs.vllm.ai/en/latest/) to learn more.\n\n- [Installation](https://docs.vllm.ai/en/latest/getting_started/installation.html)\n- [Quickstart](https://docs.vllm.ai/en/latest/getting_started/quickstart.html)\n- [List of Supported Models](https://docs.vllm.ai/en/latest/models/supported_models.html)\n\n## Contributing\n\nWe welcome and value any contributions and collaborations.\nPlease check out [Contributing to vLLM](https://docs.vllm.ai/en/latest/contributing/index.html) for how to get involved.\n\n## Citation\n\nIf you use vLLM for your research, please cite our [paper](https://arxiv.org/abs/2309.06180):\n\n```bibtex\n@inproceedings{kwon2023efficient,\n title={Efficient Memory Management for Large Language Model Serving with PagedAttention},\n author={Woosuk Kwon and Zhuohan Li and Siyuan Zhuang and Ying Sheng and Lianmin Zheng and Cody Hao Yu and Joseph E. Gonzalez and Hao Zhang and Ion Stoica},\n booktitle={Proceedings of the ACM SIGOPS 29th Symposium on Operating Systems Principles},\n year={2023}\n}\n```\n\n## Contact Us\n\n<!-- --8<-- [start:contact-us] -->\n- For technical questions and feature requests, please use GitHub [Issues](https://github.com/vllm-project/vllm/issues)\n- For discussing with fellow users, please use the [vLLM Forum](https://discuss.vllm.ai)\n- For coordinating contributions and development, please use [Slack](https://slack.vllm.ai)\n- For security disclosures, please use GitHub's [Security Advisories](https://github.com/vllm-project/vllm/security/advisories) feature\n- For collaborations and partnerships, please contact us at [collaboration@vllm.ai](mailto:collaboration@vllm.ai)\n<!-- --8<-- [end:contact-us] -->\n\n## Media Kit\n\n- If you wish to use vLLM's logo, please refer to [our media kit repo](https://github.com/vllm-project/media-kit)",
